Complete content from the Synervoz website.
# Blog
> Get technical insights on Voice AI, real-time audio systems, social voice, and the Switchboard SDK. Explore the future of audio engineering here.
Looking for technical content? Explore the [Switchboard Engineering Hub](https://switchboard.audio/hub/)
##### FEATURED
The biggest challenge in AI audio isn't training the model. It's deployment under real-world constraints, where latency, power, and usability collide. It's a gap the industry is only beginning to notice.
Switchboard gives developers **modular building blocks** (think: LEGO for audio) to create innovative real-time experiences that can combine music, voice, AI, effects, and more—without reinventing the wheel.
Voice interfaces have rapidly evolved in 2025, moving from novelty to necessity across consumer and enterprise applications. This post explores the technological breakthroughs, UX challenges, and shifting user expectations shaping this transformation.
##### LATEST
We built an iOS travel assistant that works fully offline, with speech recognition, the language model, and voice all running on the phone. When a connection is available, it can hand the thinking off to a cloud model.
Stripe’s OpenRouter deal signals a broader shift in AI infrastructure: token optimization is moving beyond choosing the right cloud model toward deciding whether a request should go to the cloud at all.
While the AI conversation focuses on models and cloud compute, a parallel shift is underway: AI inference is moving onto the devices we already own, reducing the need to send every task to the cloud.
Discover how Voice AI can enhance a broader range of mobile apps, and how hybrid on-device + cloud AI make natural voice interactions easier to build.
A decade-long quest for the perfect motorcycle audio experience reveals how AirPods Pro 3, AI, and smarter integration are transforming riding—and what's still missing.
AI progress is shifting from model capability to economic viability. Discover why the real challenge isn’t intelligence, but building affordable, continuous architectures that scale beyond the demo.
While most apps run fine on modern languages, real-time audio and AI demand the precision of C++. Learn why continuous, multi-stream systems require low-level control to prevent glitches and lag.
Edge AI is becoming the default, reducing latency, cost, and privacy risks. For voice systems, edge-first architectures deliver faster, more reliable experiences than cloud-only approaches.
Every business wants customer service to feel like a personal concierge. Few are set up to actually deliver one.
As AI demand outpaces memory supply, cloud apps grow costlier and less reliable. On-device AI keeps core features running when remote infrastructure falters.
Most conversations about Voice AI focus on the future of **Human–Machine** Interaction. The real impact of Voice AI will be how machines quietly reshape **how we talk ****to each other**.
Audio AI powers modern voice experiences, but turning breakthroughs into products is hard. Behind “speech in, speech out” lies a gap between research and real-time engineering.
Cloud-based audio AI brought us speech recognition, conversational AI agents, and more. But as usage grows beyond proofs of concept, the weaknesses of the cloud have become glaring.
Shared experiences online often fail because timing doesn’t align. AI agents will bridge that gap, detecting availability and using voice to spark spontaneous, real-time connection.
AI Codegen is no longer experimental. The teams that adopt disciplined workflows around it are already pulling ahead, while everyone else is falling behind.
One of the most fascinating applications of AI is **humanoid robots**. As audio specialists, we're particularly interested in the **audio systems onboard**, and these systems are evolving rapidly. **Figure AI’s Helix model** represents a shift in both humanoid robot capabilities and how audio is handled.
The **real frontier for AI** is no longer the models themselves but the systems that integrate them. It’s on the inference side. The **opportunity lies in the hands of those who can design, build, and deploy systems, applications, and novel use cases** that unlock the true potential of these models.
AI is reshaping the tech hiring landscape, but the Roy Lee story shows that the real failure often lies with interviewers who stop asking questions too soon. This piece argues that while AI can support better interviews, it’s human curiosity and conversation that reveal whether a candidate can actually do the job.
While **"vibe coding"** can be practical for prototyping and creative exploration, **it can be disastrous when building complex, real time systems**—particularly in fields like audio processing, where precision, performance, and reliability are paramount.
Tools like **SyncStage** and **Meloscene** solve **latency** issues, enabling real-time remote music and audio creation. They’re redefining collaboration, making virtual studios as effective as in-person sessions.
Telcos can use **AI and device data** to offer “Presence as a Service,” providing real-time status updates like availability or activity. With robust privacy controls, this service could revolutionize communication, helping telcos compete with big tech by enhancing connection and convenience.
**AI-powered voice assistants** can replace companion apps, solving app fatigue by enabling natural, spoken commands for hardware. This shift lets manufacturers focus on **voice integration** over app interfaces, delivering intuitive, hands-free control for users.
Platforms like **Cartesia** and **ElevenLabs** transform **Text-to-Speech** with lifelike voices. Integrated with **Switchboard**, TTS powers dynamic audio for **gaming**, **accessibility**, and more.
**Acoustic anomaly detection (AAD)** uses AI and microphones to monitor machinery sounds and detect issues early. It’s transforming **manufacturing, pipelines**, and **wind farms** with **non-invasive, cost-efficient, real-time alerts**, enabling proactive maintenance and reducing downtime.
AI now solves early challenges like **noise**, **privacy**, and **user fatigue**, making always-on connections seamless and intuitive. **Switchboard 1.0’s vision** is closer than ever to becoming effortless, natural communication.
Deskless workers need smarter tools. Innovations like **Zinc** and **Switchboard** enable **AI-powered, hands-free communication** with noise suppression and task integration. **Always-on connectivity** ensures safety and efficiency, transforming how these workers stay connected.
Combine music and conversation during workouts with **Switchboard**. Whether cycling at home, running outdoors, or hiking with friends, share playlists and talk seamlessly through your headphones.
Meta’s **AR glasses** and **AI-powered tools** are paving the way for the metaverse. **Wearables** and **spatial audio** will transform digital interaction, blending virtual and real-world experiences seamlessly.
AI-driven tools analyze sounds like **coughs**, **heartbeats**, and **baby cries** to diagnose illnesses non-invasively. These technologies are transforming healthcare with accessible, privacy-conscious solutions.
As cars go autonomous, interiors are becoming **entertainment hubs** with advanced **infotainment systems** like Tesla’s PS5-level setups. Companies like Synervoz are driving this shift with real-time audio solutions tailored for dynamic, multi-sensory travel.
Wearables like **Meta Glasses**, Bose AR, and Jony Ive’s Humane Pin highlight **audio’s central role** in AR innovation. With **AI-driven voice interaction**, these devices will redefine communication.
Slack could evolve with **interactive channels**, **spatial audio**, and **virtual rooms** to bridge the remote-work gap. Insights from **Switchboard 1.0** show these features can make teams feel truly connected.
A podcast app with real-time voice mixing would let friends chat over shared audio seamlessly. With **Switchboard SDK**, developers can build tailored experiences faster than ever.
In-game voice chat needs tools like **Vivox** for communication and **WWise** for sound design, but integration can be tricky. Solving issues like **noise and performance** is key to immersive gaming.
As tech advances, integrating mesh networking, voice assistants, and selective transparency features will be key for safer, seamless communication on the road.
With advances in open collaboration and consolidation across devices, the future of watch parties looks promising, enabling more immersive and accessible shared media experiences.
This article explores the technology driving high-quality listen parties, from precise music synchronization and collaborative playlists to smart audio mixing.
AI personas are set to transform social voice and video calls, acting as digital companions who can joke, settle disputes, and help plan events.
Discover how AI agents are transforming B2B customer service and virtual collaboration.
AI leadership isn’t won by dominating benchmarks—it’s won by shaping user behavior.
In a world where we talk to our devices instead of type into them, flexible audio graphs are becoming increasingly important.
Announcing our Fusion business, which leverages the power of AI Agents by customizing them and connecting them with business processes.
AI Agents are a rapidly evolving opportunity, but solutions are not one size fits all. A flexible audio graph provides business flexibility.
Audio developers, you don’t have to build your own SDK. Switchboard is your SDK.
Switchboard is the Unity / Unreal of audio engine development.
In robotics, audio processing plays an important role in enabling machines to interact with their environment in more human-like ways.
Jim Rand, CEO of Synervoz, sits down with coLAB to talk about our history and marketing.
Audio programming mistakes can produce very interesting sounds. In this talk we are going to look at these mistakes and even listen to them.
Amazon’s Interactive Video Service (IVS) is a managed live streaming service for live streaming video and audio at scale. But what if you want to do more with that audio on a device...
In this video tutorial, Synervoz VP of Engineering Balazs Kiss shows viewers step-by-step instructions for how to build a simple guitar-effect app for iOS using the Switchboard SDK.
In a recent presentation at ADCx, Kieran Coulter, Senior Engineer and Lead Architect at Synervoz, delves into neural audio digital signal processing (DSP)...
In recent years, the digital landscape has witnessed a remarkable surge in social audio apps, revolutionizing the way people connect and communicate...
In recent years, the fields of artificial intelligence (AI) and machine learning (ML) have made significant strides in revolutionizing various industries, and the domain of audio is no exception...
In today's digital era, voice and video chat have become indispensable tools for communication, collaboration, and entertainment...
Audio software engineering is an intricate field that combines technical expertise, creative problem-solving, and a passion for delivering exceptional auditory experiences...
[Get In Touch](/contact)
---
# Acoustic Anomaly Detection: The Future of Industrial Monitoring
> Explore how AI-driven acoustic anomaly detection and real-time audio processing are transforming industrial monitoring. Learn how to integrate intelligent sound pattern recognition, predictive maintenance, and low-latency audio solutions into your applications. Dive into the future of AI in acoustic monitoring and start building smarter systems today!
### **How Acoustic Anomaly Detection Works**
Acoustic anomaly detection involves using **microphones and AI algorithms** to monitor the sounds produced by machinery or structures. When machines operate normally, they produce consistent sound patterns. Any deviation—such as grinding, rattling, or hissing—could signal a malfunction. The AI model detects these anomalies by comparing real-time audio data against typical sound profiles. This approach makes it possible to detect subtle irregularities that might go unnoticed by human operators.
### **Use Cases of Acoustic Anomaly Detection in Industry**
1. **Manufacturing Plants**In manufacturing, even a small malfunction can lead to production delays. Acoustic anomaly detection can monitor equipment like **conveyor belts, compressors, and pumps**, identifying issues such as overheating or lubrication problems. When an anomaly is detected, alerts can be sent to technicians, enabling rapid response to potential problems before they escalate. This predictive maintenance approach reduces the need for costly repairs and minimizes downtime.
2. **Monitoring Remote Equipment and Pipelines**For companies managing remote infrastructure—such as pipelines and transmission lines—AAD offers a way to monitor assets from a distance. For instance, **oil and gas companies** can install acoustic sensors along pipelines to detect leaks or pressure changes. Changes in the acoustic signature may indicate a rupture or obstruction, prompting further investigation. This capability is especially valuable in isolated areas, where issues might otherwise go undetected for long periods.
3. **Wind Turbines and Renewable Energy**Wind farms and other renewable energy sources rely on continuous operation. By monitoring the acoustic signatures of **wind turbine blades and gears**, AAD can detect mechanical wear or misalignment early. For solar farms, AAD can detect changes in transformer sounds, indicating electrical issues. Proactive maintenance keeps these systems running efficiently and extends their lifespan.
4. **Railway Infrastructure**Acoustic sensors can be installed on **railway tracks** to monitor the structural health of the rails and detect issues like loose bolts or misalignments. By listening for irregularities in the sound produced by passing trains, AAD can signal maintenance teams to intervene before problems become critical, enhancing the safety and reliability of rail networks.
### **Why Acoustic Anomaly Detection is a Game Changer**
Acoustic anomaly detection systems offer several advantages:
* **Non-Invasive Monitoring**: AAD doesn’t require physical sensors to be attached to equipment, making it an ideal choice for fragile or hard-to-reach components.
* **Cost Efficiency**: Always-on microphones are relatively low-cost, and they can cover large areas, reducing the need for frequent inspections and lowering maintenance costs.
* **Real-Time Alerts**: By continuously monitoring sounds, AAD provides immediate alerts, allowing teams to respond quickly to potential issues.
### **The Future of Acoustic Monitoring**
With advances in **AI and machine learning**, acoustic anomaly detection is becoming more accurate, making it suitable for increasingly complex environments. As industries prioritize efficiency and predictive maintenance, AAD will likely become a standard tool for infrastructure monitoring. By integrating this technology, industries can ensure smoother operations, reduce risks, and save on long-term maintenance costs, marking a significant step forward in industrial management.
[Get In touch](/contact)
---
# Agentic Reasoning: Announcing Fusion
> Focused on software for interactive voice and video chat projects with complex audio requirements.
### **Agentic Reasoning: Announcing Fusion**
Sequoia recently wrote an article “[*Generative AI’s Act 01: The Reasoning Era*](https://www.sequoiacap.com/article/generative-ais-act-o1/)” discussing the shift in AI from mere pattern recognition to **agentic reasoning**, where AI models begin to simulate higher-order reasoning like humans. This transition is critical for creating more useful AI solutions that think deliberately and solve complex, real-world problems.
At **Synervoz**, we’re thrilled to announce **Fusion**, a new business that builds on this next wave of AI. **Fusion** specializes in creating tailored AI solutions, connecting models to real-world APIs and services—an area where our team excels.
With **Switchboard**, our flexible audio SDK, and now **Fusion**, we empower developers to create advanced AI applications that go beyond simple use cases. No matter the use case, Switchboard and Fusion make it easy to integrate AI-driven audio systems with external services. This capability is essential for making AI truly useful in practice, as it needs to be connected to various APIs and platforms to deliver actionable results.
By leveraging our deep experience in integrating external services and APIs with AI models, **Fusion** is positioned to help businesses build smarter, more connected systems. We see this as the key to unlocking the full potential of AI agents in industries like media, entertainment, and beyond.
Visit **Fusion** at [*fusion.synervoz.com*](https://fusion.synervoz.com) to explore how we can help you harness the power of AI-driven audio and agentic reasoning for your business.
[Get In touch](/contact)
---
# AI Agents in the B2B World: Enhancing Customer Service and Social Experiences
> Focused on software for interactive voice and video chat projects with complex audio requirements.
### **AI Agents in Customer Service: From Support to Personalization**
In many sectors, such as **banking, e-commerce, and telecommunications**, AI agents have already established their presence. Customer service bots can assist customers through chat and phone calls, offering instant help with common queries. However, **instead of merely replacing human agents**, these AI agents are also being designed to work *alongside* people in new contexts. They streamline workflows, reducing wait times and improving customer experiences by handling repetitive tasks.
While some customers might speak only with an AI agent throughout an entire interaction, others will encounter **hybrid models**—AI agents seamlessly handing off to human representatives for more complex inquiries. This approach keeps services running efficiently without sacrificing the empathy that humans bring to customer support.
### **AI as Friends on the Call: A New Dimension for Social and Professional Use Cases**
The transformative use of AI goes beyond customer service. Imagine participating in a **watch party, virtual event, or a collaborative team meeting**, where an AI agent is embedded as another participant. This agent might **suggest content, manage scheduling, or offer useful insights** during the call in real-time. The shift here isn’t about replacing a human friend but creating a **new form of digital interaction**—AI agents joining conversations to assist, entertain, or facilitate smoother collaboration.
**Banking and financial services** are also exploring this dual role of AI. AI agents could join video consultations with clients, offering financial advice and data analysis on the spot while still allowing for human advisors to provide personalized recommendations. Similarly, **AI-driven assistants** in customer support can monitor calls and jump in with relevant suggestions.
### **Building Seamless AI-Enhanced Experiences with Switchboard SDK**
Platforms like **Switchboard SDK** from Synervoz make it easy to design and deploy these complex interactions. Switchboard enables developers to create **audio and video pipelines**, making the integration of AI companions into real-time communication smoother. Whether embedding AI into **customer service systems or enabling watch parties**, Switchboard simplifies the development of features like **spatial audio** and **dynamic interactions**—key elements for enriching user experiences.
**AI’s ability to act as a friend on calls opens new doors**, allowing customers to enjoy seamless virtual experiences with both humans and digital agents. It’s not about choosing between AI and human interaction—it’s about using AI to **enhance collaborative experiences** in ways that were previously unimaginable. With the flexibility of tools like Switchboard SDK, businesses can quickly adapt to evolving needs, offering both **human and AI-driven engagement** tailored to their customers' preferences.
### **Conclusion: AI Agents—Partners, Not Replacements**
As AI continues to mature, its role in customer service and social interaction will grow. While AI can take over routine tasks, **it thrives best when used as an enhancement rather than a replacement**. From **customer service scenarios to watch parties**, these agents offer new ways to connect, engage, and collaborate. With platforms like Switchboard, companies can **develop these experiences faster**, making AI not just a tool but a partner in shaping the future of communication.
[Get In touch](/contact)
---
# AI Codegen Is Already Reshaping Software Development
> AI Codegen is no longer experimental. The teams that adopt disciplined workflows around it are already pulling ahead, while everyone else is falling behind.

A review of [O'Reilly's AI Codecon](https://www.oreilly.com/CodingwithAI/)
[*AI CodeCon*](https://www.oreilly.com/CodingwithAI/) made one thing clear: AI-assisted code generation is not a novelty. It's already reshaping how software is built. Teams that understand this shift will outperform those that don't. Others will fall behind.
Tim O'Reilly opened the event with a sharp comparison. He called this moment similar to the birth of the internet. The pattern is familiar. The web changed how people built, communicated, and collaborated. AI is doing the same. The gains in productivity are undeniable. But they are uneven. Most tools get you 70 percent of the way. The remaining 30 percent reveals the limits. This is now called the "70% problem."
Tools like Bolt, V0, and Loveable help close that gap. They provide structure, speed, and focus. But human judgment is still required. The final 30 percent always matters more than people think.
AI handles accidental complexity well. It stumbles on essential complexity. This is where senior developers show their value. They understand maintainability, long-term thinking, and code quality. And now, non-engineers are also generating code. PMs, EMs, sometimes even designers. The result? Quality control becomes critical. Sloppy AI output creates debt faster than humans can repay it.
Bad code is easy to produce. Humans write it. AI writes it too. What separates robust systems from fragile ones is process. Good software comes from critical review, systematic testing, and rigorous refactoring. The tools, whether human or machine, only get you so far. What matters is the process behind the result. Consistent, deliberate effort builds good systems. Discipline makes the difference.
The term "vibe coding" came up often. Usually with a wince. Some used it with visible discomfort. Others offered caveats. Harper Reed said plainly, "I call it AI codegen, because that's what it is." Still, the term captures something important. This is a new mode of working. Fast. Iterative. Loosely structured. Kent Beck (who changed my life as a developer once before when he introduced me to test-driven development), was first to say what many of the presenters said, that AI has brought back the joy of coding for them. The model generates. The developer shapes. The loop continues, almost adictively.
Harper Reed delivered the most practical walkthrough of the event. His codegen workflow with LLMs is detailed, battle-tested, and real. It's not about chatbots and copy-paste. It's about rigorous scaffolding. Tight loops. Systematic review. [*His blog post*](https://harper.blog/2025/02/16/my-llm-codegen-workflow-atm/) documents it well. Seeing it live showed how deliberate every step is. Reed emphasized that Git is "save games for code." Used well, if something goes wrong, you can always reload. I love that framing.
There was disagreement about what this means for junior developers. Some say AI eliminates the grunt work that helped people learn. Others argue it accelerates growth. Both are possible. Either way, ignoring this shift isn't an option. It is already happening.
The event wasn't about glossy slides or overhyped roadmaps. It focused on real usage. People shared bugs. Failures. Dead ends. They also shared wins. This is what it looks like to build with AI. It's not clean. But it is powerful.
I am far less inclined now to believe this is a trend. It's a foundational change in how software is written. Teams that learn to work with AI deliberately and critically will move faster and build better. Everyone else will struggle to keep up.
---
# AI’s Role in Real-Time Audio Systems
> The biggest challenge in AI audio isn't training the model. It's deployment under real-world constraints, where latency, power, and usability collide. It's a gap the industry is only beginning to notice.

When people think about **AI in audio**, they tend to think in terms of models: speech-to-text (STT), text-to-speech (TTS), voice changers, noise suppression, speaker diarization, etc. Startups, investors, and the media following them tends to focus on what’s possible with a particular class of real time audio model. That’s especially true of voice to voice models and text to speech companies that are increasingly focusing on real time voice agent use cases. And to be clear, the advancements in these models are both impressive and game-changing in terms of the new use cases that are now possible.
But the real challenge begins *after* training.
If you want to build a **real-time, AI-powered audio application**, you’ll quickly find that training the model is just one small part of a sprawling, deeply technical stack. A huge amount of work lies in deploying these models **in real-world conditions**—especially when trying to support **low-latency, low-power, on-device inference**.
This is what much of the industry doesn’t even recognize yet, as well as where many product teams stumble to bridge the gap between a model and a usable product. This is our focus at Synervoz. And it’s also why we built the **Switchboard SDK**.
## **Real-Time Audio AI Is More Than Just Models**
### **1. The Myth of "Just Plug In a Model"**
Many product teams assume they can easily plug models into an app. And to some extent that’s true. The model companies generally have APIs available and you can get a prototype up and running with few lines of code. But in production you’ll quickly run into constraints that force an on device audio graph to be built. Things like:
* Getting access to the microphone
* An on-device **voice activity detector (VAD)** to decide when to run the model and avoid sending and receiving endless amounts of data to the cloud unnecessarily while incurring extremely high costs and draining the battery.
* Chunking audio into **batches that align with model input expectations**.
* Adding **buffering and jitter management** to ensure you're not getting dropouts or overlap.
* You often need **preprocessing filters** like automatic gain control, high-pass filters, or denoising before feeding the model.
* You may need to **resample or convert formats** between parts of the pipeline
All of this happens in **real time**.
### **2. System Integration Is the Hidden Beast**
Models run inside ecosystems. In real-time audio, that ecosystem has very tight constraints:
* **Latency:** Anything over \~150ms and you break the illusion of real-time.
* **Power:** On-device inference drains battery fast, especially on mobile or wearables.
* **Memory:** Devices like earbuds or edge gateways don’t have room for large models.
* **Hardware quirks:** You may be deploying across ARM64, x86, Android, iOS, or embedded Linux, each with their own constraints and opportunities to optimise.
* **Concurrency:** Models must run alongside audio playback, network streaming, UI rendering, and other real-time services.
This means you must:
* Optimize for **specific hardware acceleration (like Apple Neural Engine or Qualcomm DSPs)**.
* Strip down models or distill them to smaller, faster versions.
* Build scheduling logic to **avoid CPU/GPU contention** in multi-tenant systems.
* Ensure **audio pipeline synchronization**, which is often harder than it sounds.
## **The model is just an engine**
To power AI use cases like **live translation**, **voice avatars**, **real-time captioning**, or **noise suppression**, you need a robust, adaptable pipeline that wraps around the model like scaffolding:
#### **A car analogy might help:**
* The model is the engine.
* The audio pipeline is the **entire drive train**: from the crankshaft through the transmission and tires.
* If any part fails, the whole thing breaks down.
* And you can’t just drop an engine into any chassis. The whole design needs to fit together.
* An assembly line is the only way you can put this together fast, and at scale.
#### **The Audio Pipeline Responsibilities:**
* **Capture**: Mic input with minimal delay, echo-cancelled, gain-controlled.
* **Buffer**: Manage frames, timestamps, jitter correction.
* **Process**: Feed the right frames to the right models at the right time.
* **Route**: Send outputs to playback, network, logs, transcripts, analytics, or other agents.
* **Sync**: Maintain tight coordination with other streams (e.g. media playback in a watch party or robot perception in multimodal systems).
## **Where Switchboard SDK Comes In**
Most teams aren’t set up to solve these problems well. They:
* Waste months building glue code for pipelines.
* Struggle to switch platforms (e.g. from iOS to Android or Web) and end up hiring experts to rebuild for each.
* Can’t run multiple models together (like STT + Voice Cloning + Noise Cancellation).
* End up building monoliths with no modularity, flexibility to make changes, or reuse components.
**Switchboard solves this.**
### **What Switchboard Does:**
* Provides a **modular, real-time audio graph engine**. Similar to modular DSP systems, but it’s real time, and with all the nodes you need for Voice AI and other real time audio pipelines.
* Comes with built-in **nodes** for audio capture, playback, VAD, STT, TTS, media players, custom DSPs, etc.
* Supports **hybrid graphs**—run some nodes locally, others in the cloud.
* Has first-class support for **on-device inference**, **multi-platform SDKs (Swift, Kotlin, JS)**, and **BYO model integration**.
* Handles **cross-thread timing**, **buffering**, and **low-latency audio IO**.
* Allows devs to rapidly **compose new use cases** like voice agents, real time podcast generation with co-listening, or real-time audio effects chains for your social app or game.
## **The Future: Smarter Pipelines, Not Just Smarter Models**
As AI models become more commoditized, **differentiation will come from system integration**:
* Who can run them faster, with lower latency?
* Who can run multiple models in parallel?
* Who can run them *on device*, not just in the cloud?
* Who can adapt them to quirky edge conditions like dropped frames, language switches, or Bluetooth handovers?
**That’s where the real innovation is happening now.**
There’s where we live, and that’s what **Switchboard enables you to do**. Switchboard ushers in a future where building a real-time voice app with multiple AI models running in parallel is as easy as spinning up a web app. Where **latency-aware pipelines** and **hardware-aware inference** are no longer science projects, but developer tools.
AI is transforming real-time audio—but only for teams that embrace the full stack. The future isn't just about training better models. It’s about **shipping better systems**.
With **Switchboard**, developers can stop worrying about plumbing and focus on building magical, real-time audio experiences.
---
# Always-On Communication: How Smarter AI Makes It Possible
> Discover how AI-driven noise suppression, sound recognition algorithms, and adaptive streaming are enabling always-on communication. Learn how to integrate background noise filtering, voice activity detection, and audio ducking into your applications with deep learning and open-source tools. Build smarter, more seamless audio experiences today!
### **The Initial Challenges of Always-On Communication**
Switchboard 1.0 enabled continuous connection by maintaining an open line between participants, ideal for spontaneous conversations and ongoing collaboration. However, the technology at the time had limitations:
* **Privacy Concerns**: Keeping an open audio line raised questions about privacy, and the model required careful user control to prevent interruptions at inappropriate moments.
* **Noise Management**: Without advanced noise suppression, background sounds could disrupt the experience, especially in busy environments.
* **User Fatigue**: Constant connection sometimes led to “communication fatigue,” as users felt always “on,” even when not actively engaged.
### **How Smarter AI Enhances Always-On Communication**
With recent advancements in **AI and machine learning**, many of these challenges are now manageable, creating a path for smarter and more user-friendly always-on communication.
1. **Context-Aware AI**Smarter AI models can recognize context and understand when users are busy, available, or idle. By analyzing subtle cues—such as typing sounds, voice tone, or even environmental noise—AI can **automatically adjust the communication status**, turning the line “on” or “off” based on a user’s activity and preferences. This allows people to stay connected without the pressure of constant availability, giving them the flexibility to communicate naturally.
2. **Enhanced Noise Suppression and Sound Recognition**AI-driven noise suppression can now filter out background noise with precision, making it easier to keep an open audio line without disruptions. **Sound recognition algorithms** also allow AI to detect and elevate important sounds (like speech) over ambient noise, ensuring only relevant audio is transmitted. For example, users could keep the line open without worrying about background conversations, which the AI would suppress automatically.
3. **Privacy-First Design**Today’s AI tools can **manage privacy intelligently**, allowing users to set boundaries on what is shared. For example, the AI could be programmed to mute specific types of sounds, only open the line under certain conditions, or provide notifications when someone joins a conversation. Users remain in control, adjusting their level of connection based on their preferences.
4. **Energy and Resource Optimization**The continuous nature of always-on communication requires efficient resource management to avoid draining battery or bandwidth. **Adaptive streaming algorithms** allow AI to lower the connection quality when it’s not needed and scale up during active communication. This makes always-on connectivity feasible, even for mobile devices.
### **A New Era of Connection**
Thanks to these advancements, always-on communication is closer than ever to achieving **seamless, intuitive connection**. Imagine staying connected with your team without scheduling calls or being able to jump into a conversation without “calling” someone. As AI continues to evolve, always-on communication will feel less like a call and more like an extension of natural conversation, making it possible to stay in touch effortlessly.
By integrating smarter AI into always-on communication, we’re creating a future where staying connected is as simple as being in the same room.
[Get In touch](/contact)
---
# An App to Listen to Podcasts Together: Why It’s Needed and How It Could Work
> Discover how synchronized podcast playback and real-time audio communication SDKs enable seamless group listening experiences. Learn how to integrate audio synchronization, live voice channels, and customizable sharing platforms using the Switchboard SDK. Start building the next generation of social audio applications today.
### **The Use Cases for Shared Podcast Listening**
Listening to podcasts together offers a way to enjoy shared interests on the go. For example:
* **Couples out walking their dog or spending time outdoors** could enjoy stories or learn something new together without carrying a speaker.
* **Friends or family members** could share the experience of an insightful talk or a comedy podcast, creating shared memories.
* **Remote listening** would be useful too, for friends who want to stay connected by listening to the same podcast even when apart.
### **Technical Challenges and Opportunities**
Creating an app for shared podcast listening poses a few technical challenges:
1. **Bluetooth Limitations**: While Bluetooth allows sharing audio on the same device, it doesn’t enable two-way communication between headphones, meaning listeners can’t talk over the podcast without pausing.
2. **Real-Time Communication**: To allow seamless conversation, the app would need to mix podcast audio with a live voice channel, balancing audio so listeners can chat without interrupting playback.
3. **Sync and Control**: Both listeners need a synced experience, allowing one person to pause or adjust the volume without disrupting the other.
### **Why Switchboard is Perfect for This Solution**
**Switchboard SDK** makes it easy to build shared audio experiences, offering tools for **real-time communication, audio mixing, and synchronization**. The SDK enables developers to blend podcast audio with live voice channels seamlessly, allowing listeners to talk over the audio without lag or interference.
Synervoz already offers similar applications as white-label solutions, so developers can create customized versions tailored to different audiences and use cases, whether for friends, families, or even remote teams looking for casual learning breaks.
A shared podcast listening app could redefine how we spend time together—no longer bound by Bluetooth or cumbersome audio setups. With tools like Switchboard, creating these shared audio experiences can be done much faster and cheaper than ever before.
[Get In touch](/contact)
---
# An Opportunity for Telcos to Offer “Presence as a Service”
> Learn how telcos can leverage AI and real-time data to offer “Presence as a Service,” enhancing connectivity and enabling seamless communication while prioritizing privacy and security.
### **AI-Powered Presence: A New Kind of Status Indicator**
Telcos are uniquely positioned to offer this service because they have access to a wide range of data from customer devices and network activity. Imagine a service that can tell when a user is out for a walk, based on step data from their phone, or when they’re working on their computer, based on internet usage patterns. By analyzing these inputs, an AI-powered “presence” system could **automatically update a user’s availability**, letting friends and family know whether they’re available for a chat or preoccupied.
Though similar to the concept of “active” status in messaging apps, **Presence as a Service** would be far more advanced, creating a nuanced picture of availability beyond a simple “online” or “offline.” For example, it could show whether someone is active at home, working, or in transit, letting close contacts know when they’re most likely to respond.
### **Managing Privacy Concerns and Security**
Of course, the idea of telcos monitoring user activity might sound invasive, raising valid privacy and security concerns. To make Presence as a Service feasible, **robust privacy controls and opt-in consent** will be essential. AI can be used to manage these controls, allowing users to toggle their presence on and off easily. **Data security**—a strength of most telecom providers—would also be critical. As custodians of this information, telcos could offer secure storage and management of user data, limiting access and ensuring only authorized individuals or systems can view presence information.
### **An Opportunity for Telcos to Compete with Big Tech**
Presence as a Service represents an opportunity for telcos to stake a claim in the competitive digital communications space. With big tech and startups innovating rapidly, **telcos risk losing ground** if they don’t move early. By offering services that make life more seamless, telcos can reclaim relevance, positioning themselves not just as connectivity providers but as **enhancers of personal and professional connections**. Those who opt into such a service may find they connect more often with loved ones, discovering availability intuitively instead of missing opportunities to reach out.
The question is, will telcos seize this opportunity to leverage their competitive advantage, or will they wait for others to disrupt the market? In a world that values convenience and connection, telcos have a unique chance to offer a service that enhances how we stay in touch, making availability as seamless as the networks they provide.
[Get In touch](/contact)
---
# Audio AI: Where Research and Engineering Meet
> Audio is a natural human interface, but also one of the hardest for machines to truly understand. Over the last decade, Audio AI has quietly evolved from a niche research topic into a foundational technology powering voice assistants, real-time communications, media creation, accessibility tools, and increasingly, autonomous and agentic systems.

Audio is a natural human interface, but also one of the hardest for machines to truly understand. Over the last decade, Audio AI has quietly evolved from a niche research topic into a foundational technology powering voice assistants, real-time communications, media creation, accessibility tools, and increasingly, autonomous and agentic systems.
Yet behind the apparent simplicity of “speech in, speech out” lies a deep divide — one that anyone building serious audio products eventually runs into. That divide is between **Audio AI research** and **Audio AI engineering**.
They are closely related. They depend on each other. But they are not the same thing — and confusing them is one of the most common reasons promising audio ideas fail to make it into real products.
## Research meets Engineering
At a high level, Audio AI research is about discovering what is possible. Audio AI engineering is about making those discoveries **work reliably in the real world.**
Researchers push boundaries. They ask questions like: *Can a model separate overlapping speakers better than humans? Can a network infer emotion, intent, or spatial context from raw audio? Can we generate speech or music that is perceptually indistinguishable from reality?*
These questions are answered in papers, benchmarks, and experiments. Success is measured by novelty, insight, and performance on controlled datasets. Latency, memory usage, or runtime stability are often secondary — sometimes irrelevant.
Engineering starts where research leaves off.
Engineers inherit models that look impressive in isolation and are asked to embed them into products with real users, real constraints, and real consequences. Suddenly, the question is no longer *“Does this model work?”* but *“Can this model run in 10 milliseconds, on a phone, without glitching audio, draining battery, or crashing?”*
That shift changes everything.
## Audio AI Research Today
To understand the gap, it helps to look at where audio research is currently focused.
A large portion of modern Audio AI research is aimed at human-like listening — systems that don’t just classify sounds, but understand scenes. This includes identifying multiple simultaneous speakers, tracking who is talking when, understanding background context, and selectively attending to relevant audio in noisy environments. Humans do this effortlessly; machines still struggle.
Another major thread is **audio generation**. This spans expressive text-to-speech, singing synthesis, music generation, and audio style transfer. Modern models can produce stunning results — but often at significant computational cost, with little concern for real-time constraints.
There’s also deep work happening in **audio enhancement and separation**: pulling voices out of noise, isolating instruments, restoring degraded recordings. These problems blend classic DSP with data-driven learning and are still far from “solved” in unconstrained environments.
More recently, research has expanded into **semantic and emotional understanding of sound**, as well as **audio authenticity and deepfake detection**, driven by the rapid improvement of generative models.
All of this research is vital. It defines the future of what machines could hear, say, and understand.
But none of it ships by accident.
## Why Real-Time Audio Engineering Is a Different Discipline
Real-Time audio has a property that makes engineering uniquely unforgiving: **time never stops**.
If you miss a video frame, you might drop a frame. If you miss an audio deadline, you produce silence, distortion, or instability — and the user notices immediately.
Real-time audio systems operate inside tight, deterministic loops. At common sample rates (44.1kHz, 48kHz, or higher), software must process buffers every few milliseconds, without fail. There is no room for garbage collection pauses, unpredictable scheduling, or “eventually consistent” behavior.
This is why serious audio software — especially low-latency systems — is still written largely in C or C++. Not because engineers love complexity, but because they need **precise control over memory, timing, and execution**. High-level abstractions are often too slow, too unpredictable, or too opaque.
Now add AI into that loop.
Most modern machine-learning frameworks are designed for throughput, not determinism. They assume batch processing, elastic latency, and powerful hardware. Drop one of those models into a real-time audio thread and everything breaks unless it’s carefully adapted, optimized, and constrained.
This is where the talent bottleneck appears.
Real-time audio engineers need to understand:
* Low-level DSP and signal flow
* Multithreaded systems and lock-free design
* Memory allocation strategies
* Platform-specific audio APIs
* AND modern ML models, inference runtimes, and optimization techniques
That combination is rare. Universities tend to teach one side or the other. Many ML engineers have never written code that must hit a 5-millisecond deadline forever. Many DSP experts have never deployed neural models. The overlap is small, and increasingly valuable as real time voice and audio products proliferate.
## The Invisible Work of Commercialization
Turning cutting-edge audio research into a product is less about invention and more about translation.
Models need to be reshaped, compressed, quantized, sometimes partially rewritten. They need stable APIs, predictable performance, and graceful failure modes. They need to coexist with traditional DSP blocks — compressors, filters, mixers — that still outperform AI in many scenarios.
They also need to run everywhere: mobile devices, browsers, desktops, embedded hardware. Each environment introduces different constraints and failure modes.
This is why the distance from “paper” to “product” in audio is often measured in years, not months — unless you have the right infrastructure and team in place.
## Closing the Gap: Research Meets Engineering at Synervoz
At Synervoz, we’ve spent years operating precisely at this boundary.
We collaborate closely with researchers pushing the limits of what audio AI can do — and pair that work with a full in-house engineering team experienced in real-time systems, cross-platform deployment, and production-grade audio software. The result is not just prototypes, but **working systems**.
This is the philosophy behind **Switchboard**: a platform designed to absorb cutting-edge audio research and make it deployable, composable, and commercially viable — without forcing teams to reinvent years of real-time audio infrastructure themselves.
Audio AI doesn’t advance by research alone, and it doesn’t succeed by engineering alone. Progress happens where the two meet — where bold ideas survive contact with reality and emerge as tools people can actually use.
That intersection is where we choose to build.
---
# Audio AR, Wearables, Hearables, and Emergent Hardware Platforms
> Explore the cutting-edge world of Audio AR development, where AI-driven voice interfaces and smart audio wearables redefine augmented reality experiences. Learn how to integrate voice recognition, NLP, and spatial audio into next-gen wearable devices and emergent hardware platforms. Start building the future of interactive audio today!
### **Bose AR: An Early Audio-First Approach to AR**
Bose AR, launched in 2018, was a pioneering attempt at **audio-based augmented reality**. Rather than relying on visuals, Bose AR focused on delivering contextual audio experiences by pairing sound with real-world locations. Although Bose eventually phased out the platform, the Bose AR initiative demonstrated that **sound could be used as a core element in AR experiences**, creating immersive environments and information delivery without requiring a screen.
### **The Rise of Audio-Driven AR with Meta and Others**
Now, Meta has taken up the mantle with its **Meta Glasses**, blending augmented reality with social experiences. Unlike visual-heavy AR devices, these new wearables are **audio-centric**, leveraging voice and sound to provide users with a seamless, heads-up interaction. Users can take calls, interact with voice assistants, and listen to content without needing to pull out a phone, and these glasses point toward a future where **audio is the primary mode of interaction** in the AR space.
### **Emerging Concepts from Jony Ive and Humane**
The next generation of wearables is also seeing **high-profile experiments**, such as Jony Ive’s work with OpenAI and the **Humane Pin**. These devices aim to create natural interactions with minimal hardware, focusing on intuitive use and voice interaction. Humane’s wearable, for instance, is designed to provide seamless access to digital information without requiring users to touch or look at a screen, hinting at a future where devices become **extensions of human intention, controlled by voice and gestures**.
### **Why Audio and Voice Will Lead the Way**
No matter the form factor, audio remains the **lowest common denominator** in these devices. Whether it’s an advanced AR headset or a minimalist wearable, **microphones and speakers** are universally present and becoming increasingly powerful thanks to advancements in **AI and natural language processing**. Voice interfaces allow for hands-free, natural interaction, making it easier for users to communicate with devices on the go. AI-driven voice recognition and processing mean that wearables can understand and respond to complex commands, becoming virtual assistants tailored to specific contexts and needs.
### **Audio as the Heart of Future Interaction**
As these emerging platforms refine their approaches, the devices that stick will likely share a common trait: they’ll leverage **audio as a core interaction mode**. Audio-centric devices provide a frictionless experience, whether for accessing information, coordinating tasks, or interacting with virtual environments. This audio-first approach aligns perfectly with how we naturally interact, making it a logical next step in **human-device communication**.
With these new wearables and hearables, audio’s role will continue to expand. By embedding **AI-driven voice capabilities** in these devices, we’re moving closer to a world where speaking to our devices feels as natural as talking to another person.
[Get In touch](/contact)
---
# Audio Graphs for Robots
> Focused on software for interactive voice and video chat projects with complex audio requirements.
### **Audio Graphs for Robots**
In robotics, audio processing plays an important role in enabling machines to interact with their environment in more human-like ways. Whether it’s speech recognition, localization of sound sources, or generating responses, audio graphs can be used to manage complex audio pipelines by breaking them down into manageable, reusable components, or *nodes*.
An audio graph is a network of these interconnected nodes, where each node performs a specific function like filtering, enhancing, or analyzing audio. The outputs of one node become the inputs for another, resulting in a system that processes audio efficiently. Let’s explore how audio graphs work in robotics by looking at a few examples.
#### **Example 1: Speech Recognition, Intent, and Response**
For a robot to understand human speech and interact in a meaningful way, an audio graph could be used to break down the process into several steps:
1. **Microphone Node**: This node captures the raw audio from the environment. The data from this node is fed into the next node.
2. **Voice Activity Detection (VAD) Node**: This node detects the presence of human speech in the audio stream, enabling the robot to only process relevant audio data.
3. **Speech-to-Text Node**: Once the voice has been isolated, this node converts spoken words into text that the robot can interpret and respond to.
4. **LLM Node:** This helps the robot determine the user’s intent, and can be combined with additional logic to drive the robot’s response.
5. **Text-to-Speech Node:** As part of the robot’s response, it might respond to the user with a human-like voice.
In this case, the audio graph might look like this:
\[Microphone] -> \[VAD] -> \[Speech-to-Text] -> \[LLM} -> \[Text-to-Speech]
This graph represents a simple linear flow of data through a series of nodes, turning raw audio into text from which the robot can intent and take action.
#### **Example 2: Sound Source Localization in a Mobile Robot**
A mobile robot that can navigate toward a sound source (e.g., in a search and rescue operation) needs an audio graph that can handle more complex audio data. This might involve multiple sensors and sophisticated signal processing techniques:
1. **Microphone Array Node**: Instead of a single microphone, a microphone array captures sound from multiple directions, allowing the robot to gather spatial information about the sound source.
2. **Beamforming Node**: Beamforming is a technique that uses the data from the microphone array to focus on sounds coming from a particular direction, isolating the sound source in a noisy environment.
3. **Direction of Arrival (DoA) Estimation Node**: This node uses the differences in time and phase between the microphones to estimate the direction of the sound source.
4. **Navigation Control Node**: Based on the output from the DoA node, as well as other contextual data, this node sends commands to the robot's motor control system to navigate toward the sound.
The audio graph for sound source localization might look something like this:
\[Microphone Array] -> \[Beamforming] -> \[DoA Estimation] -> \[Navigation Control]
This example integrates spatial awareness into the robot's audio processing pipeline.
#### **Example 3: Emotional Tone Recognition in Social Robots**
Social robots that interact with humans need to understand not just the words but also the emotional tone behind them. An audio graph for emotional tone recognition might include:
1. **Microphone Node**: Capturing the raw audio.
2. **Pitch Detection Node**: This node analyzes the pitch of the speaker's voice, as emotional tone often correlates with pitch variations.
3. **Spectral Analysis Node**: By breaking the audio into its frequency components, this node can detect subtle changes in voice that signal different emotions.
4. **Emotion Classification Node**: The final node uses machine learning to classify the emotional tone of the speaker, such as happiness, anger, or sadness.
The audio graph would look like this:
\[Microphone] -> \[Pitch Detection] -> \[Spectral Analysis] -> \[Emotion Classification]
In this case, the robot can adjust its behavior or responses based on the recognized emotion, enhancing human-robot interaction.
Audio graphs in robotics enable machines to process audio data in an organized and efficient manner. By breaking down complex tasks into individual nodes, each focused on a specific function, robots can accomplish sophisticated tasks like communicating with humans and taking action, sound localization, and emotion detection. These audio graphs form the backbone of auditory perception systems in robots, creating more natural, responsive interactions with humans and environments.
## **On-Device vs. Cloud-Based Audio Processing in Humanoid Robots: Striking the Right Balance**
As humanoid robots become more integrated into daily life, their ability to process audio efficiently and effectively is paramount. A critical design consideration is determining which audio processing tasks should be handled on the robot itself (on-device) versus those delegated to cloud-based systems.
### **On-Device Audio Processing: Ensuring Real-Time Responsiveness**
Tasks requiring immediate response and low latency are typically processed on-device to ensure seamless interaction. Key on-device audio processing tasks include:
* **Wake Word Detection**: Listening for activation phrases like "Hey Robot" to initiate interaction.
* **Basic Speech Recognition**: Transcribing voice commands into text for immediate action.
* **Noise Reduction and Echo Cancellation**: Enhancing audio clarity in real-time environments.
* **Immediate Command Execution**: Performing tasks such as stopping movement or responding to hazards without delay.
**Examples from Industry Leaders**:
* **Tesla Optimus**: Designed with significant on-device processing capabilities to handle real-time tasks, reducing reliance on external servers.
* **Figure's Helix AI**: Implements mostly on-device processing ensuring privacy and quick responsiveness. Uses a unified Vision-Language-Action model which integrates perception, planning, and control into a single neural network (trained on hundreds of hours of supervised human demonstrations).
* **Boston Dynamics' Spot**: Utilizes on-device processing for immediate tasks, with options to connect to cloud services for additional functionalities.
### **Cloud-Based Audio Processing: Leveraging Advanced Capabilities**
More complex tasks that require substantial computational resources or access to extensive data sets are often handled in the cloud. These include:
* **Advanced Natural Language Processing (NLP)**: Understanding nuanced language and context.
* **Language Translation**: Converting speech between different languages.
* **Large Language Model (LLM) Integration**: Utilizing models like GPT for sophisticated interactions.
* **Data Logging and Analytics**: Storing and analyzing interaction data for improvements.
**Examples from Industry Leaders**:
* **Figure's Earlier Models**: Initially relied on cloud-based GPT-4 for processing complex language tasks.
* **Boston Dynamics' Spot**: Can connect to cloud platforms like AWS and Azure for data analysis and mission planning.
* **Unitree Robots**: Utilize cloud services for over-the-air updates and enhancements, ensuring the robots stay current with the latest features.
### **Hybrid Approaches: Combining the Best of Both Worlds**
Many humanoid robots adopt a hybrid approach, processing critical tasks on-device while leveraging cloud capabilities for more complex functions. This strategy allows robots to:
* **Maintain Functionality Offline**: Ensuring essential operations continue without internet connectivity.
* **Enhance Capabilities Online**: Accessing advanced processing and data when connected.
* **Optimize Performance**: Balancing immediate responsiveness with the richness of cloud-based resources.
**Real-World Application**:
* **Amazon Nova Sonic Integration**: Combines on-device voice control with cloud-based AI for seamless speech-to-speech interactions in humanoid robots.
### **Determining Processing Allocation: Factors and Considerations**
Robots assess various factors to decide whether to process audio tasks on-device or in the cloud:
* **Latency Requirements**: Tasks needing instant response are prioritized for on-device processing.
* **Connectivity Status**: Availability and reliability of internet connections influence the feasibility of cloud processing.
* **Computational Demand**: Tasks exceeding on-device capabilities may be offloaded to the cloud.
* **Privacy Concerns**: Sensitive data is often kept on-device to protect user privacy.
### **Conclusion**
The division of audio processing tasks is crucial in the design of humanoid robots. By strategically allocating tasks based on immediacy, complexity, and privacy considerations, developers can create robots that are both responsive and capable of sophisticated interactions.
[Get In touch](/contact)
---
# Audio Opportunities in the Healthcare Industry: Harnessing Sound for Better Diagnosis and Care
> Explore how AI-driven audio technologies are transforming healthcare, from cough sound analysis and vocal biomarkers for mental health to real-time audio streaming for telemedicine. Learn how to integrate low-latency audio solutions, embedded signal processing, and HIPAA-compliant APIs into medical applications. Start building the future of audio-driven health diagnostics today!
### **Diagnosing Through Audio: Potential Use Cases**
1. **Respiratory Illness Detection**The sound of a cough can indicate much more than a common cold. AI models are now capable of analyzing cough patterns to detect respiratory conditions like **pneumonia, asthma, or even early signs of throat cancer**. By capturing cough sounds through a smartphone microphone, healthcare providers could receive early warning signs of these conditions, enabling faster intervention. AI-driven cough analysis can distinguish different illnesses based on the sound’s frequency, intensity, and duration, making it a powerful tool for respiratory diagnostics.
2. **Analyzing Baby Cries for Health Concerns**Audio analysis of baby cries offers promising insights into neonatal health. Studies show that different health conditions, such as colic or neurological issues, may cause distinct variations in a baby’s crying patterns. By using **machine learning algorithms to analyze cry frequencies and patterns**, healthcare providers could better diagnose issues like pain, fever, or even developmental disorders. This approach could offer peace of mind to new parents and support early intervention for infants with potential health concerns.
3. **Heart Health Monitoring**Audio can also play a crucial role in cardiovascular health. For example, **Heartscreen**, a pioneering solution developed to measure heartbeats using a microphone, demonstrates how audio technology can assess cardiac rhythms and identify irregularities without specialized equipment. This type of audio-based heart monitoring could become a valuable tool for detecting early signs of heart disease or arrhythmias, making regular cardiovascular monitoring more accessible to a broader population.
4. **Detecting Cognitive and Mental Health Conditions**Vocal analysis can also provide insights into a person’s mental and cognitive health. Studies suggest that voice patterns may change with conditions like **Alzheimer’s disease, depression, or anxiety**. By tracking speech patterns, pitch, and rhythm, AI-powered tools could detect subtle changes that signify cognitive decline or mental health issues. This data could offer healthcare providers valuable insights, enabling early intervention and treatment planning for patients.
### **Adjacent Opportunities in Remote Patient Monitoring**
With the rise of telemedicine, audio analysis also presents valuable applications in remote patient monitoring. For example:
* **Sleep Apnea Detection**: Monitoring breathing patterns through audio can help detect sleep apnea episodes, allowing doctors to prescribe appropriate treatments.
* **Pain Detection**: For patients who may struggle to communicate, such as the elderly, analyzing sounds like groans or sighs could indicate pain levels, enabling caregivers to respond promptly.
### **Privacy and Accessibility Considerations**
While audio-based diagnostics offer exciting potential, they also raise important privacy and accessibility questions. Ensuring data privacy, particularly with sensitive health information, will be critical as these tools evolve. However, audio-based diagnostics can also **improve accessibility to healthcare**, making it easier for people in remote or underserved areas to access critical health screenings with just a smartphone.
### **The Future of Audio in Healthcare**
As healthcare providers and technology companies continue to explore audio’s diagnostic potential, audio tools could soon become a standard part of the diagnostic process. By listening to the body’s sounds—whether it’s a heartbeat, a cough, or a baby’s cry—the healthcare industry is opening new doors for non-invasive, accessible care, helping to create a future where diagnosis is as easy as pressing “record.”
[Get In touch](/contact)
---
# Better Audio for Motorcyclists: Bridging the Noise and Communication Gap
> Explore the latest advancements in motorcycle intercom systems, from Bluetooth helmet communication and mesh networking to AI-driven noise suppression and wind noise reduction. Learn how to integrate hands-free voice controls, environmental sound recognition, and mobile connectivity for smarter, safer riding. Start building the future of motorcycle audio today.
### **The Noise Suppression Challenge**
Wind, engine rumble, and city noise make it challenging for riders to hear music, navigation cues, or each other. **Active Noise Cancellation (ANC)**, as seen in wireless earbuds like the AirPods Pro, has become a popular workaround, but there are limitations. For example, ANC often dampens all external noise indiscriminately, which can **block essential sounds** like sirens, horns, or approaching vehicles. A “**smart transparency**” feature that selectively lets through these critical sounds while muting others would be a game-changer.
In an ideal solution, motorcycle audio systems could incorporate **AI-driven sound recognition**, allowing them to identify and prioritize specific sounds. This would enable riders to safely enjoy their music or intercom while staying alert to their surroundings.
### **Better Communication at Stop Lights**
One of the biggest communication hurdles for motorcyclists is talking to friends at stoplights, where noise levels are still high, and where it’s common that not all riders are wearing an intercom.. A system that could **amplify human voices** while continuing to filter out ambient noise would make quick conversations with fellow riders much easier. Advances in **beamforming microphones** and **voice recognition technology** could allow audio systems to focus on nearby voices while continuing to filter out wind and engine noise, making it easier to communicate without shouting.
### **Staying Connected On and Off-Grid**
Despite the appeal of wireless earbuds, motorcycle intercoms still have a significant advantage: they work **off-grid**. Mesh networking from systems like Cardo and Sena’s intercoms provide reliable communication even in areas without cell coverage, which is essential for group rides in rural or mountainous areas. Until mesh networking becomes a standard feature on everyday mobile devices or earbuds, the dedicated intercom will remain the go-to for off-grid riders.
To remain relevant in the face of a fast improving mobile devices and earbuds,, intercom manufacturers like Cardo and Sena could look into pocket based **mesh networking devices** that integrate with with mobile devices. We’d also love to see features that make it easier and hands free to switch between group chats, individual riders, and communication apps on your phone that aren’t necessarily related to the ride.
### **Smart Controls and Hands-Free Functionality**
Current motorcycle audio solutions often lack intuitive controls. Riders need **hands-free ways to manage music, navigation, the intercom, and outside calls**, along with options to quickly switch between individual and group communications. A rider should find it easy to **pause music, join the group playlist or listen to their own, take calls privately or have side-channel discussions off of the main group chat, all** without affecting their group chat or disturbing others. A combination of voice controls and a physical button could make this easy. Voice-activated AI assistants like ChatGPT could be another excellent addition, allowing riders to ask questions, get weather updates, or receive navigation assistance without disrupting their intercom channel. These will be especially useful when they’re able to reach into applications to take deeper actions.
Improvements in **hands-free interfaces and voice-command accuracy** would greatly enhance the rider experience. For example, a rider could switch back and forth between music, chat, and an AI assistant without the need to fumble around with small buttons or issue complicated commands, creating a more seamless and safer experience.
### **Looking Ahead: Future-Proofing Motorcycle Audio**
As technology advances, the motorcycle audio industry will need to keep pace with new audio and communication technologies. **Smarter noise cancellation, selective transparency, and better voice amplification** (or amplification of other desirable environmental sounds) could transform the riding experience. Additionally, developments in mesh networking, hands-free control, and voice assistant integration will be crucial as riders seek more seamless, safer ways to communicate on the road.
[Get In touch](/contact)
---
# Building an SDK is Painful—But It Doesn't Have to Be for Audio Developers
> Discover how to streamline audio SDK development with optimized DSP algorithms, real-time audio processing, and AI-powered voice enhancement. Learn best practices for cross-platform development in Swift and Kotlin, seamless API integration, and building robust machine learning audio models. Start simplifying your audio development process today.
### **Building an SDK is Painful—But It Doesn't Have to Be for Audio Developers**
Building a software development kit (SDK) is no easy feat. If you're a developer working on a piece of core technology—whether it's an advanced digital signal processing (DSP) module, a machine learning-based audio model, or any other audio-centric tool—you're already dealing with a lot of technical complexity. The idea of building an entire SDK on top of that to make your technology accessible to other developers can feel overwhelming.
An SDK involves much more than just exposing your technology through an API. It requires comprehensive documentation, cross-platform support, version control, integration with other tools, constant maintenance, and, most importantly, a deep understanding of the programming languages and environments that your users will work in. Do you want to spend valuable time keeping up with the constantly evolving ecosystems of Swift, Kotlin, JavaScript, or C++? Probably not, especially when your core innovation lies in something like machine learning for speech synthesis or voice enhancement.
### **The Pain of Building and Maintaining SDKs**
For most teams, building an SDK isn't just a one-time effort. It's an ongoing process that demands attention long after your initial release. As operating systems evolve, languages change, and developer expectations grow, your SDK needs to keep pace. You might find yourself spending more time fixing compatibility issues, writing documentation, and handling support queries than focusing on the innovation that got you started in the first place.
That’s where the real pain comes in. You end up spending precious resources on building an SDK from scratch, even though your core value is in your technology, not in the infrastructure around it.
### **Enter Switchboard: The SDK for Audio SDK Developers**
What if you didn’t have to build an SDK at all? What if there was a way for you to focus on your core technology—whether it's a custom DSP algorithm, noise suppression filter, or a cutting-edge voice changer—without getting bogged down in the SDK development process?
That’s where Switchboard comes in.
Switchboard allows you to turn your core technology into a fully featured SDK without ever building one from scratch. The framework is designed to take care of all the heavy lifting, letting you build a simple wrapper around your DSP module or audio model. From there, Switchboard provides everything else you need to make your technology accessible from high-level languages like Swift, Kotlin, and JavaScript. You can offer your tech as a plug-and-play solution to developers across multiple platforms, without needing to maintain compatibility with every OS update or language quirk.
### **Why Focus on Your Core Tech?**
Switchboard lets you streamline your development process. Here’s why it’s a game-changer for teams working on audio technology:
Skip the SDK Pain: You no longer need to worry about developing and maintaining your own SDK. Switchboard has the infrastructure in place, so you can focus on refining your core technology.
Cross-Platform Ready: Switchboard is designed to make your technology accessible in Swift (for iOS), Kotlin (for Android), and JavaScript (for web). That means instant multi-platform support for your DSP module or machine learning model.
Save Time and Resources: Imagine how much more you could accomplish by dedicating resources to improving your noise suppression algorithm, voice-changer library, or text-to-speech model, rather than wrangling SDK code.
Built for Audio: Switchboard is specifically designed for audio developers. Whether you're building real-time voice processing, machine learning-powered speech recognition, or even interactive audio tools, Switchboard provides the framework you need.
### **A Better Solution for Audio SDK Developers**
For teams developing things like text-to-speech engines, voice changers, noise suppression libraries, and anything else in the audio world, Switchboard can be a game-changer. You can spend less time wrestling with SDKs and more time building world-class audio technology.
In the rapidly growing field of audio innovation, especially as voice interfaces and AI-driven sound tools become more critical, you want your focus to be where it matters: on making your core product the best it can be.
Switchboard lets you do exactly that. Let the SDK pain become a thing of the past, and let your technology shine in the hands of developers without the headache of maintaining a complex SDK ecosystem.
Focus on your core tech —[Switchboard ](https://switchboard.audio/)has the Rest Covered.
[Get In touch](/contact)
---
# Cartesia, ElevenLabs, and the Rise of Generated Audio in Text-to-Speech
> Explore the rise of AI voice synthesis and natural-sounding Text-to-Speech (TTS) solutions, from neural network voice generation to emotionally nuanced speech synthesis. Discover how real-time audio processing and dynamic TTS integration are shaping interactive audio experiences. Read more to stay ahead of the curve!
### **The Power of Cartesia and ElevenLabs in TTS**
**ElevenLabs** and **Cartesia** are at the forefront of generating lifelike audio from text inputs. Both platforms leverage advanced neural networks to produce voices that sound convincingly human, moving past the limitations of traditional robotic TTS.
* **ElevenLabs**: Known for its highly realistic voice synthesis, ElevenLabs specializes in generating emotionally nuanced audio. This makes it ideal for applications in gaming, entertainment, and even voiceovers, where the AI-generated voices need to express subtle emotions or variations in speech patterns.
* **Cartesia**: While ElevenLabs focuses on expressive TTS, Cartesia emphasizes **scalable and customizable audio** for a variety of commercial applications. Cartesia’s TTS solutions are popular in customer service, virtual assistants, and accessibility, providing clear and natural-sounding voices for all sorts of interactive audio interfaces.
### **Integrating TTS into Broader Audio Graphs with Switchboard**
Text-to-Speech becomes exponentially more powerful when integrated into **broader audio ecosystems**. This is where **Switchboard** comes in, providing the framework needed to incorporate TTS into complex audio graphs.
For instance:
* **Interactive Storytelling and Games**: By integrating TTS with real-time audio controls, Switchboard enables interactive storytelling experiences where virtual characters can “speak” dynamically in response to player actions. TTS voices generated through ElevenLabs could provide nuanced voice acting, while Switchboard coordinates voice outputs with in-game events.
* **Assistive Technologies and Accessibility**: In accessibility settings, Cartesia’s TTS can be combined with audio routing through Switchboard to provide instant narration, real-time alerts, and interactive voice guides. This combination allows for a smoother, more responsive user experience tailored to individual accessibility needs.
* **Multi-Source Audio and Broadcasting**: Imagine a live broadcast where TTS-generated news updates are seamlessly mixed with live interviews and background music. Switchboard’s audio graph capabilities allow developers to layer and manage these sources, integrating TTS voices dynamically as updates are needed.
### **Why Generated Audio Is Gaining Momentum**
The adoption of TTS in various applications signals a broader trend toward **audio-centric interaction**. Generated audio offers not only accessibility but also efficiency and creativity in content creation. With the flexibility of TTS, developers can instantly generate and adapt voice content, which is invaluable for industries that need to scale voice interactions quickly.
Incorporating generated audio with **Switchboard’s multi-streaming capabilities** means that businesses and creators can now design highly interactive, responsive audio experiences that blend live sound, TTS, and pre-recorded audio seamlessly.
### **The Future of TTS and Interactive Audio**
As TTS solutions like Cartesia and ElevenLabs evolve, we’re likely to see increasingly sophisticated and personalized applications. With tools like Switchboard, integrating TTS into broader audio environments is becoming simpler, enabling applications that require more nuance and adaptability than ever before. This dynamic audio landscape is poised to revolutionize how we experience digital content, making voice interaction and generated audio more accessible, flexible, and compelling for all.
[Get In touch](/contact)
---
# Interview with Synervoz CEO Jim Rand
> Focused on software for interactive voice and video chat projects with complex audio requirements.
[Play](https://youtube.com/watch?v=mf-S4oG1Mag)
See more videos on our [YouTube channel](https://www.youtube.com/@switchboard2718).
[Get In touch](/contact)
---
# Edge AI for Voice and Audio: Why the Future is On-Device
> Cloud-based audio AI brought us speech recognition, conversational AI agents, and more. But as usage grows beyond proofs of concept, the weaknesses of the cloud have become glaring.

| | |
| --------------------------- | ------------------------------------------------------------------------------ |
| ###### Topic | ###### Key Takeaway |
| Industry Trend | Audio AI is rapidly shifting from the cloud to the edge |
| Problem with Cloud-Based AI | Latency, privacy risks, cost, and dependence on connectivity |
| Edge AI Types | On-device (phones, tablets) vs embedded (smart speakers, wearables) |
| Why Edge AI Now? | Faster chips, better models, real-time needs, demand for privacy |
| Use Cases | Voice assistants, voice changers, speech enhancement, music tools, safety |
| Switchboard's Role | Modular SDK for real-time, low-latency, cross-platform audio processing graphs |
| Strategic Advantage | Hybrid-ready, flexible SDK for web, mobile, embedded, and offline environments |
## Why the Cloud Can’t Keep Up with Audio AI
Cloud-based audio AI brought us speech recognition, conversational AI agents, stem separation, voice changers, and real-time translation. But as usage grows beyond proofs of concept, the weaknesses of the cloud have become glaring:
* **Latency**: Cloud roundtrips, especially for complex systems, add up and quickly become unacceptable in sensitive real time use cases including gaming, conferencing, and safety-critical apps.
* **Privacy**: Sending voice data off-device creates security and regulatory headaches, and often becomes a blocker in enterprise use cases.
* **Cost**: Streaming high-resolution audio to the cloud is expensive, power-hungry, and wasteful.
* **Connectivity Dependency**: Even momentary internet loss breaks the experience.
*Edge AI*—running models locally on the user’s device—is rapidly becoming a critical part of the solution for real-time audio interactions.
## On-Device vs Embedded
| | | |
| ------------- | -------------------------------------------- | -------------------------------------------- |
| ###### Aspect | ###### On-Device AI | ###### Embedded AI |
| Hardware | Phones, laptops, tablets | Smart speakers, earbuds, cars, sensors |
| OS/Env | Android, iOS, Windows, Linux | Embedded Linux, RTOS, microcontrollers |
| Model size | Medium–Large (optimized for NPUs/GPUs) | Ultra-small (<10MB), highly quantized models |
| Update Method | App updates or OTA | SDK-flash, firmware |
| Use Case | Voice chat apps, music players, live editing | Always-on voice UIs, safety features, toys |
One way to break down what constitutes “Edge AI” is by the hardware and OS it runs on. Most use cases could be classified into one of the two categories above. This distinction matters: designing for on-device AI means targeting user-facing applications, while embedded AI is ideal for low-power, passive, real-time environments like wearables, soundbars, or IoT.
## What’s Driving the Shift to Edge Audio?
1. **NPUs in Consumer Hardware**: The Apple Neural Engine, Qualcomm Hexagon, and Google Tensor cores are making serious inference power available locally.
2. **Smaller, Faster Models**: Whisper, DistilHuBERT, and real-time Voice Conversion models now run under 100ms latency on mobile.
3. **Developer Stack Maturity**: Tools like ONNX Runtime, OpenVINO, and CoreML make cross-platform deployment more feasible than ever.
4. **Edge SDKs**: Platforms like **Switchboard** lower the barrier for building audio products with an edge-first runtime.
## Real-World Use Cases for Edge Audio AI
Here are examples from both Switchboard’s customer base and the broader market:
### Conversational Voice AI
* Intelligent assistants that still work offline (hybrid)
* Immediate feedback from small models that can communicate with other models
* Hands-free / voice controlled applications
### Gaming & Social
* Real-time voice changers (e.g., child-safe filters or roleplay)
* Local noise suppression and specific speaker detection
* AI-based NPC voice control offline (agent-based speech-to-speech)
### Music & Creator Tools
* On-device stem separation (practice mode, karaoke)
* Smart EQ and compressor graphs
* Jam session sync over peer-to-peer networks
### Communication & Conferencing
* Local echo cancellation, gain control, and dynamic speech enhancement
* Private transcription (e.g., confidential call logs)
* Barge-in detection and AI agent switching
### Automotive & Smart Devices
* Voice command parsing without cloud connection
* In-vehicle safety alerts based on sound context
* Selective noise cancellation on embedded speakers
## How Switchboard Makes Edge Audio AI Actually Buildable
While many SDKs focus on specific models (like transcription or stem separation), **Switchboard **provides a general-purpose **audio graph engine** and a modular SDK for building custom real-time audio pipelines:
### Key Features
* **Graph-Based Audio Processing**: Build and arrange processing nodes like STT, TTS, filters, DSP, media players, etc.
* **Modular Nodes**: Plug-and-play architecture lets you add speech-to-text, voice changers, or noise reduction as needed.
* **Low-Latency Real-Time**: Designed for interactive use cases like games, agents, and comms.
* **Hybrid Cloud + On-Device**: Supports seamless fallback to cloud inference or augmentation.
* **Cross-Platform**: Targets iOS, Android, WebAssembly, embedded Linux, and more.
* **Built-in Voice Activity Detection (VAD)** and extensions such as Whisper, Silero, or OpenVINO-accelerated models.
## Example: From Cloud to Edge in One Graph
Say you're building a karaoke app. Here's how your pipeline might evolve:
| | | |
| ---------------- | -------------------------------------- | -------------------------------------------- |
| ###### Component | ###### Initial Approach | ###### Switchboard Edge Approach |
| Vocal Removal | Cloud stem separation API | On-device node using embedded separation |
| Lyrics Timing | Server Whisper inference | Real-time mobile Whisper STT node |
| Model size | Medium–Large (optimized for NPUs/GPUs) | Ultra-small (<10MB), highly quantized models |
| Voice FX | Cloud rendering | Switchboard graph with reverb & pitch FX |
| Agent Coaching | Streamed to OpenAI | Local LLM w/ fallback to cloud GPT |
With Switchboard, switching between these scenarios is just a matter of swapping nodes or flipping a config switch.
## The Strategic Opportunity: Real-Time, Private, Offline-Ready
Building for edge means:
* Your product still works in a tunnel, on a plane, or off-grid.
* You control privacy: no GDPR or HIPAA issues from cloud audio leakage.
* Latency is sub-100ms, not a second or more.
* You gain platform independence from OpenAI, Google, or AWS.
This is especially powerful for:
* Regulated industries (health, finance, defense)
* Consumer electronics (audio devices, wearables)
* Multiplayer and UGC platforms (gaming, social, virtual worlds)
## AI Will Be Heard
Audio is the next frontier for Edge AI. Unlike vision, which has high bandwidth and can tolerate latency in many use cases (like photo tagging), **voice is temporal and interactive**—which makes **real-time response** non-negotiable.
Switchboard is designed to make this transition not just possible but **easy**, **composable**, and **future-proof**.
If you're building apps where audio is **not just an output but a control surface**, the edge is where your intelligence needs to live. And Switchboard gives you the tools to live there.
---
# Edge AI Is Moving From Hype to Default
> Every business wants customer service to feel like a personal concierge. Few are set up to actually deliver one.

For years, AI architecture was treated as cloud-first by default. Capture data on the device, send it to a server, run inference there, and send the result back.
That still works for some use cases. But for a growing class of products, it’s the wrong architecture.
**Edge AI **means running some or all of an AI system directly on-device—on a phone, laptop, wearable, robot, vehicle, or embedded system—rather than pushing every workload to the cloud. And increasingly, that approach is simply better.
## Why Teams Are Moving AI to the Edge
When every interaction has to make a round trip to the cloud, products inherit avoidable problems: latency, bandwidth cost, privacy exposure, flaky connectivity, and backend complexity.
Running more AI locally changes that.
A fitness coach can respond faster. A vehicle assistant can work without perfect connectivity. A robot can make decisions in real time. A wearable can process sensitive signals without constantly streaming raw data off-device.
That’s why industries like **automotive**, **robotics**, **industrial systems**, **consumer electronics**, and **healthcare** are all pushing edge architectures forward. These are environments where speed, reliability, privacy, and cost are not nice-to-haves. They’re product requirements.
## Voice AI Is One of the Best Examples
One of the clearest places this shows up is **Voice AI**.
Voice systems break quickly when they feel slow. If an assistant hesitates, interrupts badly, or stops working when the connection degrades, users notice immediately. And if you stream raw audio to the cloud continuously, the infrastructure cost and complexity can get ugly fast.
That’s why edge-first voice architecture is becoming more important.
A modern voice product might run **VAD**, audio preprocessing, local speech recognition, or text-to-speech directly on-device, while using the cloud selectively for heavier reasoning or fallback. Instead of shipping raw audio everywhere, the device handles the fast path and only escalates when needed.
That usually means:
* lower latency
* lower cloud cost
* better privacy
* more resilient offline or degraded-network behavior
* and a much better user experience
In other words, **Voice AI at the edge isn’t just cheaper. It’s often the better product architecture**.
## Our Take: Edge-First Voice AI
At Synervoz, this is exactly the direction we’re building toward.
Our [Voice AI platform](https://switchboard.audio/voice-ai/?utm_source=chatgpt.com) is designed around an **edge-first**,** hybrid architecture** for real-time voice products. The idea is simple: run what should be local, locally—and only use the cloud where it genuinely improves the experience.
That makes it easier to build voice systems that are faster, more private, more cost-efficient, and more reliable across real-world conditions.
If you’re building voice interfaces, assistants, audio-first apps, or embedded voice products, we think the future is not cloud-only. It’s **edge-first and hybrid by design**.
You can learn more on our [Voice AI page](https://switchboard.audio/voice-ai/?utm_source=chatgpt.com).
[Get in Touch](https://synervoz.com/contact/)
---
# Engineering Listen Parties and Interactive Music Apps: The Technologies Behind Seamless Group Listening
> Discover the engineering behind real-time audio synchronization in listen parties and interactive music apps. Learn how to implement low-latency streaming, WebRTC integration, smart ducking techniques, and seamless audio pausing for uninterrupted shared listening. Start building synchronized, high-quality audio experiences today.
### **Technologies Required for Seamless Listen Parties**
1. **Synchronization of Music Playback Across Devices**Synchronizing audio across multiple participants in real-time is crucial to avoid latency issues. Everyone must hear the same beats at the same moment, whether they’re chatting in voice or just vibing silently. To achieve this, listen parties require **precise timestamping and latency buffers** to maintain consistency across different networks and devices.
2. **Collaborative Playlists and DJ Controls**A truly interactive music app allows participants to **contribute to shared playlists**, vote on upcoming songs, or take turns being the DJ. Building these features requires **real-time database synchronization** and **user-friendly interfaces** to ensure smooth collaboration without confusion.
3. **Accurate Voice Activity Detection (VAD)**Effective **VAD algorithms** can detect when someone speaks and dynamically adjust music volume to accommodate conversation. The “smart ducking” technique—automatically lowering the music when someone talks—ensures that chat and music coexist harmoniously. This creates a **natural, unintrusive blend** of audio.
4. **Seamless Mixing of VoIP and Music Streams**Mixing VoIP (voice) audio with music audio in real time without introducing artifacts or echo is a complex task. Solutions like **WebRTC** combined with spatial audio techniques help achieve seamless blending, making the audio experience feel as natural as a real-life gathering.
5. **Handling Background Audio Interruptions**Mobile users often encounter interruptions, such as incoming calls or notifications. A good listen party app must be able to **pause and resume music smoothly** without losing synchronization across participants. This requires tight integration with **operating system audio APIs** to manage interruptions gracefully.
### **Case Study: Insights from Amazon Amp**
Synervoz worked on the **Amazon Amp app,** an experimental product that offered a compelling example of both the possibilities and challenges in building interactive audio experiences. Amp allowed users to create live, radio-like broadcasts with music and conversation, providing some of the functionality found in modern listen parties. However, **balancing latency, music licensing constraints, and user experience** posed significant hurdles. Working on this project added to our insights in this evolving space, alongside several similar startup projects we also helped build, including our own app, Switchboard.
### **How Generated Music Unlocks New Collaborative Possibilities**
Generated music, powered by **AI models**, opens up exciting opportunities for collaborative music experiences, in part because it does away with the most challenging licensing constraints. Everyone can easily access the same music instantly without needing to first sign into the same service and purchase the same premium package that their friend has. That makes it work a little more like it works in the real world, where one user is allowed to play music in a room and any friends can just “listen along”. While there are many nuances here, as well as legitimate concerns among artists, making music more easily accessible for listen parties is certainly a welcome change, and generated music will help push business models in a direction that makes music more accessible and available for collaborative, interactive experiences. . . Imagine a group of friends creating and listening to music together, composing unique soundscapes in real time. Unlike traditional music libraries, which are often governed by complex copyright laws and regional restrictions, generated music offers greater **freedom for co-creation and co-listening**. This will unlock more product experimentation and could help lead to lasting changes and making such experimental features available in existing music apps, and with any music.
### **Why Music Sync is still Easier than Video Sync**
Compared to **watch parties**, synchronizing music is more straightforward. While streaming video involves managing copyrights across a huge variety of fragmented platforms and regional restrictions, **music licensing is more consolidated**. Many people already have access to radio stations, public playlists, and one of a few licensed streaming platforms, simplifying cross-platform music synchronization. For a deeper dive into video sync challenges, check out our Watch Party blog post.
### **Building with Switchboard SDK: Simplifying Development**
The **Switchboard SDK** from Synervoz makes it easier to create seamless listen parties by providing powerful tools for **audio synchronization and real-time interaction**. Whether you’re building a collaborative music app or adding social features to an existing platform, Switchboard ensures **smooth audio integration with VoIP**. Its flexible audio pipelines support mixing, ducking, and spatial audio, giving developers the freedom to craft immersive and responsive listening experiences.
### **Conclusion: The Future of Social Listening**
As listen parties evolve, they will not only offer synchronized playback but also become spaces for **collaborative creation and social interaction**. With advancements in **generated music** and platforms like **Switchboard SDK**, the possibilities are expanding—allowing friends to listen, chat, and create music together effortlessly.
[Get In touch](/contact)
---
# Exploring the Cutting-Edge Developments in AI and Machine Learning for Audio
> Focused on software for interactive voice and video chat projects with complex audio requirements.
In recent years, the fields of artificial intelligence (AI) and machine learning (ML) have made significant strides in revolutionizing various industries, and the domain of audio is no exception. Advancements in AI and ML algorithms, combined with the availability of large-scale datasets and powerful computational resources, have unlocked tremendous potential for audio-related applications. This article will delve into the state of the art in AI and machine learning for audio, highlighting notable achievements, emerging trends, and potential future directions.
### Automatic Speech Recognition (ASR)
Automatic Speech Recognition technology has witnessed remarkable advancements, enabling machines to transcribe spoken language with ever-improving accuracy. Deep learning models, such as recurrent neural networks (RNNs) and transformer-based architectures, have played a crucial role in achieving state-of-the-art performance. End-to-end ASR systems that directly map audio to text have gained popularity due to their ability to streamline the traditional multi-stage ASR pipeline. Incorporation of techniques like transfer learning and unsupervised pre-training has further improved ASR capabilities, allowing for better performance even in low-resource scenarios.
### Music Generation and Composition
AI and ML techniques have sparked innovation in music generation and composition, pushing the boundaries of creative expression. Generative models like Variational Autoencoders (VAEs) and Generative Adversarial Networks (GANs) have demonstrated remarkable aptitude in composing original music pieces. These models can learn from vast music collections, capturing the nuances of different genres and artists, and generate compositions that emulate specific styles or even create entirely new ones. Researchers are exploring ways to infuse emotional attributes into music generation models, allowing AI to compose music that resonates with human emotions.
### Audio Synthesis and Enhancement
AI-based techniques have also led to significant advancements in audio synthesis and enhancement, enabling the creation of realistic sounds and immersive auditory experiences. Deep learning approaches, such as WaveNet and SampleRNN, have revolutionized speech synthesis, producing highly natural and expressive voices. The field of audio denoising and source separation has seen progress with the development of deep learning models that can separate and enhance specific sound sources from complex audio mixtures, with applications ranging from noise cancellation in voice communication systems to audio restoration in archival recordings.
### Emotion and Sentiment Analysis
Analyzing emotions and sentiments conveyed through audio signals has gained substantial interest. Machine learning algorithms, particularly those based on deep neural networks, can classify and recognize emotions from speech, music, or other audio data. These advancements have opened doors to various applications, such as sentiment analysis for call center monitoring, emotional speech synthesis, and personalized recommendation systems based on mood preferences.
### Real-time Audio Processing
Efficient real-time audio processing is crucial for applications like voice assistants, audio transcription services, and live audio streaming platforms. ML techniques, including online learning and lightweight neural network architectures, have made real-time audio processing more accessible and feasible. These models can perform tasks like speech recognition, speaker diarization, and audio classification with minimal latency, ensuring seamless user experiences.
### Conclusion
The intersection of AI, ML, and audio has given rise to groundbreaking advancements, transforming how we interact with and perceive sound. From improved speech recognition systems to AI-generated music and enhanced audio synthesis, the state of the art in AI and machine learning for audio is pushing the boundaries of what is possible. As technology continues to advance, we can expect further innovations in audio-related applications, enabling richer and more immersive auditory experiences for diverse domains and industries.
At Synervoz, this is all in our wheelhouse. From cramming ML models into tight constraints (like tiny hardware), to connecting them into user facing apps for iOS, Android, and desktop applications — we have an existing suite of tools and the team necessary to get your ML or AI project launched. Get in touch via
[Get In touch](/contact)
---
# Exploring the Frontiers of Neural Audio: Insights from ADCx
> Explore the frontiers of neural audio, from Neural DSP optimization and real-time inferencing with RTNeural to PyTorch and TensorFlow-based audio models. Learn how to implement neural DSP chaining, frequency biasing, and advanced audio separation techniques to push the boundaries of AI-driven sound processing. Start building the future of neural audio today.
In a recent presentation at ADCx, Kieran Coulter, Senior Engineer and Lead Architect at Synervoz, delves into neural audio digital signal processing (DSP), providing particular insights into the challenges of optimizing neural audio processors in practical applications. **With a focus on the neural audio landscape and real-time performance, Coulter offers a comprehensive overview of the challenges and opportunities in the area.**
* Coulter discusses the tools and frameworks commonly used in designing neural audio models, including PyTorch, Tensorflow and the RTNeural inferencing toolkit.
* He also presents a workbench of familiar neural DSPs Spleeter and Basic Pitch, showcasing the quantifiable improvements achieved and discussing practical implications of neural DSP chaining.
* Finally, Coulter introduces Neural Player, an innovative application that synchronizes audio with extracted stem MIDI playback, enabling users to appreciate the results of neural audio processing in an intuitive manner. He concludes with a glimpse into future areas of improvement, including introducing biases for target frequency ranges and the integration of neural audio solutions into consumer applications like media players and show control.
You can watch the presentation below.
[Play](https://youtube.com/watch?v=P50NTedJs1A)
[Get In touch](/contact)
---
# Hardware Companion Apps Will Benefit From AI: Reducing App Fatigue for a Seamless User Experience
> Discover how AI-powered hardware control is transforming audio devices with real-time processing, smart configuration, and low-latency solutions. Learn how AI-driven device management and voice-controlled interfaces are shaping the future of interactive audio applications. Explore the possibilities. AI-powered hardware control, Voice-controlled hardware interfaces, AI-driven device management, AI in audio hardware, voice activity detection python, python voice activity detection, webrtc voice activity detection, Voice assistants for audio devices, Smart audio configuration, AI-enhanced sound management, Real-Time Communication and AI, Real-time audio processing with AI, AI in live audio streaming, Interactive audio applications, Low latency audio solutions, audio latency test, sound latency test, latency audio test
### **App Fatigue: A Barrier for Hardware Providers**
The promise of app-based control has been a game-changer for many products, from soundbars and thermostats to home security systems. However, consumers often skip downloading companion apps, viewing them as just another item on a crowded phone. This reluctance can limit their experience and prevent them from accessing advanced functionalities that make their device shine.
### **The Opportunity: Voice-Controlled Hardware**
With **AI-driven improvements in voice control**, smart assistants can do much more than answer simple questions—they can execute complex commands that interface directly with hardware apps. This evolution is especially valuable for devices with intricate features, like soundbars with **spatial audio settings, multi-room audio management, and advanced equalization controls**. For example:
* Instead of navigating numerous sliders and options, you could say, “Hey Siri, turn down the music, increase the volume on the video call, and direct my friend’s voice through the back speakers.”
* AI can simplify tasks like **multi-room audio control** by handling commands such as, “Disconnect all speakers except the living room,” or “Set up different audio sources in each room.”
With AI, users can access the full potential of their devices through natural language, turning complex configurations into simple spoken requests.
### **A New Era for Hardware Manufacturers**
For hardware manufacturers, this shift represents a **new frontier in user experience**. By integrating their systems with voice assistants, manufacturers can reduce dependence on standalone apps. Instead of spending time building intricate app interfaces, developers can focus on **integrating controls directly into smart assistant ecosystems**. The result? More intuitive, hands-free user experiences that can enhance customer satisfaction and loyalty.
### **Realizing the Full Potential of AI and Hardware Integration**
As AI becomes more sophisticated, it can handle layered commands and context, allowing users to engage with their hardware seamlessly:
* **Contextual Awareness**: Smart assistants will learn usage patterns, automatically adjusting settings to fit preferences. For example, they could remember that you prefer movie soundtracks at lower volumes in the evening or that your family uses different audio setups based on time of day.
* **Multi-Device Coordination**: AI-powered assistants will soon manage several connected devices at once. Imagine asking for a “quiet mode” that lowers music volume, pauses notifications, and redirects calls to another room.
As AI transforms hardware management, it enables devices to deliver more value without overwhelming users with apps or intricate controls. For hardware manufacturers, embracing this change will not only address app fatigue but also unlock new potential for richer, more intuitive user experiences.
[Get In touch](/contact)
---
# Helix by Figure AI: A Practical Leap Toward Everyday Humanoid Robots
> Explore how Figure AI’s Helix uses real-time embedded audio and multimodal AI to power natural humanoid robot interactions. Audio innovation opportunities relate to advanced real time audio features—such as interruptibility, conversational memory, and continuous background listening with energy efficiency.
One of the most fascinating applications of AI is humanoid robots. As audio specialists, we're particularly interested in the audio systems onboard, and these systems are evolving rapidly. Figure AI’s Helix model represents a shift in both humanoid robot capabilities and how audio is handled. It combines visual understanding, natural language comprehension, and physical control into a unified system. The result? Robots that follow verbal instructions and perform physical tasks, all while adapting to new environments. Here’s a quick overview, as well as how audio factors into such systems.
### A Two-Brain System: Language + Motion
Helix is structured as a dual-model system:
* System 2: A 7-billion-parameter multimodal model that handles high-level reasoning. It processes RGB-D (includes depth) camera input and speech commands to understand intent.
* System 1: An 80-million-parameter motion model that handles joint-level execution across 35 degrees of freedom—fingers, wrists, torso, and head—at 200Hz. This system is optimized to be super fast.
The models exchange information through shared latent representations, allowing abstract instructions like “put the milk in the fridge” to flow smoothly into real-world movements. System 2 allows the robot to “think slow” while System 1 can “think fast” and adjust in real time.
### Vision-Language-Action Integration
Most robots follow a rigid pipeline—first they perceive, then plan, then act. Helix trains all these steps together in one neural network using human demonstration data. This structure allows it to handle previously unseen objects by grounding language (e.g., “soft,” “slippery”) to visual features learned at scale.
For example, given the command “Pass the cereal box to the other robot,” Helix maps that instruction to both a visual search pattern and a series of handoff actions—without hardcoding.
### Embedded and Efficient
Helix doesn’t rely on the cloud. It runs entirely on embedded GPUs (Jetson Orin), using 4-bit quantization and model parallelism to stay under 60W. This design delivers sub-100ms control loop latency—critical for responsive, safe operation around humans—and makes Helix viable in environments with poor connectivity.
### Real-Time Audio Processing in Helix
Audio is central to Helix’s ability to understand and respond to human intent. The system continuously processes spoken commands through onboard microphones using a speech recognition pipeline integrated into the multimodal model.
**Key Characteristics:**
* Embedded Speech-to-Text (STT): Likely built on quantized transformer-based models for latency and efficiency.
* Multimodal Fusion: Audio is fused with visual data to disambiguate intent. For example, “Give me that” is grounded visually via attention over camera input.
* Low-Latency Feedback: Sub-100ms audio command-to-action pipeline enables natural interaction pacing for tasks like collaboration, correction, or clarifying questions.
**Potential Areas for Future Improvement:**
We're speculating here, but there's likely interesting work to be done including:
* On-device speaker diarization and emotional tone detection to improve multi-human interaction.
* Noise robustness in environments like kitchens or workshops.
* Bidirectional interaction with real-time voice synthesis for robots that can ask clarifying questions or explain actions.
As Helix evolves, more advanced real-time audio features—such as interruptibility, conversational memory, and continuous background listening with energy efficiency—will be key to scaling up interaction complexity.
We will be watching the space closely.
[Get In touch](/contact)
---
# How AI Personas Will Start Participating in Voice and Video Calls Among Friends
> Focused on software for interactive voice and video chat projects with complex audio requirements.
### **AI Personas: Adding Value to Social Conversations**
AI personas embedded in social calls can serve several useful functions, including:
* **Settling Debates:** Instead of friends arguing endlessly, the AI can pull up relevant facts or provide quick answers from the web to resolve disputes.
* **Making Plans:** If friends are unsure about where to meet or what to do, the AI can **fetch information about restaurants, events, and activities**, suggesting ideas based on preferences and availability.
* **Spontaneous Humor:** By understanding the flow of conversation, AI agents can tell **jokes or share memes** at the right moments, contributing to the fun without being intrusive.
* **Helping with Creativity:** When brainstorming activities or vacation ideas, the AI can offer **suggestions or resources**, making group planning sessions more efficient and enjoyable.
### **Context-Aware Conversations: Understanding Relationships**
To truly fit into social settings, AI personas will need to **learn the context** of each friend group they interact with. For instance, they may need to understand inside jokes, shared history, or recurring interests without overstepping boundaries. AI-powered solutions such as **Switchboard SDK** can enable these advanced interactions, allowing developers to create contextual AI personas tailored to specific groups.
However, **sandboxing these interactions** is essential to ensure privacy. Each AI persona must be restricted to the particular group it interacts with, avoiding **leakage of private information** or unintended disclosures. If an AI joins multiple friend groups, it should maintain separate contexts to prevent, for example, secrets from one group being accidentally shared in another.
### **Use Case: AI Personas as Facilitators of Hangouts**
Consider a scenario where a group of friends is planning a weekend outing over a video call. The AI persona can:
1. **Search for nearby restaurants** matching the group’s tastes and book a reservation in real-time.
2. **Suggest events or concerts** based on shared interests or past activities.
3. **Help organize logistics**, such as coordinating schedules and transportation, with everyone’s availability in mind.
4. **Break awkward silences** by making light conversation or playing a funny video when the chat slows down.
These interactions make AI feel more like an integrated part of the group rather than just a tool, facilitating the natural flow of conversation while ensuring everyone is on the same page.
### **How Switchboard SDK Facilitates AI Integration**
**Switchboard SDK** makes these interactions easier to build by offering tools to **seamlessly integrate AI personas into voice and video platforms**. With **dynamic features like spatial audio**, these AI agents can even feel like they are physically present in the room, adding to the immersive experience.
### **Conclusion: AI Personas—New Friends in the Digital Age**
As AI personas evolve, they will move beyond functional roles to become active participants in social conversations, enriching our interactions with friends. By **understanding the nuances of human relationships** and being sensitive to privacy concerns, these digital companions will add convenience, humor, and creativity to group chats. Platforms like **Switchboard SDK** are paving the way for developers to build these experiences, ensuring that AI companions fit seamlessly into both social and collaborative settings.
In this exciting new world, AI agents will **enhance the way we communicate and engage** with each other—helping us plan, laugh, and bond with even more ease.
[Get In touch](/contact)
---
# How to Build a Karaoke App with Amazon IVS and Switchboard
> Focused on software for interactive voice and video chat projects with complex audio requirements.
Amazon’s Interactive Video Service (IVS) is a managed live streaming service for live streaming video and audio at scale. But what if you want to do more with that audio on device, before broadcasting it, or after receiving it? Or what if the audio from your Amazon IVS live stream is only one part of a more complex audio pipeline? Enter the [Switchboard SDK.](https://docs.switchboard.audio/)
The Switchboard SDK is a cross platform audio SDK that makes it easier to develop complex audio features and applications without needing to be a specialist in audio programming or C++. Building an application with advanced audio features can take months or longer, but using the Amazon IVS extension in the Switchboard SDK, that effort can be reduced to days or hours. The Amazon IVS extension in Switchboard makes it easy to build complex audio pipelines that can allow for Amazon IVS to work alongside features such as external media players, voice changers, stem separation, advanced noise filtering and other DSP, mixing, ducking, and handling various OS related audio issues, Bluetooth, and more.
Karaoke Apps are one of many use cases in which such audio pipelines are useful. In the rest of this article, we will walk you through a step by step process of building an Android karaoke app that combines Switchboard and IVS. Switchboard is used to apply various voice changing effects (such as pitch correction and reverb), while Amazon IVS is used to broadcast the resulting voice and music streams.
Find the tutorial's code on GitHub, along with its iOS version. Check out the live demo of the web app too.
## What you will learn
* How to create a real-time streaming experience with with Amazon IVS
* How to integrate the Switchboard SDK Extensions into your application
* How to test and apply voice changing effects from Switchboard SDK
* How to live stream your new voice to an audience using Amazon IVS
### Attributes
 AWS Level | Intermediate - 200\
 Time to complete | 60 minutes\
 Cost to complete | Free when using the AWS Free Tier\
 Prerequisites | - [AWS Account](https://aws.amazon.com/resources/create-account/)\
 Code Sample | Code sample used in tutorial on GitHub\
 Feedback | [Any feedback or issues](https://pulse.aws/survey/DEM0H5VW)?\
 Last Updated | [See tutorial](https://docs.google.com/document/d/1E3hP7ZUMKgHq7cVxHpZwnIraW8o5a_cNlp3J3TYfD2U)
## Solution Overview
Let's take a quick look at the high level solution overview in Figure 1. The Switchboard SDK is a versatile toolkit that streamlines audio app development across different platforms. It features a collection of AudioNodes—like players, recorders, and mixers—that interconnect within an AudioGraph. This graph operates via an AudioEngine, leveraging advanced platform-specific capabilities. The SDK also provides various [extensions](https://docs.switchboard.audio/nodes/) (nodes), which are wrappers around popular libraries, such as Amazon IVS. We will revisit each component in more detail in later steps.

### This tutorial consists of 3 parts:
* **Part 1** - Creating a real-time streaming app with Amazon IVS and SwitchboardSDK
* **Part 2** - Importing and applying voice changing effects
* **Part 3** - Testing your new found voice

[Play](https://youtube.com/watch?v=Au8eHYF2c3w)
[Go To Free Tutorial](https://community.aws/content/2bjOZXGNZtYebdF5GQvE5Tk1SK2/add-interactive-audio-to-amazon-ivs-live-streams-with-the-switchboard-sdk-karaoke-app-example)
[Get In touch](/contact)
---
# Interactive Audio for Fitness: Music + Talking for a Connected Experience
> Discover how interactive audio fitness applications are transforming workouts with immersive sound experiences, hands-free controls, and seamless music and voice integration. Learn how to build connected fitness solutions that enhance user engagement through social audio and real-time music sharing. Start creating next-gen fitness audio experiences today!
### **Different Scenarios**
Peloton with a Friend: You’re doing a virtual class at home, but instead of feeling alone, you can talk to a friend who’s taking the same class. Share the experience, cheer each other on, and make it more engaging.
Running with Headphones On: You’re out for a run, and a friend joins you. Instead of pausing to take your headphones off whenever you want to chat, you could talk seamlessly over your favorite running playlist.
Hiking with Blissful Playlists: Picture hiking through serene landscapes while sharing a curated playlist with friends. Talk through your headphones when inspiration strikes, without interrupting the music.
**The Promise of Switchboard**
These scenarios represent the future of interactive audio for fitness, and Switchboard SDK is here to make it happen. Our technology allows seamless mixing of music and voice, enabling users to stay connected without sacrificing their audio experience.
In fact, we’ve already developed an app that supports this use case, available as a white-label solution for developers. It integrates music sharing, real-time voice communication, and hands-free controls to ensure a seamless fitness experience.
**Why This Matters**
Interactive audio transforms fitness from a solitary activity into a shared journey. It enhances motivation, builds connections, and creates memorable moments—all while keeping the focus on the activity itself. Whether you’re on a treadmill or a mountain trail, Switchboard makes it easier to stay in sync with friends while staying in the zone.
Developers and fitness brands can now bring these features to their users, creating next-level audio experiences that blend motivation, connection, and convenience. Interactive audio isn’t just the future of fitness—it’s the key to making workouts more social, engaging, and fun.
[Get In touch](/contact)
---
# Multiplayer Gaming Audio Challenges: Navigating Sound in Competitive and Social Play
> Explore the biggest audio challenges in multiplayer gaming, from low-latency voice communication and 3D positional audio to AI-driven noise suppression and cross-platform performance. Learn how to integrate real-time voice chat, VoIP APIs, and game audio middleware like Vivox and WWise. Start optimizing your game's audio experience today.
### **Industry Leaders and Their Audio Solutions**
Vivox, owned by Unity, is a widely SDK integrated into games like League of Legends, PUBG, and Fortnite. It offers** in-game voice chat** with low latency and 3D positional audio. **Discord**, on the other hand, is a separate app, so it doesn’t take advantage of in-game features and positional audio, though Discord seems to be making further inroads to offer a more comprehensive in-game solution. Both platforms have set high standards for in-game audio, yet challenges remain for developers building games or apps that operate alongside them.
### **Audio Challenges in Multiplayer Games**
1. **Background Noise and Audio Leakage: **One common issue in multiplayer gaming is **microphone bleed**—the leakage of background sounds like in-game music, which can disrupt communication. Filtering out unwanted sounds without affecting game performance is complex, especially with players using different setups. Game developers are now exploring **noise suppression algorithms** and AI-driven solutions to isolate voice from background noise, but it’s often the case that these let all human voice detection pass through, a problem for music with lyrics or other people talking in the background, for example. Echo suppression solutions and specific speaker identification are alternatives that can be considered in parallel for an optimal user experience.
2. **Performance Constraints: **Processing high-quality audio and ML-based noise filters or voice changers alongside graphics-intensive gameplay can drain system resources, causing fps drops, latency, and other issues. **Mobile devices** face even greater constraints due to limited CPU and battery life. In these scenarios, real-time voice communication can lag or drop out. Solutions like **lightweight audio codecs** and adaptive audio quality adjustments help, but the balance between quality and performance remains a challenge.
3. **Integration Difficulties: **Tools like **WWise** provide sophisticated options for in-game sound design, while **Vivox** is ideal for real-time voice. Combining these tools might seem straightforward, but technical issues often make it more challenging. Latency issues, audio balancing, and platform-specific limitations require careful handling to ensure a smooth experience for players.
### **Why Audio Should Be a Priority**
Many game developers underestimate the importance of audio, viewing it as secondary to graphics or gameplay mechanics. However, poor audio can disrupt player engagement and even lead to player churn. **A well-integrated audio experience**—including clear voice comms, well-mixed in-game sounds, and smooth performance across platforms—can significantly enhance gameplay immersion and keep players engaged longer. Not only that, but audio can actually impact the player’s performance during the games, especially while playing first person shooter games like Valorant and CS: GO.
### **Innovations and Future Solutions**
**Synervoz** has addressed these audio challenges in gaming use cases through the provision of its products and services. Switchboard has streamlined integration with various audio SDKs including Vivox, enhancing audio clarity and synchronization without compromising game performance. By focusing on high-quality audio and flexible integration, Synervoz empowers developers to create **immersive, responsive multiplayer experiences** that rival in-person interactions.
The audio landscape in multiplayer gaming is evolving, and the metaverse is following a similar trajectory. Developers who recognize the importance of audio and prioritize it will be rewarded with improved user engagement and retention.
[Get In touch](/contact)
---
# On-Device AI’s Quiet Superpower: Resilience in a Memory-Constrained Future
> Voice AI isn’t just improving interfaces. It’s reshaping online presence by enabling real-time, drop-in interaction, shifting the internet from passive consumption back toward shared moments, coordination, and genuine human connection.

We’re entering a phase where AI demand is growing faster than global memory supply. DRAM and high-bandwidth memory (HBM) are increasingly monopolized by hyperscalers, large model training, and GPU clusters. Even when compute exists, **memory-heavy workloads are becoming harder to schedule predictably and more expensive to run**. That shows up as higher cloud bills, throttling, spot instance volatility, and occasional outright unavailability.
In that environment, applications that require constant cloud inference become brittle. Applications that can function locally—even in a degraded mode—become resilient.
## Why memory is the real bottleneck
AI is not compute-bound anymore; it’s **memory-bound**. Large models require tens to hundreds of gigabytes of RAM just to load efficiently, and even “small” inference workloads scale memory linearly with concurrency. As more products ship AI-native features, cloud providers are forced to ration high-memory instances or price them aggressively.
This isn’t theoretical. We already see:
* Memory-optimized cloud instances costing multiples of CPU-only equivalents
* Capacity constraints during peak demand windows
* Hyperscalers pre-allocating memory supply for internal use
If your product assumes “the cloud is always there,” you’re implicitly assuming **memory abundance**. That assumption is getting weaker every year.
## What on-device AI changes
On-device models flip the dependency graph. Instead of your app depending on remote memory availability for every interaction, **memory is prepaid and local**. The device already owns the RAM; your marginal cost per inference is effectively zero.
That doesn’t mean abandoning the cloud. It means **designing for continuity** when cloud compute is slow, unavailable, or simply too expensive to use for every request.
## Two concrete examples
### 1. Voice assistants and real-time speech features
A cloud-only voice assistant must stream audio, wait for inference, and pay for memory-heavy models per session. When connectivity drops—or cloud costs spike—the feature degrades or disappears. An on-device speech stack (VAD, transcription, basic intent) keeps core functionality alive offline, using the cloud only for optional enrichment. The result isn’t just lower latency; it’s **graceful survival under constraint**.
### 2. Navigation and situational awareness
AR navigation, driver assistance, or accessibility tools often require continuous perception. Sending frames to the cloud is fragile: tunnels, dead zones, and congestion break the experience. On-device vision models keep working regardless of network conditions, while cloud services remain additive rather than essential. In a memory-constrained cloud environment, this distinction becomes the difference between “works” and “doesn’t.”
## The strategic takeaway
On-device AI is not just a performance optimization or a privacy feature. It’s a **hedge against infrastructure fragility**.
As memory shortages intensify and cloud economics shift, products that assume infinite remote compute will face rising costs and reliability risks. Products that can operate locally—falling back to the cloud only when it makes economic sense—will be more predictable, more resilient, and ultimately more competitive.
In the next phase of AI, **resilience may matter more than raw model size**.
## Ready to Start Building?
[Explore the Switchboard SDK](https://switchboard.audio)
---
# Overcoming Challenges in Audio Software Engineering: Mastering the Sound Waves
> Explore the challenges of audio software engineering, from low-latency and real-time audio processing to playback optimization and distortion prevention. Learn how to enhance audio responsiveness and build high-performance sound applications. Start optimizing your audio software today.
Audio software engineering is an intricate field that combines technical expertise, creative problem-solving, and a passion for delivering exceptional auditory experiences. Behind the scenes, audio software engineers face numerous challenges that require them to navigate through the complex realm of real-time processing, compatibility, signal processing algorithms, user interface design, and more. In this article, we'll explore the biggest problems faced by audio software engineers and how they overcome these hurdles to create cutting-edge audio software solutions.
1. **Real-Time Processing: **The Symphony of Low Latency\
When it comes to audio software engineering, real-time processing is the backbone of applications such as music production, live sound, and gaming. Achieving low latency and high efficiency in real-time audio processing presents a formidable challenge. Audio software engineers meticulously fine-tune their algorithms and optimize their code to ensure seamless audio playback and responsiveness, providing users with a fluid and immersive experience.
2. **Compatibility and Cross-Platform Support: **Uniting Sound across Systems\
In today's diverse technological landscape, audio software engineers must develop applications that seamlessly traverse multiple operating systems and hardware configurations. This necessitates ensuring compatibility and consistent performance across platforms like Windows, macOS, Linux, iOS, Android, and more. Meeting the demands of various environments requires rigorous testing, meticulous code implementation, and adaptability to different system architectures.
3. **Signal Processing Algorithms:** Mastering the Art of Sonic Manipulation\
The core of audio software engineering lies in designing and implementing high-quality signal processing algorithms. These algorithms drive audio synthesis, effects processing, and audio analysis, enabling users to create and shape their sonic landscapes. Audio software engineers strive to strike a delicate balance between computational efficiency and audio fidelity, employing their expertise in digital signal processing to overcome challenges such as complexity, accuracy, and maintaining optimal audio quality.
4. **Performance Optimization:** Orchestrating Smooth Audio Execution\
Processing large amounts of audio data in real time can place a significant burden on system resources. Audio software engineers embark on the arduous task of optimizing their software's performance to ensure efficient CPU utilization, memory management, and disk I/O. Through meticulous profiling, algorithmic enhancements, and architectural optimizations, they orchestrate smooth and fluid audio execution, allowing users to work seamlessly with their audio projects.
5. **User Interface Design:** Harmonizing Functionality and User Experience\
Intuitive and user-friendly interfaces are paramount in audio software engineering. Audio software engineers must design interfaces that strike a harmonious balance between functionality, ease of use, and aesthetic appeal. Navigating complex audio processing tasks necessitates well-thought-out controls, parameters, and visual feedback that empower users to unleash their creativity without being hindered by a steep learning curve.
6. **Audio Quality and Artifact Minimization:** Composing Sonic Perfection\
Delivering high-quality audio output while minimizing artifacts and distortions is an ongoing pursuit for audio software engineers. They dedicate themselves to tackling challenges such as aliasing, phase cancellation, noise, and distortion, ensuring that audio enthusiasts and professionals can enjoy pristine sound reproduction. By leveraging their understanding of digital audio theory and employing advanced algorithms, they strive to compose sonic perfection.
7. **Audio File Formats and Standards:** The Harmonic Convergence of Compatibility\
The audio landscape encompasses a myriad of file formats and industry standards. Audio software engineers grapple with the intricacies of supporting various formats, ensuring seamless import/export functionality, and compatibility with widely used formats like WAV, MP3, FLAC, or AAC. By staying abreast of the latest standards and leveraging robust audio libraries and APIs, they ensure that users can effortlessly work with audio assets in their preferred formats.
8. **Testing and Bug Fixing:** Tuning the Melody of Stability\
Rigorous testing and bug fixing are essential steps in the audio software development process. Audio software engineers conduct thorough testing to ensure software stability, reliability, and compatibility across diverse environments. Through meticulous debugging, logging, and error handling, they fine-tune the melodic composition of their software, ensuring that it can withstand the rigors of real-world usage.
9. **Keeping up with Technological Advancements:** Riding the Wave of Innovation\
The audio software industry is a rapidly evolving domain, with new technologies and techniques emerging incessantly. Audio software engineers need to stay at the forefront of advancements such as machine learning for audio processing, virtual reality (VR) audio, and spatial audio. By embracing innovation and continuously expanding their skill sets, they unlock new creative possibilities and provide users with groundbreaking audio experiences.
10. **Collaboration and Integration:** The Symphony of Teamwork\
Audio software engineers often collaborate with audio designers, musicians, and game developers, working as part of larger teams to create cohesive audio solutions. Effective collaboration and integration of their software with other tools and workflows demand strong communication skills, empathy for other disciplines, and the ability to work harmoniously as a team. Together, they orchestrate a symphony of creativity, delivering comprehensive audio experiences to end-users.
Audio software engineering presents an array of challenges that demand technical acumen, creativity, and an unwavering dedication to sonic excellence. Through their mastery of real-time processing, compatibility, signal processing algorithms, user interface design, audio quality, and more, audio software engineers continue to push the boundaries of what is possible in the world of sound. By overcoming these challenges, they enrich our lives with immersive audio experiences, empowering artists, enthusiasts, and professionals to unleash their sonic imaginations.
Synervoz is an innovation & software development studio focused on audio, entertainment and online collaboration. If you’re struggling with any of the above problems, chances are we can help. Get in touch via
[Get In touch](/contact)
---
# Slack 2.0: What We’d Love to See
> Focused on software for interactive voice and video chat projects with complex audio requirements.
### **Slack’s Huddles: A Step Forward**
With **Huddles**, Slack took a step toward casual **drop-in audio**. Built in partnership with **Amazon Chime**, Huddles improved Slack’s audio stack, making it easier to initiate conversations without the formality of a scheduled call. But as we learned with Switchboard, there’s a lot of unrealized potential.
### **What We’d Love to See in Slack 2.0**
Here’s our wish list for a truly immersive, collaborative Slack experience:
1. **More Interactive Channel Types**Imagine channels where teams can **watch videos together**, **listen to music**, or even **play games** directly within Slack. These channels could be designed specifically for different types of collaboration, whether it’s brainstorming over music or catching up with a video.
2. **Enhanced Audio and Video Integration**Audio and video channels could benefit from more **advanced features**, like real-time audio spatialization or smart ducking (reducing background audio or a shared media player when someone speaks). These features would enhance virtual presence, making conversations feel more organic and in-the-moment.
3. **Metaverse-Ready Features**While **working in VR** might seem futuristic, the rise of immersive digital spaces is undeniable. Picture Slack channels as virtual rooms, where teams can “meet” in shared 3D environments. Simple, customizable spaces for brainstorming or virtual coffee chats could help bring a sense of presence to remote teams, an experience we are building with **Switchboard’s Ronday** app.
### **Bridging the Physical Divide**
As a remote team ourselves, we deeply understand the desire to bridge the gap between virtual and in-person communication. Experimenting with **new modes of communication** is part of our daily routine, as we continually use Switchboard’s example apps to enhance team collaboration. While Slack has been integral in the digital workspace, the next evolution will require deeper integrations, bridging audio, video, and virtual spaces.
[Get In touch](/contact)
---
# Social Voice Will Drive Growth in All Product Categories
> Shared experiences online often fail because timing doesn’t align. AI agents will bridge that gap, detecting availability and using voice to spark spontaneous, real-time connection.

What’s better than watching a funny video on YouTube? Watching it with friends.
The same goes for TikToks, live concerts, game streams, multiplayer games, music sessions, or just scrolling through memes. Humans are wired for shared experiences—and the internet is finally catching up.
But it’s still really hard to know when someone else wants to share that experience. Not because your friends aren’t online. Not because the tools don’t exist. But because the timing doesn’t align.
The window of “I’m bored and available” is short, and people aren’t great at declaring those moments.
That’s where AI agents come in. AI Agents Will Solve the Coordination Problem.
The problem isn’t “How do I watch this show with my friend?”
It’s: “When is the right time for both of us?”
AI agents will soon:
* Monitor context (calendar, presence, ambient audio, current activity).
* Detect shared availability.
* Nudge you into experiences spontaneously—in real time.
This turns every app into a hangout opportunity, and every product into a social catalyst.
## Why Voice Will Be the Glue
While video is heavy and chat is slow, voice is ambient, fast, and deeply human. It:
* Creates intimacy.
* Requires little attention or setup.
* Can run in the background while people play, scroll, or work.
* Is baked into almost every modern device.
Voice is the lowest-friction gateway into shared experiences. It feels spontaneous. It keeps people connected. It drives retention and stickiness like nothing else.
Every product can benefit from real-time social features:
* Entertainment → “Watch or listen together with voice connected."
* Trading apps → “Jump on a quick voice chat with your r/wallstreetbets friends before you buy.”
* Fitness apps → “Go on a run and listen to music together, even if you’re across the country.”
* eCommerce → “Shop with your partner, live voice while browsing.”
* Social→ “Use your voice assistant to connect you in shared experiences at the right moments."
The goal is no longer just engagement. It’s co-engagement.
## Platform Builders Already See It
Mark Zuckerberg has spent the better part of two decades building toward a vision of the metaverse as social infrastructure. And Elon Musk’s merger of X and xAI shows he gets it too: content + presence + AI = the future of interaction.
The companies that win will be the ones that treat “togetherness” as a core feature, not a bolt-on. If you're building:
* Consumer electronics → Bake in voice-first presence layers (think Smart Speaker meets Discord).
* Streamers → Make watch together the default, not an edge case.
* AI agents → Focus on who to connect and when, not just what to say.
* APIs and SDKs → Give developers the tools to create cross-app shared moments easily.
## The Social Operating System Is Coming
Once AI agents can coordinate our free time and bring the right people together at the right moments, the internet will change again. The next breakout products will be the ones that:
* Know when to connect us
* Make it seamless to join in
* Let us experience everything together, in real time
---
# Switchboard is to Audio what Unreal and Unity are to Game Development
> Discover how Switchboard is revolutionizing audio development with a modular framework akin to game engines like Unreal and Unity. Learn how to implement real-time DSP effects, audio graph creation, and interactive audio applications for gaming, VR, and voice interfaces. Start building the future of audio technology today.
### **Switchboard is to Audio what Unreal and Unity are to Game Development:**
Around 30 years ago, before there were game engines as a service, developers spent countless hours building custom game engines, a task that was not only time-consuming but also required highly specialized knowledge. This scenario mirrors the current state of audio software development—fragmented, time-consuming, and complex enough to require specialized expertise. But just as Unity and Unreal Engine transformed game development, Switchboard is poised to transform audio software development.
### **The Era Before Game Engines**
Before Unity and Unreal Engine, game developers had to create everything from scratch. Graphics rendering, physics calculations, and input management were just the tip of the iceberg. Each game was an island, with proprietary code bases that made reuse and sharing among developers difficult, if not impossible. This not only slowed down development time but also increased costs significantly, restricting innovative game development to those with substantial resources.
### **The Game-Changing Arrival of Unity and Unreal**
The introduction of Unreal (1998) and Unity (2005) provided developers with ready-to-use, highly sophisticated tools that abstracted the complexities of game mechanics, rendering, and physics. They democratized game development, enabling developers at all levels to turn their creative visions into reality without reinventing the wheel for each new project.
### **Switchboard: The Unity/Unreal of Audio Software Development**
Just as Unity and Unreal simplified game development, Switchboard simplifies audio software creation. Switchboard provides a comprehensive suite of audio tools and building blocks—from voice changers and synchronization to advanced DSP effects. What once required specialized knowledge in audio processing and software engineering can now be accomplished with modular ease.
Switchboard's core feature, the ability to build complex audio graphs, is akin to assembling a game scene in Unity. Developers can drag and drop different audio components to create sophisticated audio experiences, whether for applications in real time communication, gaming, virtual reality, or media and entertainment.
### **Why Switchboard Matters Now**
As voice interfaces and audio interactions become increasingly integral to technology—from smart homes to interactive storytelling—there's a growing need for an efficient way to develop complex audio solutions. Switchboard meets this need head-on, offering developers the tools to innovate and streamline audio software development.
Just as Unity and Unreal Engine have become the backbones of game development, Switchboard aims to be the foundational platform for audio software development. It’s time to stop reinventing the audio engine and start building on one that’s already as powerful as it gets.
Visit us at [*switchboard.audio*](https://switchboard.audio) to learn more about how we can empower your audio development journey.
[Get In touch](/contact)
---
# Unlocking the Full Potential of AI Agents with Switchboard: Going Beyond the API
> Explore how Switchboard goes beyond traditional APIs with real-time audio manipulation, customizable pipelines, and low-latency processing. Learn how to integrate modular audio processing nodes, AI-driven voice assistants, and advanced echo cancellation techniques for seamless speech-to-speech applications. Start building next-gen audio solutions today.
### **Unlocking the Full Potential of AI Agents with Switchboard: Going Beyond the API**
AI agents are becoming increasingly sophisticated and readily available to incorporate into new products and use cases. One of the latest developments is OpenAI's Realtime API, which enables speech-to-speech applications, offering exciting possibilities for dynamic interactions. But while promising, it still leaves many use cases on the table, especially for developers who want greater control and flexibility.
That’s where Switchboard comes in, offering a more powerful framework for building AI-driven applications, particularly for audio-based AI agents. In this post, we’ll explore how Switchboard fills in the gaps left by current API solutions, opening up a world of opportunities for developers and businesses alike.
### **The Promise of OpenAI’s Realtime API**
OpenAI’s Realtime API is a significant milestone in the realm of AI agents. It allows developers to create responsive applications that convert speech to text, process it using language models, and return synthesized speech in real-time. Imagine an AI assistant you can speak to naturally, with near-instantaneous responses. This is especially useful for applications like voice assistants, customer service bots, and other conversational agents.
However, while the Realtime API brings ease of use and accessibility, it also comes with limitations. For instance, what if your use case requires more than what a cloud-based API can offer? What if you need something that operates entirely on-device or on-premise? Or, perhaps, you want to experiment with different language models and text-to-speech solutions to find the perfect fit for your product?
### **When APIs Fall Short**
Here are a few scenarios where an API like OpenAI’s Realtime API might fall short:
* **On-premise language models:** In some cases, you may want your AI agent to run on prem, either for privacy reasons or to reduce latency. This is common in industries like healthcare or finance, where data security is paramount. Relying on cloud-based APIs is not always an option in these cases.
* **Multiple LLMs in parallel:** What if you want to quickly audition different LLMs to compare their responses? Or build a solution to talk to all of them in parallel? For developers who need this flexibility, relying on a single cloud provider’s API might not cut it.
* **Embedded solutions in hardware:** For developers working on hardware solutions, such as IoT devices or edge computing systems, integrating a cloud-based AI service isn't always feasible. Sometimes you need an AI agent that operates directly on the hardware, with no reliance on external APIs.
* **Custom Text-to-Speech (TTS) solutions:** What if you want to experiment with different TTS providers, like Cartesia or Eleven Labs, or to use an in-house technology? APIs can limit your flexibility in trying out different audio solutions to find the best one for your needs.
* **Advanced audio control:** Many real-world applications require more than just basic speech-to-text and text-to-speech functionality. You might need features like noise suppression, voice changers, or the ability to integrate your AI agent into a voice or video call. This level of control isn’t possible with many out-of-the-box API solutions.
### **Enter Switchboard: The Power of Flexibility**
Switchboard is designed for developers who need more than what current APIs can offer. With Switchboard’s audio framework, you can build sophisticated audio pipelines—known as *audio graphs*—that give you unparalleled flexibility and control over your AI agent's capabilities. Here’s how Switchboard solves the challenges mentioned above:
* **On-device or on-premise deployment:** Switchboard allows you to deploy language models and audio processing modules on-device or on-premise, providing the security and low-latency benefits of local processing. Whether you're working on a consumer device or an enterprise solution, Switchboard's framework is adaptable to your architecture.
* **Multiple LLMs in parallel:** With Switchboard, you can integrate multiple language models into your pipeline and compare their responses in real-time. This is ideal for experimenting with different LLMs and finding the one that delivers the best performance for your specific use case.
* **Hardware integration:** Need to embed your AI agent in hardware? No problem. Switchboard can operate independently of external APIs, allowing you to build a fully self-contained solution that runs directly on your hardware, whether it’s a smart speaker, a wearable, or an IoT device.
* **Custom Text-to-Speech options:** With Switchboard, you’re not locked into any one TTS provider. You can easily swap between providers like Cartesia, Eleven Labs, or your own proprietary technology. This flexibility makes it easy to fine-tune the audio experience to match your product’s unique needs.
* **Full control over the audio pipeline:** One of Switchboard’s standout features is its ability to handle complex audio processing in real-time. You can add noise suppression, voice changers, or even integrate your AI agent into a voice or video call with ease. All of this is possible within the same framework, giving you full control over the entire audio pipeline.
### **The Future of AI Agents**
As AI agents become more ingrained in our daily lives, the demand for flexibility, control, and customization will only increase. While APIs like OpenAI’s Realtime API provide a solid starting point, they are just one piece of the puzzle. For developers who need to push beyond the limitations of cloud-based solutions, Switchboard offers a versatile and powerful alternative.
With Switchboard, you can create AI agents that are not only more responsive and customizable but also capable of handling the advanced audio requirements of real-world applications. Whether you're building a voice assistant, a customer service bot, or an embedded AI solution, [*Switchboard*](https://switchboard.audio/) provides the tools to make it happen.
[Get In touch](/contact)
---
# This is a Test Post Page With a Very Long Title that will Wrap
> This is the description for the blog post, it will be longer and go in meta data.

Lorem ipsum dolor sit amet, consectetur adipiscing elit. Vivamus efficitur, est eu sollicitudin fringilla, elit tellus tempus augue, et posuere odio enim in nibh. Etiam eget velit eu sem fermentum molestie. Sed sit amet convallis tellus. Pellentesque aliquam vitae magna sed imperdiet. Morbi accumsan ultricies quam eu venenatis. Ut vestibulum sed ex eu aliquet. In ac massa ac magna faucibus accumsan. Quisque faucibus accumsan erat, nec aliquam enim ornare non. Integer ornare tempor felis non rutrum. Duis a accumsan eros. Aenean pretium sapien at erat efficitur, vel condimentum massa gravida. Vestibulum quis sem volutpat, blandit risus sed, imperdiet leo. Aliquam vel dui enim.
Duis non nunc dui. Donec ultrices dapibus purus, vitae iaculis ante accumsan eget. Pellentesque et ante nec leo lacinia posuere. Donec sapien mi, tincidunt ut nisl non, faucibus condimentum libero. Fusce posuere purus in neque fringilla cursus. Sed tempor cursus justo a semper. Aliquam consequat ultricies sapien, a egestas libero varius eu. Pellentesque ac augue aliquam, faucibus purus eu, posuere tellus. Mauris quis lorem posuere, posuere ligula nec, gravida massa. Aenean et arcu quis turpis eleifend molestie. Duis viverra tempus nunc, quis accumsan dui tempus ac. Sed augue leo, tincidunt ac dignissim non, egestas quis neque.
Aliquam lectus turpis, suscipit ac orci ac, rhoncus imperdiet massa. Maecenas et ultricies magna. Ut ac elit placerat, consequat tortor eu, pulvinar justo. Nam efficitur, mi id lacinia tincidunt, orci leo fringilla sapien, ac volutpat tellus quam nec mi. Etiam convallis sodales urna ut dapibus. Donec ut leo in sem pretium fringilla. Donec sodales suscipit turpis id sagittis. Curabitur sagittis cursus orci non sodales.
---
# The AI Race Is About Distribution, Not Benchmarks
> Focused on software for interactive voice and video chat projects with complex audio requirements.
## Where the AI Race Is Actually Headed
Foundational model capabilities will continue to matter—but what’s going to really matter is how quickly those capabilities get turned into things people want to use. And that means we’re entering the era of interface velocity.
The next breakout experiences will likely come from companies that ship fast, experiment faster, and bridge the gap between new model capabilities and daily life. Here’s where that frontier is unfolding:
## 1. Real-Time, Multimodal Communication
We're on the edge of AI that can:
* Hold voice conversations in real time
* Understand and react to what's happening on your screen
* Screenshare, co-browse, or narrate as you interact
* Combine voice, vision, and touch into one fluid conversation
Early demos (like OpenAI’s GPT-4o) hint at what’s coming—but the race is on to make this usable, delightful, and ubiquitous. Whoever gets this right will redefine how we interact with devices and each other.
## 2. Agent-to-Agent Social Coordination
Soon, your AI won’t just help you—it’ll talk to other AIs that belong to your friends, coworkers, or family. Imagine:
* Coordinating hangouts or work sessions between AI assistants
* Planning trips, syncing calendars, suggesting mutual times
* Sharing relevant data across trusted AI networks
This creates a layer of persistent social presence—without constant human micromanagement. And whoever builds the best protocol and UX for it wins.
## 3. Cross-Device, Context-Rich Experiences
True ambient computing means:
* Talking to your headphones
* Seeing the result on your phone
* Getting follow-ups on your TV
* Picking up where you left off on your car dashboard
Multimodality isn’t just input/output—it’s context continuity across devices. That requires deep coordination of hardware, software, and AI agents. Right now, no one has nailed this yet.
## 4. Deep Integration with User Accounts & Services
Today’s AI “agents” often feel like disconnected toys. Connecting them to your real accounts is clunky and slow.
The future? AI that can:
* Take actions inside your calendar, email, files, apps
* Do so safely, reliably, and with minimal setup friction
* Remember what you’ve done across services
The battle here is twofold: building trust and minimizing friction. The first to get this right will become the new “command center” for how people get things done online. Things like ChatGPT’s Connectors and MCP offer a window into the future here, but it’s still early days.
## Why Real-Time Matters—And Why It’s So Hard
Here’s the kicker: most of these AI-powered experiences require real-time interaction. That’s where the existing developer toolchain breaks down.
Real-time audio, in particular, is tough. The cloud tools out there today—LiveKit, Agora, Twilio, WebRTC—handle the pipes, but they don’t manage the complexity on your device. You still need to hand-roll things like:
* Audio graphs
* Speech detection
* Noise cancellation
* Voice changer integration
* Synchronization across media streams
* Low-latency DSP and hybrid workflows
That’s where Switchboard comes in.
## Switchboard: Turbocharging Real-Time AI Experiences
Switchboard makes it dramatically easier to build real-time, on-device and hybrid audio experiences—the kind of experiences next-gen AI apps need.
* Cross-platform audio graph abstraction
* Plug-and-play modules for VAD, STT, TTS, filters, effects, and more
* Real-time streaming that’s compatible with popular cloud solutions
* Built for speed, experimentation, and iteration
Whether you’re building a voice assistant, a social audio app, or a new kind of screenless AI interface, Switchboard reduces time-to-market by 10x.
We’re already partnering with teams pushing boundaries in this space, and through our Venture Studio, we also continue to experiment directly with what comes next.
## The Future Belongs to the Fast
The AI race is shifting from compute power to consumer resonance.
From benchmark wins to behavioral change.
From centralized dominance to distributed real-time UX.
Whoever ships the most beloved products—fast—will own the next front page of the internet.
We have the tools to make that happen. Let’s build amazing new experiences together.
[Get In touch](/contact)
---
# The Concierge Problem Is Real. Solving It Is Complicated.
> Every business wants customer service to feel like a personal concierge. Few are set up to actually deliver one.

Every business wants customer service to feel like a personal concierge. Few are set up to actually deliver one.
A recent [piece](https://www.a16z.news/p/the-internet-ruined-customer-service?utm_source=substack\&publication_id=13145\&post_id=191162732\&utm_medium=email\&utm_content=share\&utm_campaign=email-share\&triggerShare=true\&isFreemail=true\&r=5liio\&triedRedirect=true) from *a16z* makes a compelling case: the internet democratized commerce, but it made the experience of being a customer worse in the process. At scale, devoted attention couldn't scale with it. Now, they argue, AI changes that equation — making concierge-level service economically viable for any business, not just luxury brands.
We think they're right. We also think the gap between the vision and the reality is where most organizations quietly get stuck.
## The platform layer is the easy part
There's no shortage of purpose-built customer service AI platforms — Decagon, Sierra, PolyAI, Cognigy, Parloa, among others. These are genuinely impressive systems. They can handle high deflection rates, integrate with CRMs, and increasingly deliver experiences that customers actually prefer over a phone queue.
But platforms assume a level of infrastructure hygiene that most large organizations don't have. They assume your audio is clean. They assume your channels are unified. They assume the signal being fed to the AI is good enough to reason over in real time.
In practice, customer service doesn't originate in one place. It comes from mobile apps, web apps, telephony, chatbots, and siloed departments — each with its own audio pipeline, its own latency profile, its own noise floor.
And voice is especially unforgiving. Echo, background noise, codec artifacts, handoff delay — any one of these can break the experience before the AI ever gets a chance to help. The concierge vision falls apart when the audio arriving at the model sounds like it was recorded inside a moving car.
## This is where we come in
Synervoz has a consulting practice built around one of the harder problems in voice AI: making all the pieces work together. That means helping organizations understand where the real friction is — whether it's in the audio pipeline, the system architecture, or the choice of AI platform — and designing solutions that hold up under real-world conditions.
Evaluating whether to build on OpenAI's Realtime API, Anthropic's models, a dedicated platform like Decagon or PolyAI, or some combination isn't a vendor decision. It's an architecture decision. It requires someone who understands the full stack: models, audio pipelines, telephony, latency constraints, and the security and integration demands of enterprise systems. That's what we do.
And for organizations with mobile or web applications, we can go further. Switchboard, our real-time audio SDK, is built to handle complex multi-stream scenarios — human and agent audio together, across noisy environments, at low latency — processing audio on-device before anything touches the cloud. It's a capability that purpose-built customer service platforms don't offer, and one that matters a great deal when the quality of the audio directly determines the quality of the experience.
The concierge era is coming — the infrastructure has to catch up
The vision of AI as a concierge for every customer is worth taking seriously. But getting there requires more than choosing the right platform. It requires getting the audio right, the architecture right, and the integration right — simultaneously, in real time, at the moment a customer is already frustrated.
That's a hard problem. It's the one we're built for.
Curious how your voice AI stack holds up? We're happy to dig into the specifics — whether you're evaluating platforms, troubleshooting a live deployment, or starting from scratch.
## Curious how your voice AI stack holds up?
*We're happy to dig into the specifics, whether you're evaluating platforms, troubleshooting a live deployment, or starting from scratch.*
[Get in Touch](https://synervoz.com/contact/)
---
# The Dangers of Vibe Coding in Real Time Audio Processing: Why a Robust Foundation Matters
> Focused on software for interactive voice and video chat projects with complex audio requirements.
In an era of increasingly prevalent AI-assisted coding, many developers find themselves in a whirlwind of rapid iteration, loosely structured experimentation, and what is often referred to as "vibe coding." While this approach can be practical for prototyping and creative exploration, it can be disastrous when building complex, real time systems—particularly in fields like audio processing, where precision, performance, and reliability are paramount.
### What is Vibe Coding, and Why is it a Problem?
Vibe coding typically refers to AI-generated code using conversational prompts rather than structured design. Developers may piece together AI-suggested solutions through trial and error, trusting that the generated code will work without deeply understanding its implications. While this can accelerate prototyping as well as produce functional products, it introduces significant risks in critical and complex systems like real time audio processing, where every millisecond counts, and failure modes can lead to severe performance issues, instability, degraded audio quality, and more time chasing problems than the generated code saved in the first place.
Some key dangers of vibe coding in the context of real time audio include:
* Unpredictable Performance: Without a structured approach, inefficiencies accumulate, leading to buffer underruns, latency spikes, or unpredictable glitching.
* Brittle Codebases: Code developed ad-hoc is often difficult to extend, debug, or optimize, leading to technical debt that makes future improvements painful.
* Lack of Scalability: real time audio pipelines require careful modular design to scale efficiently across different hardware and software environments.
* Debugging Nightmares: In a nondeterministic, highly interactive environment like real time audio, debugging can be exponentially harder if the system is not guided by a structured design.
### How the Switchboard SDK Provides a Robust Foundation
Rather than falling into the trap of vibe coding, developers can use Switchboard as a structured, modular foundation for real time audio processing. Switchboard allows developers to build sophisticated audio pipelines using a well-defined node-based architecture, ensuring that even when AI-generated code is introduced, the risks are contained and the overall system remains stable and maintainable.
**1. Modularity Enables Experimentation Without Chaos**
Switchboard is designed around modular audio nodes, which encapsulate specific processing functions. This means developers (or AI) can rapidly iterate on individual nodes without affecting the entire system's integrity. Unlike monolithic, tangled codebases that vibe coding tends to produce, this structured approach keeps the core of the system stable while allowing AI to enhance or replace individual components in a controlled manner.
**2. Containing Risk When Using AI-Generated Code**
AI-generated code can be an incredible asset in real time audio, helping to create new DSP modules, voice changers, speech-to-text processors, or other complex audio transformations. However, AI-generated code is inherently unpredictable—sometimes it works perfectly, other times it introduces hard-to-diagnose issues.
With Switchboard:
* AI-generated nodes are sandboxed within the broader architecture.
* If an AI-generated node fails, it does not break the entire pipeline.
* Developers can replace or fine-tune AI-generated code without affecting the core system stability.
This containment strategy ensures that AI can be used as a powerful augmentation tool without risking the integrity of the entire audio pipeline.
**3. Ensuring real time Performance and Reliability**
Unlike traditional software development, real time audio systems must operate within strict timing constraints. Every processing step must execute within a fraction of a millisecond to avoid audio dropouts and latency issues. Vibe coding often results in inefficient, unoptimized code incompatible with these requirements.
Switchboard’s architecture enforces best practices in:
* Threading and Concurrency: Ensuring efficient CPU utilization without blocking real time threads.
* Memory Management: Avoiding dynamic allocations that could cause unpredictable slowdowns.
* Processing Efficiency: Each node is designed to run efficiently within the real time constraints of audio applications.
By providing these guardrails, Switchboard prevents the common pitfalls of vibe coding while enabling the creative flexibility that AI-assisted development offers.
### The Best of Both Worlds: AI-Powered Innovation with a Strong Foundation
AI is changing how developers write software, and its potential in real time audio processing is enormous. However, without a solid framework, AI-assisted development can easily devolve into an unmanageable mess of fragile, inefficient, and unreliable code.
Switchboard strikes a balance: it provides a structured, reliable foundation while still allowing for AI-driven innovation at the modular level. This means developers can safely experiment with AI-generated DSP modules, speech processing algorithms, and other audio features without introducing the chaos of vibe coding.
### Conclusion: Build Smart, Not Just Fast
Vibe coding might work for quick demos, but when it comes to real time audio pipelines, a structured, modular approach is essential. Switchboard provides the foundation to build reliable, scalable, and high-performance audio applications while allowing AI to play a powerful role in enhancing individual processing nodes.
By choosing the right tools and frameworks, developers can ensure that their AI-assisted code remains manageable, maintainable, and optimized for real time performance—without sacrificing speed and innovation.
[Get In touch](/contact)
---
# The Evolution of Social Audio: Exploring the Pioneers and Future Trends
> Focused on software for interactive voice and video chat projects with complex audio requirements.
Lockdowns led to a surge in social audio apps over the past few years, revolutionizing the way people connect and communicate. From the early listening party pioneers like Switchboard and Roadtrip to "town square" apps like Clubhouse and Twitter Spaces, these platforms illustrated new ways to engage in real-time conversations, share music, ideas, and form meaningful connections. Here's a quick overview of the origins of the modern social audio movement and the pioneering role of our very own Switchboard App (formerly known as TurnMeUp). We'll also discuss how social audio is poised to shape the future as microphones and speakers become ubiquitous across a wide range of devices.
### The Birth of Social Audio
Perhaps somewhat hubristically, we would trace the modern social audio movement back to the early 2010s around the time we (Synervoz) started tinkering with an app we called TurnMeUp. To our knowledge, this was the first app where you could listen to music together with a persistent Voice over IP connection (i.e. a listening party with voice chat). We pioneered (and patented) technology related to “auto-ducking” media in response to voice activity detection (VAD) in environments where people were connected through voice or video chat while listening to music and other media. TurnMeUp was aimed at use cases like walking, running, cycling, and skiing together, such that you could listen to music and still talk without having to take your headphones off.
In 2016, Synervoz entered the Techstars accelerator in partnership with Virgin Media, and shortly thereafter we relaunched the app as Switchboard. The target audience shifted to remote workers who wanted to feel more connected by having instant audio connections to their remote team, and to be able to hang out and listen to music together in rooms. We explored a lot of pioneering ideas before they were popularized by others: drop-in audio channels, voice commands to activate them, synchronizing the music you’re listening to, watching YouTube together, wiring up buttons to turn your remote office desk into an instant intercom, and more. You can see some examples of this in our [venture studios](/venture-studio/) — but suffice it to say that we laid some of the foundations for the social audio movement to come.
### The Explosion of Social Audio
Switchboard was perhaps a little too early to market, as it was during the COVID-19 lockdowns that the social audio genre truly took off. We passed the “listening party” torch to Roadtrip (later renamed Campground), which was, to some extent, a modern take on [turntable.fm](https://deepcut.live/) — but in this case including voice chat and targeted at mobile devices.
Then came Clubhouse and an explosion of competing products and features that attempted to ride the social audio wave. Twitter Spaces, new features in Discord, Spotify, and Meta’s suite of apps are only a few of the dozens of examples. Some of these platforms became a lifeline for individuals craving social interaction and networking opportunities in a physically distanced world. Others faded into obscurity. Kosmi is one product that stuck around, and we became closely involved with. If you’re curious, head over to to check that out.
### The Future of Social Audio
A crucial factor contributing to the proliferation of social audio is the widespread availability of microphones and speakers on a variety of devices. Smart speakers have become commonplace in homes, providing an effortless way to join audio discussions with a simple voice command. Earbuds, worn more frequently, have transformed into personal audio hubs, allowing individuals to participate in conversations on the go. Smart TVs and soundbars are also starting to integrate social audio capabilities, enabling immersive experiences in living rooms.
Smart assistants will also play a vital role in facilitating connections through social audio. Whether its finding out which friends are available, making it easy to join conversations, switching between apps, or creating personal audio rooms, smart assistants will streamline the user experience. Voice assistants will help people to effortlessly connect with others
As microphones and speakers continue to proliferate across devices, social audio is poised for further growth. The trend will expand beyond dedicated apps to becoming an integral part of many digital platforms and ecosystems. We anticipate a seamless integration of social audio into messaging apps, social media platforms, streaming media (music, video, and games), virtual reality environments, and, indeed, the metaverse. The future of social audio holds the promise of enhanced communication, deeper connections, and the democratization of voices.
### Conclusion
The explosion of social audio apps has ushered in a new era of communication, transforming the way individuals connect, collaborate, and build relationships. With Switchboard as one of the original pioneers of social audio, dating back to its early days as TurnMeUp, we helped lay the groundwork for this genre. As microphones and speakers become more prevalent on a wider range of always-connected devices, you can expect Synervoz and our Switchboard platform () to be an increasingly obvious part of the landscape.
[Get In touch](/contact)
---
# The Fusion of Voice and Video Chat: Exploring Diverse Applications
> Focused on software for interactive voice and video chat projects with complex audio requirements.
In today's digital era, voice and video chat have become indispensable tools for communication, collaboration, and entertainment. By combining voice and video chat with other audio sources, a multitude of applications across various domains have emerged, transforming the way we connect and interact. In this blog post, we will explore the main applications where voice and video chat are combined with other audio sources, ranging from professional environments to social settings and beyond.
1. **Watch Parties and Listen Parties:**\
One of the emerging trends is the concept of watch parties and listen parties. These interactive experiences bring people together virtually to simultaneously watch movies, TV shows, or listen to music. Voice and video chat serve as the foundation, enabling participants to communicate in real-time while synchronized with the audiovisual content. These events often incorporate additional audio sources, such as shared background music or sound effects, creating a shared atmosphere and enhancing the overall enjoyment.
2. **Online Meetings and Video Conferencing:**\
Voice and video chat have revolutionized online meetings and video conferencing, enabling remote teams and individuals to connect seamlessly. Alongside face-to-face communication, other audio sources like screen sharing, presentation audio, and collaborative document editing complement the experience. This integration fosters collaboration, allowing participants to discuss, share visual content, and work on projects in real-time, regardless of physical distance.
3. **Webinars and Online Classes:**\
In the realm of education and professional development, webinars and online classes benefit greatly from combining voice and video chat with other audio sources. Lecturers and presenters can engage learners through live video streams and interactive discussions. Additional audio sources, such as pre-recorded lectures, background music, and interactive polls, further enhance the learning experience, making it more immersive and engaging.
4. **Customer Support and Help Desks:**\
Voice and video chat play a crucial role in customer support services and help desks. The integration of these features allows for real-time communication, enabling support agents to address queries, resolve issues, and provide personalized assistance. Other audio sources, like automated voice prompts, recorded messages, and background music or announcements, contribute to a seamless and professional customer service experience.
5. **Gaming and Esports:**\
In the gaming industry, voice chat has become a staple for multiplayer games, enabling players to communicate and strategize in real-time. Video chat may also be integrated for live streaming, esports events, or team coordination. Moreover, game audio sources, such as in-game sounds and music, add depth and immersion to the gaming experience, creating a multisensory environment.
6. **Remote Collaboration and Teamwork:**\
Voice and video chat combined with other audio sources play a vital role in facilitating remote collaboration and teamwork. Collaboration tools and platforms integrate voice messaging, audio notifications, and background audio to enhance communication, project management, and team cohesion among remote team members. These features promote efficient and effective collaboration, irrespective of geographical barriers.
7. **Social Media and Communication Apps:**\
Voice and video chat are integral components of popular social media and communication apps. These platforms enable real-time voice and video conversations between individuals, fostering connections and maintaining social relationships. Additionally, other audio sources, such as voice messages, multimedia content, and background music, contribute to the overall user experience, making interactions more engaging and personalized.
8. **Podcasting and Broadcasting:**\
Podcasts and broadcasting platforms leverage voice and video chat alongside additional audio sources to create captivating content. Through live interviews, discussions, and audience interactions, podcasters and broadcasters engage their listeners and viewers. These platforms often incorporate background music, sound effects, and audience participation to enhance the immersive experience and keep the audience captivated.
The combination of voice and video chat with other audio sources has revolutionized various aspects of our lives, from professional collaboration to entertainment and social interactions. The applications explored in this blog post highlight the versatility and impact of this fusion in different domains. As technology continues to evolve, we can expect further innovations that integrate voice, video, and audio sources to create even more immersive and engaging experiences for users around the world.
The Switchboard SDK was designed to help with these types of applications. Check out to learn more.
[Get In touch](/contact)
---
# The Future of AI Is On-Device
> While the AI conversation focuses on models and cloud compute, a parallel shift is underway: AI inference is moving onto the devices we already own, reducing the need to send every task to the cloud.
Most of the AI conversation still revolves around the cloud: which company has the best model, who has the most GPUs, and how much compute the next generation of models will require.
But a parallel shift is happening that may matter just as much for application developers: **AI inference is moving onto the devices we already own.**
Phones. Laptops. Desktop computers. Smart speakers. Cars. Wearables. Eventually, almost anything with enough compute and memory.
This doesn't mean frontier models or cloud AI are going away. It means we probably won't need to send every AI task to them.
## Models are getting small enough to live everywhere
The capabilities available in relatively small models have improved enormously.
Google's Gemma family is explicitly being designed for mobile and edge hardware. Gemma 3n, for example, can process text, images, video and audio while operating with memory requirements comparable to a 2B or 4B parameter model. Google describes it as being designed specifically for phones, tablets and laptops.
Apple now gives developers direct access to the foundation model running on Apple Intelligence devices. Its on-device models support things like summarization, extraction, image understanding, structured output and tool calling without requiring every request to leave the device.
Microsoft has been embedding small models such as Phi-4-mini directly into Edge, while Meta has released 1B and 3B Llama models specifically designed to fit on mobile and edge devices.
And the list is growing quickly.
Some representative examples:
* **Gemma 3n / Gemma models**: multimodal understanding, transcription, translation, reasoning and general application intelligence on phones, tablets and laptops.
* **Llama 3.2 1B/3B**: summarization, rewriting, instruction following and other lightweight language tasks on phones and edge hardware.
* **Qwen3 0.6B and other small Qwen variants**: very compact language models capable of instruction following, multilingual processing, reasoning and tool-oriented workflows; small enough to make local deployment practical across increasingly modest hardware.
* **Whisper Tiny/Base/Small**: speech recognition that can already run completely offline on iPhones, Android devices, Raspberry Pis, Macs and PCs.
* **Task-specific models**: VAD, noise suppression, wake-word detection, speaker identification, embeddings, translation and other narrowly focused models can run on considerably more constrained devices, including embedded systems and wearables.
That last category is especially important.
On-device AI doesn't necessarily mean putting one general-purpose LLM everywhere. Often the better architecture is several small models, each doing one job extremely well.
## Why send everything to the cloud?
If an application can determine whether someone is speaking locally, there isn't much reason to stream silence to a server.
If it can transcribe speech locally, perhaps only the resulting text needs to reach a larger model.
If a small local model can classify a request, summarize some text, understand a command or call a function, perhaps the cloud model doesn't need to be involved at all.
The advantages compound.
**Latency improves** because there is no network round trip.
**Costs fall** because fewer tokens, audio streams and API requests need to be processed in the cloud.
**Privacy improves** because sensitive data can stay on the user's device.
**Reliability improves** because some features continue working with a bad connection—or no connection at all.
And **scaling gets easier**. Ten million devices performing inference themselves is very different infrastructure from ten million devices continuously asking your servers to do it for them.
## The interesting architecture is hybrid
None of this means every application should download the largest model that can physically fit on a phone.
The cloud remains incredibly useful. Larger models will continue to be better at difficult reasoning, broad knowledge, large contexts and tasks where additional compute actually improves the result.
The more interesting architecture is therefore:\
**local first, cloud when necessary.**
A wearable might handle wake words, audio preprocessing and simple intents locally, then hand a complex request to a phone.
The phone might run speech recognition and a small language model locally, but route difficult reasoning to a frontier model.
A laptop or desktop can push that boundary considerably further, running much larger models entirely locally.
A smart speaker might locally handle the majority of common commands while calling the cloud for the long tail.
Instead of choosing one model, developers increasingly get to choose **where each piece of intelligence belongs**.
## This is where we've been positioning Switchboard
This shift is also a big part of how we've been building our [**Switchboard Voice AI**](https://switchboard.audio/cases/voice-ai/) product line.
Voice is particularly well suited to hybrid architectures because there are so many pieces in the pipeline: voice activity detection, echo cancellation, noise suppression, speech recognition, turn detection, speaker processing, language models and text-to-speech.
Some of those pieces should almost always happen locally. Others increasingly can happen locally. And some still make sense in the cloud.
Our goal is to make those decisions modular.
Today, our tooling already supports architectures where audio processing, VAD, STT and other components run on-device, while cloud models are used only where necessary. We're extending that approach toward complete local and hybrid voice-agent pipelines across mobile, desktop, embedded devices, smart speakers and wearables.
We've been betting for some time that AI applications won't ultimately be built around a single giant API call.
They'll be built from a combination of models running in different places, selected according to the task, available hardware, latency requirements, privacy requirements and cost.
And as small models keep improving, the portion running on the device is only going to get bigger.
---
# The Future of Automotive Audio: The Transformation of In-Car Entertainment
> Discover how immersive automotive audio and AI-powered voice controls are shaping the future of in-car entertainment. Learn how to integrate spatial audio, real-time audio processing, and advanced voice-activated systems to enhance the driving experience. Start building next-generation automotive audio solutions today!
### The shift in automotive design
This shift reflects the evolution of the car interior into a “living room” on wheels. Just as we watch movies on flights, the concept of streaming content or gaming during a car ride is becoming more viable as infotainment options expand. Tesla's latest update includes features such as multi-screen setups—with rear passenger control of video streaming on apps like YouTube and Netflix—showcasing how cars can support more personalized, family-friendly entertainment during road trips.
The potential of automotive audio is especially exciting as cars become entertainment hubs. **Advanced spatial audio and multi-channel setups** can offer immersive soundscapes for movies, music, and calls, enriching in-car experiences.
Companies like **Synervoz** are tapping into this trend by developing audio solutions tailored for the automotive industry. Their technology, which includes high-quality audio pipelines and spatialization, allows for real-time audio adjustments and multi-room audio management. This means that in-car sound systems can adapt based on each passenger's preferences—whether it's quieting down a movie soundtrack to prioritize phone calls or redirecting audio to different parts of the cabin.
Looking ahead, the combination of smart voice controls and enhanced audio options will likely dominate the future of automotive audio. Passengers will be able to control everything from volume to spatial configuration through AI-enabled voice commands, creating a truly hands-free, immersive entertainment experience. With companies like Tesla and Synervoz pushing these innovations, the future of automotive audio is set to redefine in-car entertainment, transforming travel into a rich, multi-sensory experience.
[Get In touch](/contact)
---
# The Future of Communication for Deskless Workers
> Explore how AI-enhanced communication devices and real-time communication tools are transforming how deskless workers stay connected. Learn how to implement voice-activated systems, AI-driven noise suppression, and seamless audio solutions to build the future of workplace communication. Start developing smarter tools today.
### **Zinc and the Power of Integrated Communication**
Zinc initially focused on **frontline communication** for industries like healthcare, retail, and field services, emphasizing real-time messaging, voice calls, and video. After its acquisition by ServiceMax, Zinc’s capabilities were combined with **field service management**, giving workers a platform to communicate and manage tasks within the same ecosystem. This integration helped service workers solve problems on the go, reducing downtime and making assistance just a call away.
### **Our Switchboard 1.0 Experiments in Deskless Communication**
With **Switchboard 1.0**, we explored audio solutions that could empower deskless teams by ensuring clear, reliable communication. We focused on **real-time audio**, enabling team members to connect instantly without needing to dial in or switch apps. These experiments underscored the importance of audio clarity, ease of use, and battery efficiency—especially in noisy environments like construction sites or hospitals.
### **The Future: Smart, AI-Enhanced Walkie-Talkies**
The next generation of deskless communication is likely to feature **smart walkie-talkies** with built-in AI. Imagine a device that combines the ruggedness and simplicity of a traditional walkie-talkie with the intelligence of modern voice assistants. With **AI-driven features** like automatic noise suppression and contextual voice commands, workers could communicate hands-free, seamlessly switch between tasks, and access relevant information on demand.
For example, smart walkie-talkies could use **AI to analyze voice patterns**, identifying when a worker is requesting information versus talking to a colleague. These devices could even integrate with service management software, enabling workers to file reports or receive task updates via voice commands.
### **Always-On Connectivity and Safety**
Safety is a top priority for deskless workers, and **always-on connectivity** can provide a vital link to emergency support. Future communication devices might feature **“always-listening” technology** that can recognize distress signals or automatically detect when a worker needs assistance. Hands-free controls and easy voice-activated commands mean workers can stay connected even in challenging environments without having to remove gloves or tools.
### **Bridging the Communication Gap**
Companies like ServiceMax and innovative platforms like Switchboard are setting the stage for a more connected, efficient future for deskless workers. By combining robust communication with task management and AI-powered features, the future of deskless work will prioritize **instant support, safety, and seamless information flow**. As technology evolves, we’re likely to see smart devices that keep workers safe, efficient, and connected, no matter where their job takes them.
[Get In touch](/contact)
---
# The Future of Human-Device Interaction: Ears, Voices, and the Rise of Audio Graphs
> Focused on software for interactive voice and video chat projects with complex audio requirements.
### **The Future of Human-Device Interaction: Ears, Voices, and the Rise of Audio Graphs**
The world of technology is evolving, and with it, the way we interact with devices is shifting dramatically. We’re entering an era where every device is equipped with three critical components: microphones, speakers, and now, a "brain"—artificial intelligence that allows these devices to understand, process, and respond to human input. This brain-powered interaction means that the lowest common denominator for communication is no longer screens or touchpads; it’s ears and voices.
In this blog, we’ll explore how speech-based interaction is poised to dominate the future of human-device communication, why audio graphs are becoming critical infrastructure for this shift, and how Synervoz and its Switchboard SDK are perfectly positioned to help build this future.
### **The Evolution: From Touchscreens to Speech-Based Interaction**
For years, human-device interaction has been driven primarily by visual and tactile interfaces. From tapping on touchscreens to typing commands into a keyboard, we’ve adapted ourselves to these methods of communication. But that’s changing. As devices become more intelligent—thanks to advancements in machine learning and natural language processing—they’re also becoming more human in how they communicate. Devices now listen and speak.
While some devices will push the boundaries with additional sensory input, like cameras or touch sensors, allowing for more complex, human-like robots, most will rely on speech-based interaction as their primary mode of communication. Why? Because it’s the most natural and efficient way for humans to interact with the world. We talk. We listen. And now, our devices can do the same.
This shift toward voice-first interfaces presents both challenges and opportunities. At the core of this new paradigm is audio—specifically, how audio is processed, transformed, and delivered. This is where audio graphs come in.
### **The Importance of Audio Graphs in a Voice-First World**
In this new era, audio isn't just about playing a sound or recording speech. It’s about constructing complex, dynamic audio pipelines that can handle everything from speech recognition and text-to-speech, to noise suppression and real-time voice transformation. Enter the concept of *audio graphs*—the building blocks that allow developers to build these sophisticated pipelines.
An audio graph is essentially a flowchart of how audio moves through various processing stages, from input (microphone) to output (speaker), with transformations in between (e.g., noise suppression, voice modulation). These graphs give developers control over how audio is processed at every stage, allowing for more complex and nuanced audio-based interactions.
As speech-based interaction becomes the default, the demand for robust, flexible audio frameworks will skyrocket. Developers will need tools that allow them to easily create and maintain audio pipelines that integrate with AI-driven systems. This is where Synervoz and Switchboard come into play.
### **How Synervoz and Switchboard Are Shaping the Future**
Synervoz, with its innovative Switchboard SDK, is positioned to be at the forefront of this new wave of human-device interaction. Switchboard simplifies the development of complex audio applications by offering a modular framework for creating and managing audio graphs. Whether you’re developing real-time speech-to-speech systems, voice-changing applications, or noise-suppression tools, Switchboard provides the building blocks you need.
Instead of reinventing the wheel, developers can leverage Switchboard’s pre-built audio modules, focus on their core technology (like DSP or machine learning models), and quickly integrate advanced audio features without getting bogged down by low-level infrastructure challenges.
Moreover, as AI-driven interactions become more prevalent, Switchboard's flexibility allows it to support both on-device processing and cloud-based solutions. This is especially crucial for handling edge cases, such as devices with limited resources or applications requiring real-time processing and control over the audio pipeline.
### **A Future Powered by Voice and Audio Graphs**
In a future where devices listen, speak, and understand, audio will be the backbone of human-device interaction. Whether it’s your smartphone, smart speaker, or even a humanoid robot, the ability to process and transform sound in real-time will define how seamlessly these devices integrate into our lives.
Audio graphs will play a foundational role in this future. And Synervoz, with Switchboard at its core, is building the tools that will enable developers to create the next generation of audio-driven applications.
We’re at the cusp of a revolution in how humans and machines communicate. Devices may have ears and voices now, but it's what we do with audio technology that will define this new era. Switchboard is ready to help developers bring this vision to life.
### **Conclusion: The Next Step**
As the world moves toward voice-first interaction, the importance of audio in technology is only going to grow. Developers need powerful, flexible tools to handle the complexity of real-time audio processing, and Synervoz’s Switchboard is uniquely suited to meet these demands. Whether you're developing an AI assistant, a smart home device, or a futuristic robot, the future of audio is already here, and Synervoz is leading the charge.
Are you ready to build the next generation of audio applications? Start with [*Switchboard*](https://switchboard.audio/).
[Get In touch](/contact)
---
# The future of motorcycle audio
> Founded Synervoz in 2014. Former engineer turned entrepreneur with a background in engineering, finance, and management. Queen's graduate and top 1% MBA graduate from IE Business School. Product designer, inventor, and two-time Techstars founder. Canadian Music Week pitch winner, SXSW finalist, and has traveled to 60+ countries.
This is the first summer I've ridden with AirPods Pro 3.
Apple also recently released a beta firmware update for AirPods that adds some interesting new capabilities, so I wanted to do some testing.
What follows are some of my observations about this experience, as well as where I see the future of motorcycle audio given this experience and the gaps that remain to be filled.
This is not meant to be a review of any of the products mentioned here; just some personal observations and what I think they mean for where the industry is headed.
I’ve been chasing the "perfect motorcycle audio experience" for well over a decade. Not just as a rider, but professionally, given my company specializes in audio software development.
Over the last ten years of running Synervoz, I've had conversations with companies across the industry—Cardo, Sena, Apple (including the AirPods team), and others—about what I thought was missing from the motorcycle audio experience.
For years, it always felt like the technology was moving in the right direction, but painfully slowly. This week was the first time I got on my Harley and thought:
*"Wait... this is actually starting to happen."*
## From the original AirPods Pro to AirPods Pro 3
I've been riding with AirPods under my helmet since the original Pro model first came out.
My original AirPods Pro worked pretty well initially – certainly better than any passive earplugs ever worked for me – but over time the active noise cancellation became less effective. They also developed that infamous high-pitched squeal every once in a while, which made rides less fun and more tiring.
So I bought a new pair of AIrPods Pro 3 and this summer is the first time I’ve gotten to try them out while riding. And the difference is even more than I expected.
## Noise Suppression and Adaptive Audio
For context, I ride a Harley V-Rod Muscle. If you've never heard one in person, it isn't exactly a quiet motorcycle. It’s a Porsche-designed engine with a badass sound, but it also makes an absurd amount of noise.
I ride with a full-face helmet. Often without a windshield, and in that setup the engine remains louder than the wind until, I dunno, maybe 80-100 km/h. With a windshield, that crossover might happen closer to 120 km/h. Hard to say exactly, but historically that’s my perception using the original Airpods Pro.
But with my Airpods Pro 3, the engine noise drops from being the dominant thing you hear to barely noticeable. It’s almost weirdly quiet (more on safety concerns later). And it does a pretty good job of killing the wind at highway speeds as well.
But even more interesting was **Adaptive Audio**. You can actually hear the noise cancellation gradually engage, which really lets you appreciate just how much sound it's removing.
Paired with **Conversation Awareness**, it’s kind of a game changer.
I often find myself in a scenario where I pull into a gas station, or stop at a red light, friends roll up next to me, and start talking. So immediately I’m fumbling in my pocket trying to change the volume (among other alternatives like pausing music, finding transparency, etc.).
And by the time I've done all that, the light is green and I’m either fighting to pocket my phone or get the volume back up before moving again.
Of course, different solutions with voice detection and music auto-ducking have been in the market for a while. In fact, we patented some technology in this area almost 15 years ago. But incumbent alternatives had always been limited in other ways. For example, mobile apps (including one we made) that combine VoIP + Music won’t work off grid. And intercom systems historically do not have ANC (more on that later too).
So, having Adaptive Mode + Conversation Awareness built into the Airpods Pro 3 and that actually working in the vicinity of multiple Harley engines running is insane. The music fades smoothly and the transparency opens up so I can hear my friend, then the noise suppression ramps back up when we start moving again. It sounds almost magical.
Finally, we’re getting close.
## What’s still missing
What's funny is that this is almost exactly the direction I've been hoping the industry would move toward. For years I've had conversations – though perhaps not enough – around the shortcomings of existing intercom systems. Not because they're bad. They're actually impressive pieces of engineering and product design. But they’ve never had it all, and a viable solution has always felt like cobbling together multiple components instead of one cohesive experience.
The Airpods Pro 3 experience shows me that the gap is narrowing. But there is still plenty of room to build a more cohesive system.
For example, Adaptive Audio could benefit from motorcycle-specific presets.
Imagine a mode that intentionally lets through:
* emergency vehicle sirens
* horns
* tire squeal
* nearby traffic
...while still aggressively suppressing engine and wind noise.
That's a very different optimization problem than walking around downtown wearing earbuds.
Voice control also still struggles.
At most meaningful speeds, Siri has a hard time hearing me at all.
And even in quiet conditions, she’s not great at changing directions or adding stops on the fly. She’s still a bit clunky vs. the ideal user experience one would hope for.
On the other hand, she’s WAY more capable than before. In quiet conditions, changing my music, pulling up Maps to go simply from point A to point B, or having a short voice AI conversation about whatever – it works.
It’s clear to me that the seamless voice experience where you can control multiple apps through a single unified interface – music, navigation, comms with friends, and random voice ai discussions – is almost here.
The biggest blocker at the moment is Siri’s inability to hear me at speed. That said, I don’t think it’s crazy to expect that, even under a full face helmet, and even at highway speed with crazy levels of noise, in-ear microphones could get a clean enough signal to work well in the context of voice commands and conversation in general – be it with other riders or Voice AI.
I’ve run a few experiments, and I intend to run several more (e.g. different helmets, different speeds, different bikes, different headphones), where I took recordings while riding.
[](https://a-us.storyblok.com/f/1001508/x/67544e9ce0/jim-on-motorcycle.mp3)
What this shows is that, on that ride, I actually got a surprisingly good signal despite the noise and headphones being pressed into the foam of my helmet. And I’ve found my voice is usually intelligible across a variety of conditions. So, even if the current model wasn’t trained extensively in motorcycling conditions, if it’s intelligible to me, we can probably fine-tune a model to which it will also be intelligible.
It’s worth noting that motorcycle intercoms have the advantage of a directional microphone placed right in front of your mouth inside the helmet. On the other hand, they aren’t super portable. It would be nice if these were made wireless and sold with multiple fitments (velcro and otherwise) so that they could be easily swapped across different helmets, shared with friends, and potentially paired with either the intercom or your phone (for when you’re riding alone, or on-the-grid with friends who don’t have intercoms, for example).
A near term workaround I experimented with, using a cheap Bluetooth mic, worked surprisingly well. There's potentially an interesting accessory waiting to be built there.
But I digress.
## Why Cardo and Sena Still Matter
It’s tempting to think AirPods will replace intercoms. But that’s still not feasible for off-grid rides.
One of the biggest advantages of Cardo and Sena is something your phone simply can't do.
Mesh intercom for rides where you have poor cellular coverage.
A consistent, reliable offline connection remains really valuable.
While Bluetooth offers some possible workarounds, there are serious limitations. The range isn't good enough, and for most in-market devices, as soon as you switch Bluetooth into two-way audio mode, your music is limited to a low sample rate, so it sounds terrible. While there are some other potential workarounds for devices – e.g. Bluetooth 5.3, aptX, Skaa for broadcast audio-sharing, among other possibilities – range will still be an issue for off-grid rides.
While I can imagine a purpose built device that you could put in your pocket for a more portable solution, helmet-mounted mesh intercoms are still the best solutions today.
## Motorcycle Intercoms Have Their Own Problems
I've owned a Cardo Packtalk Bold for years.
It’s pretty good and accomplishes the essentials. And having tried out a newer model belonging to a friend of mine – intercoms seem to be getting a little better each year.
But they still leave a lot to be desired.
Installing speakers and wiring into a helmet is annoying.
They're not particularly portable if you own multiple helmets.
You can't easily lend one to a friend.
Voice commands become increasingly unreliable as speeds climb.
Depending on your helmet + intercom + mic setup, your motorcycle, and how much wind you're sitting in, the voice activity detection may not trigger unless you yell. Or it'll stay open when it shouldn't.
If you ride a Harley without a giant batwing fairing or if you don’t wear a full-face helmet, you'll struggle to find a setup that works.
And we still haven’t addressed active noise cancellation.
## The Weird Hybrid Setup That Actually Works
So today I ride with a combination of my Cardo and AirPods Pro 3 inside my helmet. Surprisingly, it's a pretty good combination.
The AirPods handle music, Siri (which finally has some hope given recent changes), Google Maps, ANC, and Adaptive Audio.
The Cardo handles the intercom via mesh.
As long as I don't blast my music too loudly, I can still hear the intercom surprisingly well.
The two systems basically operate independently. It's not elegant, but it's the closest I've come to the experience I've wanted for years.
## What About the New Sena + Bose Units?
I haven't yet had the chance to try the new Sena 60S EVO or 60X systems with Sound by Bose.
My guess is this will come closer than anything else to an all-in-one solution.
I'm definitely looking forward to trying it out to see how the in-helmet headphones sound, and curious to see how the system comes together with the optional ANC earbuds tied in.
I've heard the in-ear concerns over the years. Whether we’re talking about motorcycling, running, or cycling; that in-ear devices are too dangerous because they block important road sounds.
The concern is well founded. But I think the technology has finally moved beyond it. Selective hearing is now possible. Instead of simply blocking sound, we can choose which sounds matter. Suppress engine drone. Reduce wind fatigue. Boost sirens. Boost horns. Boost nearby traffic.
That isn't just more enjoyable. It could actually be safer.
## The Last Mile
The thing that still feels missing isn't necessarily new hardware or entirely new software.
It's integration.
Imagine saying:
"Hey headset, mute the intercom for a minute."
Then continuing naturally:
"Find a place with a good patio where other bikers tend to stop."
"Reroute us through the twistiest roads."
“In my podcast they were talking about CRISPR GPT and AI-driven protein design. Can you give me an overview of how that works in layman terms?”
“Share the podcast with Nick and Greg and go back 2 minutes”
No memorizing command trees.
Seamlessly switching who and what you’re talking to, listening to, and paired with.
No confusion about whether you're talking to Siri, your headset, your phone, your GPS, or your intercom. The systems just integrate and interoperate seamlessly. Natural conversation to get what you want instantly and without memorizing what’s possible.
The underlying technology is finally capable. Voice AI has matured. Noise suppression has matured. Speech recognition has matured.
The missing piece is stitching everything together into one cohesive rider experience. None of these individual technologies feel futuristic anymore. The magic is making them disappear into the background. It’s easier said than done, but it’s exciting that we’re finally there.
## Why I'm Optimistic
For the first time, I don't feel like we're waiting for some future breakthrough. I think we're mostly waiting for good product design. The building blocks are finally here.
As someone who's spent years building real-time voice systems at Synervoz, and who spends a lot of weekends riding, it's the most exciting time for motorcycle audio that I've seen in my riding lifetime.
I’ve long been thinking about that last mile.
More portable systems.
Better integration between music, intercoms and voice assistants.
Natural Voice AI conversations instead of rigid command phrases.
Smarter interaction with the next generation of Siri and other AI assistants.
The future motorcycle headset shouldn't feel like a collection of separate gadgets. It should feel like one intelligent companion riding with you. For the first time in a long time, I think we're actually close.
If you're working on this problem too, I'd love to talk.
---
# The Metaverse is Still Coming: How Wearables, AI, and Audio Are Paving the Way
> Discover how Meta's AR glasses, AI advancements, and immersive audio are bringing the metaverse closer to reality. Learn about the technologies redefining digital interaction.
### **Meta’s Vision and the Role of Wearables**
Meta has maintained a firm belief in the potential of the metaverse, a virtual universe where digital and physical worlds converge. While the initial push centered around VR headsets like the Quest, Meta has now turned attention to **AR glasses**, aiming to integrate the digital experience into our real-world activities. These wearables are designed to become as ubiquitous as smartphones, offering an immersive experience without the need to fully disconnect from the real world.
Wearable devices like AR glasses represent the **next phase of computing**, potentially becoming as indispensable as mobile phones. With augmented reality projected right into users’ vision, these glasses allow people to access information, collaborate with others, and interact with digital content without taking out a device.
### **How AI Will Usher in the Metaverse**
**Artificial Intelligence** is key to making the metaverse functional and intuitive. AI powers several features crucial to an immersive experience:
* **Enhanced Reality Perception**: AI algorithms can understand and interpret real-world environments, adding contextually relevant digital elements that blend seamlessly with physical surroundings.
* **Personalization**: AI allows for tailored experiences, adapting to individual preferences and needs, which is essential for making the metaverse practical and engaging for daily use.
* **Voice and Gesture Recognition**: AI-driven interfaces enable hands-free interaction through voice commands and gestures, making it easier for users to interact with virtual elements without complex controls.
These advancements ensure the metaverse can be as dynamic and responsive as the physical world, with **virtual assistants** able to provide real-time information, recommendations, and support—all without a traditional screen or keyboard.
### **The Vital Role of Audio in an Immersive Metaverse**
While visuals are important, **audio will be a cornerstone of the metaverse experience**. Effective spatial audio will help create a realistic sense of place, giving depth to virtual environments and making digital interactions feel natural. High-quality, immersive audio is essential for navigating these virtual spaces intuitively, especially when augmented by AI.
Consider the importance of clear, spatially accurate sound for tasks such as **directions, alerts, and real-time communication**. In a fully realized metaverse, audio cues will allow users to “hear” directions from their AR glasses or engage in private conversations even within crowded virtual settings. This seamless interaction, enhanced by real-time audio processing and noise filtering, will be crucial to making the metaverse a functional part of daily life.
### **The Metaverse: Moving Closer to Reality**
Meta, along with other tech leaders, is actively investing in the infrastructure and tools necessary for this vision. **Wearables, AI, and immersive audio** are converging, turning the metaverse from a distant concept to a tangible goal. Though it might still be in development, the metaverse promises to transform how we interact with technology, opening new pathways for communication, collaboration, and creativity.
As these technologies advance, the metaverse will grow from a speculative vision to an integrated part of our everyday lives, reshaping how we engage with the world and with each other.
[Get In touch](/contact)
---
# The Real AI Frontier: Systems Integration
> Focused on software for interactive voice and video chat projects with complex audio requirements.
AI has dominated tech headlines with breakthroughs in foundational models from OpenAI, Google, Meta, Anthropic, Mistral, and Deepseek. These models, powered by immense computational resources and data, have set the benchmark for what AI can achieve.
However, the landscape is rapidly shifting.
The foundational models are now engaged in a game of leapfrog, where leads are short-lived, and the race has led to the commoditization of these technologies. Open-source models, such as LLaMA and Falcon, have democratized access to cutting-edge AI, enabling developers to build on existing models without starting from scratch. DeepSeek demonstrated how foundational models can be rapidly iterated and deployed, underscoring this trajectory toward commoditization.
The real frontier for AI is no longer the models themselves but the systems that integrate them. It’s on the inference side.
The opportunity lies in the hands of those who can design, build, and deploy systems, applications, and novel use cases that unlock the true potential of these models. This will benefit systems integrators and the businesses that use them to implement AI solutions before competitors.
### The Shift Toward Systems and Ecosystems
As open-source initiatives close the gap with proprietary models, the industry’s focus is on what comes next. Companies like Google and Meta are uniquely positioned to lead this charge because of their expansive ecosystems. By seamlessly embedding AI into existing products like Google Workspace or Instagram, they can create unparalleled user experiences that are both sticky and transformative.
For smaller players, the race is about agility. The ability to rapidly prototype and deploy systems that leverage AI for specific applications will separate winners from also-rans. The competitive advantage no longer lies in owning the most advanced model but in building the systems that effectively incorporate these models into workflows, solving real-world problems at scale.
### Bridging the Gap: The Synervoz Approach
For years, Synervoz has integrated AI with real time systems, from the early speech-to-text and natural language models to the latest LLMs. Our mission is to simplify the path of using AI models in real-world applications for our customers. Through our flagship product, Switchboard, we provide developers with tools to rapidly connect AI capabilities to products across multiple platforms, whether for online or offline operation.
The Switchboard SDK is a modular framework that enables developers to build complex audio pipelines without reinventing the wheel. By offering pre-built components—such as speech-to-text, text-to-speech, noise suppression, webRTC services, LLMs, and more—Switchboard allows developers to focus on their unique value propositions rather than the underlying infrastructure. The cross-platform capabilities of Switchboard are especially important in real-world systems, which often have constraints, such as needing to work offline, and models, therefore, need to run on the device itself.
Imagine a robot or a self-driving car that relied on an internet connection that suddenly glitched out. In reality, hybrid systems and those with hard real time constraints are not easy to build, and AI-generated code is not robust enough for these applications.
Switchboard helps bridge that gap.
Incorporating LLMs in user experiences is quickly becoming tablestakes, but tools to easily integrate them are lacking for many real time use cases. For example, imagine building a voice-based customer service assistant that integrates OpenAI’s real time speech-to-speech capabilities with a VoIP service, noise suppression, on-device transcription, and options for real time language translation. Without a tool like Switchboard, the process would involve significant engineering effort thanks to issues like latency, on-device processing constraints, and more. With Switchboard, it’s a matter of connecting the right modules and letting the framework handle the complexity.
Why Integration is the New Competitive Advantage
In this new landscape, the companies that will thrive are those that can:
1. **Build Quickly: **The faster you can go from idea to deployment, the more competitive you become. Tools like Switchboard enable this agility by reducing development cycles and technical complexity.
2. **Deliver Value at Scale:** Foundational models are only as good as the systems built around them. These systems must translate raw AI capabilities into user-centric experiences that solve real problems.
3. **Leverage Ecosystems:** Companies with existing ecosystems, like Google or Meta, have a natural advantage. For others, partnerships and interoperability become key strategies to embed their AI systems where users already exist.
### Conclusion: The Road Ahead
As foundational models continue to commoditize, the real innovation will come from systems that make AI practical, accessible, and impactful. The next wave of breakthroughs won’t come from a single large language model or image generator but from applications that creatively combine these tools, especially those that help humans leverage them.
Synervoz and Switchboard are at the forefront of this shift. By making it easier to integrate AI into products, we’re empowering developers to focus on what matters most: creating solutions that make a difference. The new frontier is here: building systems that redefine what’s possible with AI.
[Get In touch](/contact)
---
# The Real Constraint in AI Isn’t Intelligence—It’s Economics
> Every business wants customer service to feel like a personal concierge. Few are set up to actually deliver one.
For the past two years, AI progress has been measured in capabilities. Bigger models. Better benchmarks. More impressive demos.
That phase is ending.
We’re entering a different regime — one where the limiting factor isn’t what models can do, but what they cost to do continuously.
## From Capability to Cost
It’s no longer hard to build something impressive in AI. With the right APIs, a small team can assemble a system that feels magical in a demo. What’s much harder is making that system viable at scale.
The moment you move beyond one-off interactions into real usage — real users, real time, real persistence — costs stop behaving nicely. They don’t scale linearly with requests; they scale with time, concurrency, and system complexity.
You can see this most clearly in generative video. The outputs are stunning, but each second of generated content carries a massive compute burden. If usage increases, costs don’t taper — they explode. Unless revenue grows faster than compute, the product breaks (take Sora, for example).
The same pattern shows up in voice. A simple request–response interaction is cheap enough. But continuous voice — always-on listening, streaming transcription, reasoning, synthesis — transforms the problem. You’re no longer paying per request. You’re paying for a system that never stops running.
At that point, the constraint becomes obvious: AI systems don’t fail because they’re not capable enough. They fail because they’re too expensive to run at the level users expect.
## The Hidden Multiplier: Continuous Systems
The industry still tends to think in discrete interactions: a prompt goes in, a response comes out. But the most valuable AI products don’t behave that way.
They are persistent, interactive, and often multi-stream. A voice interface isn’t just handling one input — it’s managing microphone input, background audio, multiple participants, and ongoing context, all in real time. An AI agent isn’t a single call — it’s a loop, continuously observing and acting.
This introduces a hidden multiplier. Costs don’t just increase with usage; they increase with duration and complexity. A system that runs for 30 seconds is fundamentally different from one that runs for 30 minutes, even if they use the same models.
That’s where most architectures start to break.
## Why Cloud-First Starts to Fail
The default approach today is simple: push everything to the cloud and let the model handle it.
That kinda works, until you introduce real-time interaction.
Latency becomes noticeable. Costs become continuous. Synchronization across streams becomes non-trivial. What looked like a clean pipeline in a diagram turns into a fragile system in production.This is why so many AI products feel polished in demos but struggle at scale. The architecture assumes discrete, stateless interactions. The product demands continuous, stateful ones. Those are fundamentally different problems.
## The Shift That Actually Matters
The industry is slowly converging on a new reality: The winning AI systems aren’t necessarily those with the most intelligent models. It’s the ones that can run continuously, cheaply, and reliably.
That shift changes what matters.
Instead of asking how to make models smarter, you start asking when they should run at all. Instead of defaulting to the cloud, you distribute execution across devices. Instead of treating inference as a fixed cost, you make it conditional — escalating only when necessary.
This is less about models and more about orchestration.
## The New Moat
As models commoditize and compute gradually gets cheaper, the real differentiation shifts elsewhere. Not to prompts. Not even to the models themselves.
To architecture.
The teams that win won’t just have access to powerful models. They’ll know how to run complex, real-time systems across devices, under tight latency constraints, without burning through margin. That’s what turns an impressive demo into a durable product.
We’re not leaving the age of intelligent systems. We’re entering the age of **economically viable intelligence**. And that’s a much harder problem.
If you’re building in this space, the question isn’t just what your system can do — it’s whether it can afford to keep doing it.
For a deeper look at how we’re approaching this from a real-time, edge-first perspective, visit [switchboard.audio](https://switchboard.audio/)
---
# The Sound of Audio Programming - Developing Perfect Glitch
> Explore the challenges of audio programming, from identifying and fixing glitches to optimizing DSP algorithms for real-time signal processing. Learn best practices for preventing audio clipping, aliasing, and phase cancellation while developing robust, cross-platform audio applications. Start refining your audio engineering skills today.
Audio programming mistakes can produce very interesting sounds. In this talk we are going to look at these mistakes and even listen to them. We’ll try to identify some of the coding errors solely by ear and develop “perfect glitch”. Some examples that we will examine: clipping, discontinuity, aliasing, phase cancellation, latency issues, buffering problems.
Through practical demonstrations, we will not only listen to these unique sounds but also learn how to recognize them in our own audio projects. Moreover, we will delve into techniques to mitigate and avoid these typical problems.
See more videos on our [YouTube channel](https://www.youtube.com/@switchboard2718).
[Play](https://youtube.com/watch?v=rlMvfFGEj3Q)
[Get In touch](/contact)
---
# The Truth About AI-Assisted Interviews and Why Most Tech Candidates Still Can't Code
> Focused on software for interactive voice and video chat projects with complex audio requirements.
There's a lot of talk about Roy Lee and AI-assisted tech recruiting going around. That story spread fast because it touched a nerve. Not just the scale of what he pulled off, but how familiar it all felt. In my career, I've interviewed hundreds of tech candidates, and I've seen first hand the impact that AI-assisted job interviews have had.
[This article](https://www.mergesociety.com/tech/roy-lee) nailed the core issue: it isn't a candidate problem. It's an interviewer problem. Roy Lee got through because people didn't dig. They accepted the performance. They didn't stay in the conversation.
**A Real Conversation**
The best interviews don't feel like tests. They feel like working sessions. Two people walking through an idea, figuring out what someone really understands.
When you ask someone to explain how they built something, you're not just checking knowledge. You're checking depth. A surface-level answer might sound fine until you follow up. Ask for more detail. Ask how they handled the edge cases. Ask why they made that call. The more you dig, the more the truth shows up.
Everyone hits the bottom eventually. That's not a problem. That's the whole point. A good interviewer knows how to get there without turning the interview into a hostile exercise.
**Where AI Fits**
AI won't fix hiring, and it certainly won't replace good interviewers. What it can do is help all interviewers get better.
Used well, AI can suggest sharper questions. It can flag when a candidate's story contradicts itself. It can keep the conversation moving when a human might get stuck. But it shouldn't make the call. That's still on the person doing the interview.
This is how we see it: AI should make people better at doing hard things. Interviewing is hard. Listening is hard. Adapting is hard. The best tools should support the human in the loop to keep those things going, just like Roy Lee's tools did for the candidate side.
And if a candidate is using AI too? From my perspective, that's fine. They still have to understand what they're saying. They still have to explain it. They still have to stand behind it.
**Still, Some Can't Code**
Even with good questions, there's one truth that never really changes. Some people just can't code.
In my experience, half the candidates applying for developer jobs fall into this category. Not beginners. Not out of practice. They just can't write code.
You don't need a complicated screen or Leetcode to figure that out. A very short live coding session is usually enough. Simple problems, clear expectations. But they need to be able to talk through their work. That's what engineers do day-to-day, after all.
**What Matters**
There will always be noise in hiring. Always some way for people to slip through if no one's paying attention. But the solution isn't more structure for structure's sake. It's sharper interviewers. More curiosity. Better tools. More real conversations.
Roy Lee wasn't the problem. He just showed us where the cracks are.
[Get In touch](/contact)
---
# Token Cost Management Is Becoming an Architecture Problem
> While the AI conversation focuses on models and cloud compute, a parallel shift is underway: AI inference is moving onto the devices we already own, reducing the need to send every task to the cloud.
OpenRouter gives developers a common layer across hundreds of AI models, making it easier to route a request to the model that makes the most sense for the job — based on cost, capability, latency, availability, privacy requirements, or some combination of those things. Stripe now describes this explicitly as optimizing token routing and usage.
That makes sense. You probably shouldn't be sending every request to the biggest and most expensive frontier model.
A simple classification task might go to a small model. A harder reasoning problem might go somewhere else. Some workloads might prioritize latency, while others optimize primarily for cost.
But we think the next step is bigger than model routing.
## The cheapest token may be the one you don't send to the cloud
Models keep getting smaller, faster and increasingly specialized.
That means the decision isn't just going to be:
### Which cloud model should handle this request?
It's increasingly going to be:
Should this request go to the cloud at all?
We wrote more about this in “[The Future of AI Is On-Device](/blog/the-future-of-ai-is-on-device)”.
Things like speech recognition, voice activity detection, embeddings, classification, audio processing, routing, turn detection and increasingly even language-model inference can already run locally in many applications.
You can then reserve expensive cloud inference for the subset of requests that actually need it.
Instead of:
`App → Frontier model`
you start building systems that look more like:
`App → Local model / preprocessing → Router → Cloud model when necessary`
For applications operating at meaningful scale, that can change the economics substantially.
And cost isn't the only benefit.
Running more inference locally can reduce latency, keep sensitive data on the device, reduce dependence on network connectivity and make scaling easier. If 70% of a workload runs on users' hardware, that's 70% of the workload your backend doesn't have to provision infrastructure for.
## Token cost management will become inference management
We think organizations will increasingly optimize across three layers:
* **Which tasks actually require AI inference**
* **Which model is efficient enough for each task**
* **Where that inference should run — device, edge or cloud**
Cloud model routers like OpenRouter solve an important part of that equation.
Hybrid architectures solve the rest.
We've spent years building developer tooling around real-time audio, on-device AI and hybrid cloud/device architectures, and we're increasingly helping companies think about this exact problem.
If your organization is spending thousands of dollars per employee per month on AI, or you're building an application where your users are consuming too many expensive cloud tokens, there's probably a meaningful optimization opportunity.
And it may involve more than negotiating a cheaper API rate.
We can help.
---
# Using the Switchboard SDK to Build a Guitar-Effect App (Video Tutorial)
> Follow Synervoz VP of Engineering Balazs Kiss in this video tutorial to create a guitar-effect app for iOS using the Switchboard SDK. Perfect for developers exploring audio innovation.
In this video tutorial, Synervoz VP of Engineering Balazs Kiss shows viewers step-by-step instructions for how to build a simple guitar-effect app for iOS using the Switchboard SDK. See more videos on our [YouTube channel](https://www.youtube.com/@switchboard2718).
[Play](https://youtube.com/watch?v=4Gj_3DUQwt0)
[Get In touch](/contact)
---
# Virtual Studios, Figma & Online Collaboration for the Creative Industry
> Focused on software for interactive voice and video chat projects with complex audio requirements.
### **Figma: The Gold Standard in Collaborative Design**
Figma has set a high bar for online collaboration, allowing designers to work together in a shared digital space seamlessly. Teams can edit, comment, and brainstorm in real-time, making it ideal for design workflows. But when we shift to audio, video, or interactive media production, latency and synchronization become critical issues, especially for creators working in real-time environments.
### **SyncStage: Tackling Latency for Musicians**
**SyncStage** is one of the pioneering platforms solving the latency problem for remote music collaboration. By creating an environment with **extremely low latency**, SyncStage allows musicians to play together from different locations as if they were in the same studio. This capability is crucial for musicians, as even slight delays can disrupt timing and rhythm. SyncStage is enabling musicians to rehearse, perform, and even create together, pushing the boundaries of what’s possible for virtual studios in music.
### **Meloscene: A Virtual Production Studio for DAWs**
For audio producers who rely on **Digital Audio Workstations (DAWs)**, Meloscene is developing solutions that simulate a **physical studio environment** in a virtual space. This enables users to sync up DAWs, allowing multiple users to interact with the same production session remotely. With Meloscene, producers can collaborate as if they were sitting at the same console, making real-time adjustments without the geographical limitations. This technology brings new possibilities to professional sound production, fostering creativity through seamless collaboration in virtual settings.
### **TribeXR: Virtual DJing in the Metaverse**
**TribeXR** is revolutionizing virtual DJing, offering a platform where users can learn and practice DJing through **VR**. TribeXR’s virtual DJ equipment replicates the real experience, giving aspiring DJs the tools to hone their skills without physical gear. The platform has exciting implications for collaboration, with potential for **collaborative DJ sets in virtual environments**, letting DJs around the world perform together or teach one another in real-time. As the metaverse continues to expand, TribeXR’s approach represents the future of interactive music education and live performance.
### **The Challenges of Real-Time Collaboration in Audio**
Unlike design collaboration, where immediate response time isn’t essential, audio and music collaboration require **ultra-low latency**. Any lag in audio response disrupts rhythm and flow, essential elements in musical performance and production. Platforms like SyncStage and Meloscene are addressing these challenges with **specialized algorithms** and **network optimizations**, allowing creators to interact in real-time.
### **Virtual Studios: A Look Ahead**
As remote work continues to shape creative industries, the demand for collaborative virtual studios will only grow. From **real-time music creation** to **DJ sets in virtual spaces**, platforms like SyncStage, Meloscene, and TribeXR are paving the way for a new era of online collaboration. By overcoming the constraints of latency and introducing tools tailored to audio and video, these platforms are helping to bridge the gap between physical and virtual studios.
The future of creative collaboration is moving beyond the screen, offering **immersive, shared environments** where audio professionals can create together, no matter where they are in the world.
[Get In touch](/contact)
---
# Voice AI for Mobile Apps: Companions, Tutors, Fitness Coaches and More
> Voice AI can make mobile apps more natural and engaging by powering companions, tutors, fitness coaches, interactive characters, and hands-free experiences.
There's a much broader category of apps where voice just makes sense: AI companions you can talk to naturally, language tutors you can actually practice with, fitness coaches that guide you through a workout, characters you can interact with, or existing apps that are simply easier to use when your hands or eyes are busy.
For developers, the interesting question is becoming less "**Can I add voice AI?**" and more "**Where would voice actually make my app better?**"
Here are a few places where we think the answer is pretty obvious.
## Voice AI for fitness apps
Fitness is a great fit for voice because looking at and touching your phone is often exactly what you don't want to be doing.
Imagine talking to a coach while running or working out:
"What's my next exercise?"
"Give me another 30 seconds."
"That was too heavy. Drop the next set by ten pounds."
The AI can answer while also calling functions inside the app to change timers, log workouts, modify exercises, or pull up information.
That makes the app feel less like something you operate between sets, and more like a coach that's actually there with you.
It's also a good example of where **hybrid Voice AI** gets interesting. Something like "start my timer" probably doesn't need a frontier model running in the cloud. That can potentially happen locally, while more complicated questions get routed to a cloud model.
## Voice AI for language-learning apps
Language learning might be an even more obvious use case. If you're trying to learn a language, you need to actually speak it.
Instead of recording a sentence, submitting it, and waiting for feedback, you can just have a conversation with an AI tutor.
That also means dealing properly with the messy parts of human conversation:
**Tutor**: What did you do this weekend?\
**User**: Je suis allé au... uh...
The tutor shouldn't immediately assume you're finished because you paused for half a second. Especially when you're learning a language, pauses, corrections, and half-finished thoughts are part of the experience.
And because the AI can call into the rest of the app, the conversation doesn't have to live in a vacuum. It can save vocabulary, show corrections, adjust the difficulty, or move you into another lesson.
At that point, voice isn't really an add-on anymore. It's part of the interface.
## Voice AI for companions and characters
Companion apps, virtual characters, and conversational games are a little different because the conversation itself is often the product.
Here, latency and turn-taking matter a lot.
If the AI is halfway through a long response, you should be able to say:
"Wait, that's not what I meant."
and have it stop and listen.
That sounds simple, but getting interruptions, echo cancellation, turn detection, and mobile audio working well together is a surprisingly large part of making a voice agent actually feel natural.
That's one of the reasons we built our open-source [OpenAI Realtime Toolkit](https://github.com/switchboard-sdk/openai-realtime-toolkit) for React Native. It handles a lot of that plumbing around OpenAI's Realtime API so developers can spend more time on the actual experience.
The same problems come up with AI NPCs, kids' characters, interactive stories, meditation coaches, and plenty of other conversational apps.
## Voice as a hands-free interface
There's also a much bigger category that doesn't necessarily need an AI personality at all.
Cooking apps. Navigation. Field-service software. Travel apps. Automotive apps. Accessibility tools. Productivity apps.
Basically, anything you might want to use while your hands or eyes are busy.
Instead of tapping through menus, you can just say:
"What's next?"\
"Read that again."\
"Skip this step."\
"Show me the photo."\
"Add that to my list."
The LLM handles the language, and tool calls connect that conversation to what the app can actually do.
It's a pretty natural extension of the interfaces these apps already have.
## Not everything needs to go to the cloud
This is probably the part we're most interested in.
Developers increasingly don't have to choose between **cloud AI** and **on-device AI**. You can mix the two.
Phones are now capable of running speech recognition, voice activity detection, text-to-speech, and increasingly capable small language models locally.
So you can keep fast, frequent, or predictable interactions on the device, and use bigger cloud models when they're actually useful.
***
A fitness app might handle:
***"Start my timer."***
entirely on-device, while sending:
***"Can you change today's workout because my legs are still sore from Monday?"***
to a cloud LLM.
***
A language tutor might do speech recognition and text-to-speech locally while using a cloud model for the conversation itself.
A companion might use local processing to figure out when you've started and stopped talking, while a realtime cloud model handles the character.
That's what we mean by **hybrid Voice AI**. It's not really about replacing the cloud. It's about not sending everything to the cloud just because that's where the LLM happens to live.
That can mean lower latency, lower inference costs, better offline behavior, and more control over what data leaves the device.
A few tools for building this
We've open-sourced a couple of the pieces we've been using to make these kinds of apps easier to build.
### [EdgeSpeech](https://github.com/switchboard-sdk/EdgeSpeech)
Gives React Native developers a simple interface for running speech processing directly on the device.
### [OpenAI Realtime Toolkit](https://github.com/switchboard-sdk/openai-realtime-toolkit)
Handles the mobile audio and conversational plumbing around OpenAI Realtime, including things like echo cancellation, turn detection, interruptions, and tool calling.
### [Switchboard](https://switchboard.audio/cases/voice-ai/)
Is the broader framework we've built for connecting all of this together: real-time audio graphs where on-device components and cloud AI services can be mixed and matched.
Fitness coaches, tutors, companions, and characters are some of the obvious applications.
But the more interesting question is probably: **what apps become possible when talking to software starts to feel as natural as tapping it?**
---
# Voice AI Isn’t Just Changing How We Talk to Machines
> Voice AI isn’t just improving interfaces. It’s reshaping online presence by enabling real-time, drop-in interaction, shifting the internet from passive consumption back toward shared moments, coordination, and genuine human connection.

## It’s Changing How We Talk to Each Other
Most conversations about Voice AI focus on the future of **Human–Machine Interaction**. The promise is familiar: more natural interfaces, faster input, fewer screens, better assistants. Speak instead of type. Ask instead of click.
But that framing misses the more important shift already underway.
The real impact of Voice AI won’t be how we talk to machines. It will be how machines quietly reshape how we talk **to each other**.
At the surface level, voice changes habits. Talking is faster than typing. It carries tone, emotion, timing. It nudges people away from carefully constructed messages and toward something more spontaneous and human. When voice becomes normal, people simply talk more — and text less. That alone is a meaningful behavioral change.
But go one layer deeper and something more interesting emerges. Voice doesn’t just replace input methods; it subtly pulls the internet back toward **real-time presence**. For the last two decades, our digital lives have been optimized for asynchronous behavior: scrolling, liking, commenting, reacting. These systems scale beautifully, but they quietly push people into passive observation rather than participation. You don’t hang out online anymore — you watch other people do it.
Voice changes that gravity.
Once voice is ambient and easy, interaction stops feeling like a task. It becomes something closer to dropping in. A quick check-in. A shared moment. And when you add AI into that loop, the system no longer just responds — it **coordinates**. An assistant doesn’t just answer questions; it notices when people are available at the same time. It can suggest when to drop in, or help to schedule future times that work for both of you. It can help you figure out what to watch or play in the moment and alert you about future events to get together for. It lowers the friction of getting together and figuring out what to do.
This is where **Human–AI interaction starts influencing Human–Human interaction**.
Instead of AI being the destination — the thing you talk to — it becomes connective tissue. It helps you find the right people at the right time while helping to curate what you can do or create together.
We already know this pattern works because we’ve seen it before — just in narrower contexts. Gamers have lived in this world for years. Voice chat, drop-in sessions, shared activity spaces, real-time coordination. What’s changing now is that this behavior is escaping the gaming bubble and moving into more platforms and use cases.
Platforms like **Discord Activities** made it obvious that people don’t just want to talk — they want to **do things together while talking**. Watch something. Play something. Mess around with media. And products like [Kosmi](https://kosmi.io/) are pushing this even further, experimenting with spaces where humans and AI interact together around content in real time. The media player itself becomes social. AI isn’t replacing the group; it’s participating with it, shaping the experience as it unfolds. It can also generate content on the fly, allowing people to create and consume highly personalized media and shared experiences.
This shift matters because real-time interaction solves many of the problems we’ve quietly accepted as “normal” online behavior. Doomscrolling. Silent consumption. Low-grade loneliness disguised as engagement. Async systems are great at filling time, but terrible at creating presence. Real-time systems do the opposite — and until recently, they were expensive and hard to scale.
AI changes that equation.
If AI can handle coordination, discovery, suggestions, and logistics invisibly, then **real-time no longer feels heavy**. You don’t need to plan. You don’t need to schedule weeks in advance. You just show up when it makes sense — together.
There’s also something strangely familiar about this future. It feels closer to how the internet felt in the 90s and early 2000s, before feeds and metrics dominated everything. Smaller groups. Live conversations. Shared moments that didn’t need to be archived or optimized. Voice-first, real-time systems bring back some of that texture — but with modern infrastructure, global reach, and intelligence layered underneath.
This is why the biggest opportunity in Voice AI may not be assistants, search, or productivity at all. It may be **social primitives**: presence, availability, co-experience, drop-in interaction. Whoever figures out how to own those layers won’t just build better products — they’ll reshape how being online feels.
Voice AI won’t just change how we talk to machines.
It will change who we talk to, when we talk, and how often we actually show up for one another.
And that might end up being one of the most positive shifts the internet has seen in a long time.
## Ready to Start Building?
[Explore the Switchboard SDK](https://switchboard.audio)
---
# Voice is the Interface
> Voice interfaces have rapidly evolved in 2025, moving from novelty to necessity across consumer and enterprise applications. This post explores the technological breakthroughs, UX challenges, and shifting user expectations shaping this transformation.
Voice technology has promised “natural” human-computer interaction for years, yet true voice-first experiences remain rare. Why? Historically, voice user experience (UX) has lagged behind expectations due to latency, friction, and privacy hurdles. Unlike tapping a screen, speaking to an app often introduces a noticeable delay from spoken word to action, and any delay over about a second can feel sluggish. In conversation, humans expect near-instant responses (we naturally pause only \~200-500 ms between turns). Long processing times or awkward pauses break the flow, leading to frustration. Early voice interfaces also imposed cognitive friction: users weren’t sure what commands were possible, how to phrase them, or whether the system was even listening. In short, using your voice often felt harder than using your fingers, especially when feedback cues were unclear and errors were common.
Privacy concerns have further dampened adoption. “Always-on” microphones spook many users; *40% of voice assistant users worry about who might be listening and how their voice data gets used*. Incidents like smart TVs or voice devices accidentally recording sensitive conversations have made the public understandably wary. Unless companies are totally transparent about data practices, they risk scaring people off. For developers, handling voice data also raises compliance burdens: ensuring consent before recording, securing transmissions, and limiting retention are now table stakes. These challenges (latency, UX friction, privacy) help explain why voice interfaces often felt clunky or “not ready” until recently.
Compounding the issue is that most applications have treated voice as a bolt-on feature rather than a primary interface. We’ve seen countless apps where voice control is an afterthought; a novelty command or a basic speech-to-text input added to a touch-centric design. This bolt-on approach misses the transformative potential of voice. As [*an insight from Bessemer Venture Partners*](https://www.bvp.com/atlas/roadmap-voice-ai) put it, *“Voice AI isn’t just an upgrade to \[software’s] UI; it’s transforming how businesses and customers connect.”* In other words, voice isn’t merely a new button or menu, it’s a fundamentally different mode of interaction that demands its own design paradigms. Treating voice as secondary often leads to awkward experiences: apps that make you hit a tiny mic icon, speak a command, then revert to tapping because the voice flow isn’t fully thought through.
Meanwhile, speech recognition technology itself has made huge strides, we now have near-human-level accuracy from advanced AI models, but the surrounding infrastructure is lacking. Modern speech models like deep-learning ASR (Automatic Speech Recognition) can transcribe or understand speech far better than systems a decade ago. For example, open-source models like OpenAI’s Whisper (released 2022) demonstrated robust transcription of accents and noisy audio , and Google’s Conformer architecture significantly improved accuracy on real-world speech while staying efficient . However, simply dropping these powerful models into an app doesn’t solve the end-to-end problem. Developers quickly discover that building a real-time voice application requires a lot beyond the speech-to-text or text-to-speech model itself. You need streaming audio pipelines, wake-word detectors, voice activity detection, low-latency networking, error-handling mechanisms, and more. As one commentary noted, the adoption of speech tech has been limited by privacy, latency, and affordability challenges, despite the accuracy improvements. The cloud-centric infrastructure of early voice apps introduced too much latency and risk, and moving to more private, on-device processing isn’t trivial given device CPU/memory constraints. In short, the ecosystem has lacked a dedicated audio runtime; a layer that treats the continuous, real-time nature of voice as a first-class citizen. Instead, developers have been left to stitch together point solutions (ASR API here, wake-word SDK there, some DIY audio threading) and hope it works smoothly. It often doesn’t.
The good news is that we stand at an inflection point. Key problems are being solved (or at least seriously addressed) by a new wave of AI advancements and platforms. It’s becoming feasible to design applications where voice is the primary interface, not a gimmick, but the core interaction mode. In this whitepaper, we’ll explore how “voice is the interface” is turning from aspiration to reality, powered by AI breakthroughs. We’ll look at real-world use cases across consumer, enterprise, and industrial domains to ground the discussion. We’ll examine hard numbers on market growth and technical performance to quantify the opportunity. Then we’ll dive into strategic implications: what recent model advancements and infrastructure developments mean for builders, why we likely need an audio-first tech stack, and how to design for the messy realities of human conversation (like interruptions and context). Finally, we’ll address the ethical dimension, from user consent to data retention, and conclude with practical takeaways. The overarching message is that voice interfaces are poised to be a foundational shift in computing, not a niche trend, and those building in this space must approach it with both excitement and clear-eyed pragmatism.
## **Three Real-World Narratives: Voice in Action**
To illustrate why voice-first applications are so compelling, consider three short scenarios in different domains each highlighting how AI-driven voice interfaces can shine where traditional UIs fall short.
### **Consumer: Voice Shortcuts in Everyday Mobile Life**
*It’s 6 PM and Maya is elbows-deep in a recipe, her phone propped up nearby. With sticky hands, tapping and swiping is out of the question. “Hey, skip to the next step,” she says aloud. Her cooking app obliges, reading the next instruction. A few minutes later, the food is simmering but her toddler is getting antsy. “Text Jason: Dinner in 10, please set the table,” Maya calls out. Her phone recognizes the command, sends the text, and even announces the reply from Jason when it arrives. Later that evening, Maya unwinds with a mobile game. Instead of navigating menus to trigger her favorite combo move, she simply says “Fireblast” (a custom voice macro she set up) and the game instantly executes a series of actions that normally require multiple taps.*
This scenario is becoming possible because voice is finally moving from a novelty to an integral part of the mobile UX. Platforms are starting to support voice macros or shortcuts that let users chain complex actions to a simple spoken phrase. In fact, Google has been working on an “Assistant Shortcuts” feature to let users create voice macros for third-party apps. Apple’s Siri Shortcuts similarly allows custom voice triggers for app actions. The idea is to let users fluidly control apps by voice, beyond the canned commands that developers hard-coded. For consumers, this can mean saving time and reducing frustration; especially in contexts like cooking, driving, or gaming where hands-free control is a game-changer.
Yet, most mobile apps today still treat voice as a bolt-on. They might allow dictation in text fields or a limited set of voice commands, but few rethink the app’s flow around voice. The opportunity (and challenge) ahead is to design apps that are *voice-first* when appropriate, meaning the primary way to navigate could be speaking, with the visual interface as backup. This requires not just speech recognition, but also smart UX design to guide the user on what commands are available (solving the “knowledge black box” issue where users don’t know what they can say). It also requires keeping latency low so the interactions feel instant. In our narrative, note that Maya’s commands (“skip to next step,” “text Jason…”) were responded to immediately. If she had to wait 3-4 seconds each time, she might as well have washed her hands and tapped the phone; the magic would be lost. For consumer voice interfaces, milliseconds matter; a smooth experience depends on tight integration of ASR, app logic, and feedback cues. When done right, voice becomes like a conversational shortcut; it feels like the app *understands* your intent and acts, without you laboriously navigating menus or forms. Done poorly, it feels like yelling at a stubborn robot. The next generation of consumer apps will need to close that gap. Companies should watch how platform-level voice capabilities (like Google’s Assistant APIs or Apple’s on-device speech recognition improvements) evolve, because these can enable richer voice interactions inside third-party apps. The key is to identify where voice actually improves UX (e.g. quick, context-specific commands or hands-busy situations) and focus voice features there, rather than trying to voice-enable every single action in a clunky way.
### **Enterprise: AI That Listens in Meetings and on Calls**
*A project manager, Alex, joins a Zoom meeting with a big client. Instead of scrambling to take notes, Alex relies on an AI meeting assistant running in the background. Throughout the call, the assistant transcribes the conversation in real time and highlights key decisions and action items. Five minutes after the meeting, Alex receives a neatly formatted summary in their email (key discussion points, commitments, deadlines) all prepared by the AI. Meanwhile, in a different department, a call center supervisor reviews analytics from last week’s customer support calls. An AI system has automatically listened to every call, flagged ones where customer sentiment turned negative, and even scored each agent on a quality rubric (politeness, script adherence, issue resolution). This would have taken a human QA team weeks, but the AI evaluated 100% of the calls overnight. Armed with these insights, the supervisor coaches the team on specific areas for improvement.*
This narrative shows voice AI addressing two huge enterprise needs: meeting productivity and call quality assurance. These are real trends. Meeting transcription and summarization tools have exploded in popularity: roughly 24% of enterprises have adopted AI meeting summarization as a use case, ranking it among the top emerging applications of generative AI. The payoff is obvious: professionals reclaim the time and cognitive load of note-taking, and nothing gets forgotten. Products like Fireflies, [*Otter.ai*](http://otter.ai), and others join platforms like Zoom and Microsoft Teams in offering live transcripts and summaries. The technology has matured to the point where speech-to-text is accurate enough and large language models are smart enough to extract salient points from an hour-long discussion fairly reliably. This is a big step forward for voice interfaces in the workplace: the AI isn’t just taking dictation, it’s listening and understanding context well enough to produce useful output (summaries, action items). It’s easy to imagine this going further: real-time “chapter markers” in a long meeting, voice assistants that proactively surface relevant documents when a project is mentioned, etc. Voice becomes a two-way interface here: humans speak, the AI listens and provides synthesized outputs or even suggestions.
In customer support and sales, voice analytics are transforming how calls are monitored and improved. Traditional call QA involved managers randomly sampling a few calls per agent (often less than 5% of interactions) due to sheer volume. AI-driven voice analysis flips this model on its head. Now every single call can be transcribed and evaluated, which means 100% coverage in quality monitoring. As Zendesk describes, AI can flag problematic cases and uncover trends that humans would miss, simply because it can listen to and analyze all interactions without fatigue. This yields tangible business value: ensuring compliance with scripts or policies, identifying customer pain points, and highlighting coaching opportunities for agents. Several startups and enterprise solutions offer “conversation intelligence” that scores calls, detects sentiment, or even gives real-time guidance to agents (“The customer sounds frustrated, try a different approach”). In effect, voice AI turns unstructured conversations into actionable data at scale.
From a strategic viewpoint, these enterprise examples highlight that speech models alone aren’t enough: it’s the surrounding workflow integration that makes them valuable. The meeting summarizer needs to plug into calendar and email systems (so summaries are delivered to the right place and tied to the meeting event). The call analytics need to integrate with CRM or support ticket systems, and present insights in dashboards managers can use. Latency is less of an issue here (it’s fine if the summary arrives a few minutes later, or QA reports are overnight), but accuracy and reliability are paramount. If the summaries hallucinate incorrect decisions, or the QA scoring model is biased or inconsistent, users will not trust it. Therefore, domain-specific tuning and transparency become important, e.g. letting users review the transcript segments that led to a certain summary or QA flag, to verify context. Even with these challenges, the trend is clear: voice is becoming a primary data source in enterprise settings, not just something for voice assistants to handle trivial tasks. Meetings, calls, interviews, presentations; so much vital business knowledge is exchanged via spoken words. AI finally gives us tools to capture and leverage that knowledge at scale. Product leaders in enterprise software should treat voice as a first-class modality, ensuring their apps can ingest and output audio (not just text) and building in features that assume speech is a default input for busy professionals. The companies who get this right will deliver huge productivity gains and likely differentiate their offerings in terms of user experience.
### **Industrial: Hands-Free on the Frontlines**
*On the factory floor, a maintenance technician named Priya is repairing a large piece of equipment. It’s noisy, her hands are occupied with tools, and safety is a concern; she needs to keep her eyes on the task. Equipped with a rugged headset, Priya can simply speak to log her actions and access information. “Replaced valve A, now closing pressure release,” she dictates, and the system transcribes the update into the maintenance log in real time. When a question comes up, she asks the voice assistant, “What was the torque spec for this bolt again?” Immediately, the headset reads out the specific value from the manual. Across the site, other technicians are doing similar hands-free logging: updating job statuses, creating voice memos of issues to check later, all without stopping work. Supervisors see live updates streaming in, and when Priya finishes, the job report is essentially already written by the AI from her voice notes.*
This industrial scenario underscores how critical voice interfaces can be in environments where using a touchscreen or keyboard is impractical. Here, voice is the primary interface by necessity: it lets workers remain heads-up and hands-free. A growing number of field service and industrial companies are exploring voice-activated solutions for exactly these reasons. Voice-activated field software can allow technicians to control their mobile apps and data systems with spoken commands, without lifting a finger. The benefits are measurable: increased efficiency (no need to stop work to type), improved accuracy (less after-the-fact data entry, more real-time capture), and even enhanced safety (workers keep their eyes and hands on the task, not on a device).
For instance, one field service report describes a plumber updating job status and retrieving information via voice while repairing a leak, instead of pausing to manually input data. Another common use is for technicians to fill out inspection or maintenance forms via dictation: the system can guide them via voice prompts and record their spoken answers, which is far faster than writing on paper or typing on a tablet in the field. Companies like those in HVAC, utilities, or manufacturing maintenance see voice interfaces as a way to streamline workflows and reduce error rates. People are less likely to “forget” to log a step if they can just say it as they do it. And by integrating voice systems with back-end databases (asset management systems, CRM, scheduling tools), an update spoken by a tech can instantly reflect in inventory or job queues , keeping everyone in sync.
There are challenges to overcome here too. Industrial environments can be noisy, which means speech recognition must be robust to background sounds. Specialized vocabulary or jargon may require custom language models or tuning. Connectivity can be an issue in remote sites; the voice solution should ideally have offline capabilities or at least local buffering so it doesn’t lose data if the network drops. Additionally, user training is non-trivial: some workers may be set in their ways and hesitant to trust an AI system. Successful deployments often involve change management, good UX design (making the voice assistant’s prompts and confirmations clear but not annoying), and fallback options if voice fails (the worker needs a backup method to complete the task if the system doesn’t understand after a couple tries).
Despite these hurdles, the direction is clear. Just as consumer and office apps are being reimagined with voice, so too are industrial workflows. In fact, the stakes can be even higher in these scenarios: a voice interface that saves 5 minutes per service job or prevents one safety incident by keeping a worker’s focus on their surroundings can justify itself quickly. We can expect AI advances to further enhance these use cases: imagine an on-site voice assistant that not only transcribes what the tech says but intelligently checks for consistency (“Did you also perform the pressure test? I didn’t hear it mentioned”) or even listens to the machine sounds to detect anomalies. We’re heading toward an era of ambient intelligence on the job, and voice is the key interface to make it practical. For companies building products in field service, construction, manufacturing, etc., it’s time to consider an audio-first UX. The old paradigm was clipboards and later mobile apps; the new paradigm is a virtual assistant that’s part of the toolkit, listening and helping in real time.
## **Voice by the Numbers: Market Growth and Technical Benchmarks**
The qualitative benefits of voice interfaces are compelling, but it’s also important to look at the data. Voice AI is big and getting bigger, in terms of market size, user adoption, and technical capability. Here we provide some quantitative context to ground the strategic outlook:
* **Market Explosion**: The market for voice-based AI technologies is growing at a staggering pace. Analysts project the global voice recognition and voice AI sector to expand from roughly $18 billion in 2025 to nearly $78 billion by 2032, a \~22.9% CAGR. Another estimate focused on “voice AI agents” (conversational agents handling calls, etc.) foresees tens of billions in value by the early 2030s. The drivers are ubiquitous: rising demand for contactless interfaces (spurred in part by the pandemic), proliferation of smart devices with built-in voice, and enterprise investment in automation of voice communications. Voice is not a niche interface reserved for smart speakers anymore; it’s becoming a standard expectation across devices and industries.
* **Device and User Adoption**: A few years ago, having a voice assistant in your home felt futuristic; now it’s commonplace. By 2025 there are an estimated 8.4 billion digital voice assistants in use globally, which actually exceeds the human population. This count includes smartphone-based assistants (Siri, Google Assistant), smart speakers (Alexa, Google Home), in-car systems, and more. It’s double the number from just 2020. On the user side, about 20% of people worldwide use voice search or voice commands actively (a figure that had spiked slightly higher during 2022 and settled around one-fifth of internet users). In the United States, roughly 36% of the population uses voice assistants in some form , and in certain demographics (e.g. younger users or smartphone owners), the rates are even higher. These stats underscore that voice interfaces have already achieved broad consumer penetration. They are not an early-adopter curiosity; they are mainstream. The trend is similar in enterprise: for example, millions of hours of customer service calls are now handled by AI voice systems annually, and many large companies have at least pilot programs for AI transcription or voice bots. Investors are pouring money into voice tech startups, and incumbent tech companies are racing to integrate voice capabilities into their platforms.
* **Latency and UX Expectations**: We’ve mentioned how critical latency is for voice UX. Let’s quantify that: if a voice assistant’s response latency exceeds about 1 second (1000 ms), users often perceive it as a poor experience Ideally, responses should approach human conversational latency (200-500 ms). For comparison, human turn-taking in conversation often has only a quarter-second gap. Achieving sub-second system responses end-to-end is extremely challenging; it means speeding up speech recognition, language understanding, and response generation, and possibly doing some of these in parallel. Recent model and infrastructure improvements have cut down latency significantly: OpenAI’s GPT-4 Turbo (a model optimized for speed) and similar efforts have shown it’s possible to nearly halve the response time of typical cloud AI services. However, hitting human-level latency consistently still requires heavy optimization and clever engineering (streaming inference, efficient codecs, etc.). This is why companies are increasingly exploring on-device processing to eliminate network delays. When computation happens locally, you remove the round-trip to a cloud server, which for a spoken query could easily be 200-500 ms of network time. One blog from a voice AI provider notes that on-device speech recognition eliminates network latency and can even run faster than cloud if the model is lightweight enough. Indeed, Amazon has reported that executing voice tasks on-device (for Alexa) required compressing models to <1% of their original size to fit on a device, but yielded huge latency and bandwidth improvements. The takeaway: users increasingly expect voice interactions to be real-time (think a back-and-forth conversation, not a walkie-talkie). Achieving ultra-low latency (<300 ms responses) is a crucial technical target, and it’s driving architectural changes (discussed later) like moving from cascading voice pipelines to end-to-end speech-native models.
* **Accuracy and Model Size Trade-offs**: Thanks to AI advances, speech recognition accuracy is now generally above 90% for many use cases, and in some benchmarks, ASR is approaching human-level word error rates. OpenAI’s Whisper model demonstrated state-of-the-art accuracy on diverse speech, but it’s too heavy to run on most mobile devices in real time (Whisper large has \~1.5 billion parameters). There’s a push toward lightweight ASR models (those that can run on device or with minimal cloud resources) without sacrificing too much accuracy. Google’s Conformer-based models are one example of optimizing for both accuracy and efficiency. AssemblyAI’s Conformer-1 and -2 models trained on huge datasets achieved robust performance on real-world audio and also benefited from engineering that reduced inference latency by \~50% compared to prior models. We’re also seeing creative approaches like knowledge distillation and quantization to shrink model size. The need to handle voice on mobile CPUs (or specialized NPUs) forces these optimizations. Another aspect of “accuracy” is not just transcription correctness, but understanding user intent correctly (which might involve NLU after transcription) and handling ambiguous input. Metrics for that are harder to pin down but crucial. The bottom line is that the quality of voice AI outputs (transcriptions, responses, etc.) has improved dramatically, making voice interfaces viable where they once failed. But ensuring those models can run under real-world constraints (memory, CPU, cost) is an ongoing balancing act. Product builders must consider model size and deployment carefully, for instance, a 500MB model running in the cloud might give great accuracy but could be too slow or expensive at scale, whereas a 50MB edge model might be snappier and private but potentially less accurate. Finding the sweet spot (or using a hybrid approach) is part of the strategy now.
* On-Device vs Cloud Trade-offs: This is a quantitative and strategic consideration. Cloud speech services (Google STT, Azure, etc.) often boast the highest accuracy and easy scalability, but they come with latency overhead and privacy concerns of streaming user audio to a third party. On-device speech recognition ensures privacy by design (data stays on the device) and can work offline, which is a big plus. It also avoids cloud fees. The trade-off is that the device must handle the CPU load, and models may need to be simplified. However, it’s noteworthy that modern techniques have made it possible for on-device models to rival cloud quality in many cases. Enterprises and developers are increasingly aware of these trade-offs. For latency-critical or privacy-sensitive applications (say, a smart home device or a medical app), on-device or on-premise voice AI is highly desirable. For scenarios requiring heavy-duty language reasoning or large context (like a complex assistant conversation), a cloud LLM might still be needed in the loop. The quantitative point here is that hardware is a limiting factor: edge devices have limited memory and battery. We’re seeing investments in more efficient algorithms and even specialized AI chips for voice to push the frontier.
In summary, the numbers paint a picture of voice interfaces coming into their own. Billions of devices are listening, a significant chunk of users engage with voice daily, and the market is surging with investment. Technically, the gap between what users expect (fast, accurate, seamless voice interaction) and what’s possible is closing. But to truly capitalize on this, we need more than just big models and a large market opportunity. We need to rethink how we build applications for voice.
## **Strategic Observations: Building for an Audio-First Future**
The rise of voice as a dominant interface isn’t happening in isolation, it’s the result of convergence in AI research, developer tooling, and user experience insights. Here are some key strategic observations about where the ecosystem is heading and what it means for anyone looking to build audio-first applications:
### **1. Model Advancements Are Pushing the Ecosystem Forward**
We’re witnessing a flurry of AI model improvements that directly benefit voice applications. Large speech models (like Whisper, released in late 2022) set new benchmarks for transcription quality and multilingual support. Transformer-based architectures like Conformer have improved noise robustness and accuracy while keeping models efficient. Importantly, these cutting-edge models are not just academic exercises; they are being open-sourced or made available via APIs, allowing developers to build on top of them quickly. For example, Whisper’s open-source release meant any developer could incorporate near state-of-the-art ASR into their app without a huge research budget, and indeed many did. Likewise, we’ve seen open-source text-to-speech models that produce uncannily human-like voices, and even early speech-to-speech translation models. This democratization of model access accelerates innovation in voice UX.
Beyond individual models, there’s a broader architectural shift under way: moving from the traditional cascading pipeline (ASR → NLP/LLM → TTS) toward more integrated or speech-native approaches. The classic pipeline has been effective, but as noted earlier, it has drawbacks in latency and loss of rich audio context. The next generation of models aims to handle speech end-to-end or in a multimodal fashion. For instance, new research into Speech-to-Speech (STS) models keeps the data in the audio domain throughout, enabling ultra-low response times (\~300 ms) and preserving nuances like tone and the ability to handle interruptions. OpenAI’s recent demonstration of a multimodal GPT-4 (sometimes referenced as GPT-4o) that can natively ingest and output audio is a bellwether. If an AI can “listen” and “speak” in one unified model, we no longer have to bolt together separate services, potentially reducing latency and making the interaction more fluid.
Another trend is model specialization and size optimization. Not every voice task needs a giant 20-billion-parameter model. As Bessemer’s Voice AI roadmap highlights, there’s excitement around *smaller, targeted models* that can handle straightforward conversational turns quickly, without invoking a massive, general model for simple tasks. For example, a small on-device model might handle a wake-word detection and a simple command like “volume up” entirely locally, while a cloud model handles a complex query. This hierarchical approach can cut costs and latency. Developers will increasingly have the option to orchestrate multiple models: maybe a local model does initial intent recognition and only if it’s a complex request does it call out to a more powerful cloud model. Model advancements are giving us the pieces; the strategic question is how to compose them optimally for a given use case.
In essence, the AI research community is solving many of the historical blockers for voice interfaces; accuracy in noisy conditions (Whisper and Conformer made leaps there ), fast inference (distilled and quantized models), multilingual capabilities, and even emotional expressiveness in generated speech. This creates a ripe environment for product innovation. Those building voice-first apps should track the latest model releases closely; what was impossible a year ago might be feasible now (for example, real-time translation of a phone call, or on-device transcription of meetings). And one need not invent these models from scratch, it’s often about smart engineering and integration of what’s available.
### **2. Beyond Models: The Need for a Dedicated Audio Layer and Runtime**
While models are critical, a great voice application requires a lot more than high accuracy speech recognition. It requires a real-time audio pipeline that handles the messy details of audio streaming, synchronization, and user interaction. Many developers learned this the hard way: you can’t just call an ASR API and call it a day if you want a truly conversational experience. You need an architecture that treats audio as a first-class citizen.
Consider the problem of interruptions in conversation. If the user tries to barge in while the AI is speaking, a naive system won’t handle it; the ASR might still be off or the system might ignore the interjection. A robust voice runtime will include components like Speech Activity Detection (VAD/SAD) to constantly monitor the mic input even while the system is responding, so it can detect that the user started speaking. It then needs logic to pause or stop the TTS playback and listen, essentially enabling a dynamic, overlapping conversation. Achieving this requires tight coupling between the audio playback system and the speech recognition system; they can’t be in separate silos. ChatGPT’s new voice mode, for instance, was successful in large part because OpenAI built an integrated stack where the TTS is interruptible and the system maintains context even if the user jumps in mid-sentence. Most off-the-shelf voice services don’t handle that for you; a custom runtime is needed.
Another example: “end-pointing” detection: figuring out when the user has finished speaking a query, especially if they didn’t explicitly press a button or say a clear trigger word at the end. Many ASR engines, if given an open mic, either use a fixed timeout or struggle if the user hesitates mid-sentence. Developers often end up building their own end-of-speech detectors to make the experience snappier (not waiting too long after the user stops talking) and more reliable. Similarly, filtering out background noise or doing echo cancellation (so the system doesn’t confuse its own voice output as user input) are decidedly non-trivial problems. They land squarely in the realm of audio engineering and signal processing, not just AI algorithms. A well-designed audio-first platform will provide these capabilities as part of the runtime.
We’re starting to see voice-focused developer platforms emerge to fill this gap, essentially acting as the “game engine” for voice apps. They aim to abstract away the low-level difficulties of streaming audio, managing state, and scaling real-time voice interactions. For example, some platforms handle the telephony integration, transcription, and even respond with filler “ums” to hold the conversation if a backend call is slow. Others provide tools for conversational flow control, so a developer can script certain dialogues and have a deterministic path when needed (vital in use cases like healthcare or finance where certain checks must occur in order). The point is, building a voice app from scratch is still hard: it’s akin to building a real-time operating system that juggles audio I/O, multiple AI services, and a conversation state that could change any second. You wouldn’t reinvent a graphics engine to make a video game, you’d use Unity or Unreal; similarly, new voice runtimes offer higher-level constructs tailored for speech interactions.
For organizations planning to develop voice-first products, it’s wise to consider these platforms or frameworks rather than trying to bolt together your own solution entirely. Using a dedicated audio layer can drastically reduce development time and improve quality. These systems are built to handle issues like *latency spikes* (e.g. switching to a backup ASR if the primary one fails or is slow ), *scalability* (keeping audio streams in sync when you have hundreds of concurrent calls), and *observability* (logging and debugging conversations, which is a new challenge; it’s not like debugging a web app). The best voice experiences today (like some advanced virtual agents in customer service) benefit from such an orchestration layer behind the scenes, ensuring that the AI’s performance translates into a smooth user experience.
In summary, developers need an audio runtime, not just AI models. Neglecting this is like having a great engine with no chassis or wheels for your car. The strategy should involve evaluating what infrastructure to build in-house versus what to leverage from emerging voice platforms. Much like cloud revolutionized web app development by abstracting server management, these voice runtimes will abstract audio management. Those who adopt or build them will be able to spend more time on what the voice application *should do* rather than fighting the how.
### **3. Designing for Context, Interruption, and User Control by Default**
Voice is a profoundly human interface, and human conversations are complex. They involve context, turn-taking dynamics, and subtleties that early voice apps largely ignored. The next generation of voice-first applications must bake these considerations in from the start: remember context, handle interruptions gracefully, and always give the user a sense of control.
Maintaining context is essential for multi-turn conversations. If a user asks, “Where is Alice today?” and then follows up with “What about Bob?”, a good voice assistant should understand that “what about Bob” likely refers to the same context (perhaps asking about Bob’s location) rather than treating it as an unrelated query. This was a weak point in many voice systems; they were essentially one-shot command executors. Today, with large language models and better state tracking, we can do much better. Even so, it requires intentional design: deciding what conversational history to keep, how to let the user correct the system or clarify (“No, I meant the *other* Alice”), etc. As mentioned earlier, advanced voice AI like GPT-4’s voice mode have demonstrated more fluid context handling; they keep a memory of the dialogue so far and can seamlessly incorporate a user’s mid-thought clarification. Developers should leverage techniques like storing session state or using conversation IDs to thread context through successive calls to the AI. More sophisticated approaches include retrieval-augmented generation where the system can pull in relevant info based on context (e.g., if earlier you mentioned “the 2019 report”, a subsequent question about “it” could fetch that report’s content). The goal is to make interactions feel like a coherent dialog, not a series of isolated Q\&As.
Interruptions deserve special focus because they are so common in human-to-human conversation. We interrupt to clarify, to change topic, or to interject an urgent thought. Voice interfaces historically handled this poorly. If you tried to talk while Alexa was talking, she would typically ignore or say “Sorry, I didn’t catch that.” This is changing. As noted, new systems are allowing interruption during TTS playback , and research is exploring how to have AI agents that can themselves interrupt (e.g., to ask a clarifying question proactively). Designing for interruption means your voice app should *always be listening*, at least in a lightweight sense, even when it’s talking. Technically, this can be via a continual VAD and a mechanism to cancel or pause output. Interaction-wise, it means being prepared for the conversation to go off-script. For instance, if the user interrupts with “actually, wait, that’s wrong,” the system should be ready to pause and address that (maybe by correcting itself or asking for clarification) rather than stubbornly continuing a long response. A conversation design principle here is to make interactions flexible: don’t lock users into long monologues or rigid menus. Encourage brevity and allow changes of direction. Users will feel the system is more intelligent and considerate if it can adapt mid-stream. As one design guide puts it, a voice interface should feel like a cooperative conversation partner, not a lecture.
Finally, user control and transparency must be front and center. With voice, users can feel especially vulnerable. After all, they are literally being listened to. To build trust, voice applications should *always let the user control the experience*. This includes basic things like: easy mute or stop commands (“Cancel” should immediately halt any action or audio, no questions asked) and clear indications of when the system is listening or recording. It also extends to data practices: for example, giving users the ability to delete their recordings or transcripts, or turn off cloud retention of their voice data. Both Amazon and Google faced backlash in past years until they provided options for users to wipe their voice history and tightened data handling policies. In some jurisdictions, laws require explicit consent to record audio, so apps need to obtain that (and it’s just good practice ethically). There’s also an expectation that always-on systems be transparent about what’s happening. This could be as simple as a LED on a smart speaker that lights up when audio is streaming out, or a subtle beep when a car’s voice assistant starts sending data to the cloud. Even in purely on-device scenarios, letting the user know “I’m listening for the wake word locally, nothing is sent until you say it” via onboarding materials can help alleviate concern.
At a design level, think of user control also in conversation flow. A voice assistant should allow the user to redirect or opt-out easily. If it’s reading a long chunk of info, the user might say “stop” or “enough” and that should be gracefully handled. If the user wants to undo an action done by voice (“actually, cancel that order I just placed”), supporting that builds confidence that using voice won’t run amok. In essence, we need to empower users in voice interactions just as we do in GUIs (where they have cancel buttons, undo, visual feedback, etc.). Without visuals, this is harder, but auditory or spoken confirmations and straightforward off-ramps are key. Always consider the fail-safe: what happens if the AI mishears something critical? A well-designed system might ask for confirmation for high-stakes actions (“Did you really want to delete all your files? Please say yes to confirm.”). These checks, while adding a bit of friction, are part of responsible voice UX because they give the user ultimate control.
In summary, voice apps must be designed with human conversation norms in mind. They should carry context, allow natural interruption, and make the user feel in charge at all times. Achieving this is as much a product design challenge as a technical one. It means possibly re-thinking conversational flows, user onboarding (teaching users how to interact by voice), and error recovery strategies. Those who nail these aspects will deliver voice experiences that feel not just novel, but genuinely delightful and trustworthy. As one recent commentary on ChatGPT’s voice mode noted, the reason it wowed users is that it felt “more human, more complex”. It could handle a messy conversation where you interject, backtrack, and it adapts. That’s the bar now.
## **Ethics and Responsible Voice Interfaces**
No discussion of audio-first applications would be complete without addressing the ethical and privacy dimensions. Voice interfaces inhabit an especially sensitive space: they deal with personal, sometimes intimate data (your voice and what you choose to say), they often function in private homes or workplaces, and by design they must “listen” in order to work. Earning and keeping user trust is absolutely critical if voice is to fulfill its promise as a dominant interface.
**Consent:** First and foremost, users should have control over when and how their voice is used. This starts with obtaining clear consent to record and process voice data. Many platforms and jurisdictions mandate this. For instance, Apple’s guidelines require apps to request permission before accessing the microphone, and to explain why (e.g. “This app needs to listen to your voice commands to function”). It’s not just a legal checkbox; it sets the tone for the user relationship. A voice app should make it obvious when it’s listening and allow opt-in for any continuous listening mode. The “wake word” model (where the device locally monitors for a trigger like “Hey Siri” before activating cloud streaming) has become a standard partly to balance utility and consent. Nothing except a short audio buffer leaves the device until that magic word is detected. Some advanced voice AI scenarios talk about always-on assistants that proactively interject (think JARVIS from Iron Man). If those become reality, they will need even more careful user consent frameworks; perhaps a configurable setting like “Help me out when you think I need an alert” that the user can toggle. The guiding principle is user agency: the user should explicitly agree to being listened to, and be able to pause or stop it at any time. It’s encouraging that even companies like Spotify, which added voice features, emphasized that using them is contingent on user consent and that users can decline if they’re uncomfortable.
**Data Retention and Privacy**: When voice data is captured, how long is it kept? Who can access it? These questions have gotten companies into hot water. There have been headlines about snippets of Alexa recordings being reviewed by employees, or voice data being stored indefinitely unless users proactively delete it. Best practice today (and likely a future regulatory requirement) is to be minimally invasive: keep voice recordings only as long as needed to accomplish the task or improve the service, and anonymize or delete them as soon as possible. Some services now default to deleting audio recordings after a short period (e.g., Amazon allows users to auto-delete after 3 months). From an ethics standpoint, if voice is truly the interface of the future, we must avoid it becoming a surveillance nightmare. Companies should be transparent in their privacy policies about what they collect (audio recordings, transcripts, derived data like emotion tone), and give users the option to purge their data. Edge processing can help here. If more voice recognition can happen on-device, then no raw audio ever needs to hit a server, reducing privacy risk. As mentioned, on-device voice AI is becoming more viable and should be used for sensitive contexts whenever feasible.
**Another aspect is security**: voice data can be personal (your voice is a biometric identifier). Systems should encrypt voice data in transit and at rest , and guard against abuse. For example, voice assistants should have some protection against unauthorized commands; imagine someone yelling through your window “Hey VoiceSpeaker, unlock the door!” Ideally, the system has voice recognition to only obey the owner’s voice or requires a confirmation PIN for security-critical actions. Biometric voice ID is double-edged: it can add security (only I can authorize a bank transfer with my voice) but also raises privacy issues (my voiceprint is being stored somewhere). Designers need to consider threat models, like malicious use of AI-generated voices to spoof identity, and build safeguards (maybe a user-chosen challenge-response for sensitive transactions, rather than relying solely on voice matching).
**Transparency in AI behavior**: Users should know when they are talking to a machine versus a human. This is an ethical point about deception. With AI voices becoming so natural, there’s a risk that users might be fooled (imagine a voice agent calling a customer and the customer not realizing it’s AI). In some jurisdictions, there are already or will be rules that automated calls must disclose they’re not human. Even in interactive voice responses, if an AI is generating answers, a simple notice like “I’m an AI assistant, here to help” can set correct expectations. Transparency also means explaining to users, at least in broad strokes, how their voice inputs are used. For example, an app might on first launch say: “We value your privacy. Your voice commands will be used to control the app and to improve our speech recognition over time. We won’t use them for anything else without your permission.” Such messaging can be accompanied by a link to a full privacy policy for those interested. According to surveys, users are more willing to engage with voice tech if they feel informed and in control of their data.
Ethical use of voice data also touches on bias and fairness. Voice AI systems have historically struggled with recognizing certain accents or dialects (often those of marginalized groups). If a voice interface doesn’t work as well for some users, that’s both a UX failure and an ethical issue. Developers should strive to use diverse training data and test their systems with diverse voices. And in customer-facing scenarios, ensure there’s an easy fallback to a human or another interface if the voice system isn’t understanding someone well. It can be incredibly exclusionary to have a voice-only interface that doesn’t accommodate a user’s speech pattern; imagine a customer service line that hangs up because it can’t parse a particular accent. In the push for voice-first apps, we must remember to provide alternatives and accessibility (ironically, voice itself is an accessibility feature for many, but not universally). Some users with speech impairments, for instance, might prefer a different modality. A truly thoughtful design might allow seamless switching (e.g., if the voice bot isn’t working out, route to a text chat or a human agent.)
To wrap up, the ethical mandate for voice applications is: Respect the user’s voice as you would their personal space. That means ask before entering, listen carefully, don’t overstay your welcome (don’t hoard data), and leave if you’re asked to. Do these things, and users will be far more likely to trust and adopt voice interfaces. As the old saying in security goes, trust is hard to earn and easy to lose. One privacy blunder or feeling of “I’m being spied on” can turn someone away from voice tech for a long time. Conversely, clear respect for consent and privacy can be a selling point. Given that nearly all major tech companies have faced scrutiny on this, new players have an opportunity to differentiate with *privacy-first voice experiences*. In an era of growing AI skepticism, building ethical guardrails into your voice application is not just morally right, it’s strategically wise.
## **Takeaways and Recommendations: Building in the Voice-First Era**
We’ve covered a lot of ground, so let’s distill the key takeaways and some forward-looking recommendations for product leaders, developers, and investors interested in voice-first applications:
* **Voice is Reaching a Tipping Point:** It’s no longer a fringe interface. With billions of voice-enabled devices in use and a substantial portion of users comfortable with voice commands , the user base is there. The AI capability is catching up to user expectations, and infrastructure is emerging to support it. This is a foundational platform shift akin to the rise of touchscreens or mobile apps: those who recognize its significance stand to benefit. Don’t view voice as a novelty; view it as a paradigm shift in how people interact with technology. Companies that reimagine user journeys with voice at the center (where it makes sense) could leapfrog competitors in convenience and user engagement.
* **Focus on High-Value Use Cases Today:** What’s viable right now? Based on current tech maturity, several use cases are already delivering value: automated meeting summarization (saves time, widely adopted) , voice assistants for simple tasks (timers, smart home control) which are now baseline expectations, voice search in apps, real-time transcription for notes or captions, and domain-specific voice bots (e.g. triaging customer support calls with a first-line AI agent). These are areas where off-the-shelf models and tools can be combined to build a product with reasonable effort. For instance, using an API like AssemblyAI or Deepgram for transcription and GPT-4 for summarization, one can build a meeting notes assistant fairly straightforwardly. In hardware, earbuds with voice assistants or cars with voice control are also well within today’s capabilities. In contrast, what’s still hard (though being worked on) is open-ended conversational AI that can handle anything a user says as well as a human would, or truly emotion-aware, contextually savvy AI friends (the sci-fi Jarvis or Her). Also challenging is achieving human-level dialog in edge cases like highly noisy environments or for speakers with very unique speech patterns; progress is made, but not 100%. Multi-party conversation understanding (where multiple people are talking) is another frontier; current systems prefer one speaker at a time. So, build for use cases that play to the strengths of today’s AI: structured conversations, well-defined tasks, and scenarios where slight errors are tolerable or can be mitigated with human fallback.
* **Invest in the Ecosystem**, **Not Just Models**: If you’re an investor or technology decision-maker, recognize that the winners in voice might not only be those with the “best ASR model” but those with the best ecosystem and developer experience. This means platforms that make it easy to create, deploy, and monitor voice applications. We see startups focusing on exactly this: providing tooling for conversation design, debugging voice interactions, and integrating voice into existing software workflows. Also, areas like voice security (speaker authentication, deepfake detection) and voice-specific hardware (low-power chips for always-listening devices) are ripe for investment. Think of the layers: foundational models (lots of competition there, including open source), enabling infrastructure (still plenty of room, analogous to how Twilio enabled telephony apps or Stripe enabled payments. Who will enable voice apps easily?), and vertical applications (voice AI tailored for healthcare, sales, education, etc.). Bessemer’s market map of Voice AI shows innovation at all these layers. A savvy strategy might be to combine strengths; for example, a vertical app built on top of a strong platform partner, focusing on a niche but leveraging general improvements beneath.
* **Embrace a User-Centric Design Mindset**: As you build voice experiences, constantly step into the user’s shoes (or rather, their ears and mouth!). Voice interactions are intimate; when done right, they can delight users by making technology feel more natural, almost invisible. But if done wrong, they can feel frustrating or even invasive. Follow best practices of conversation design: keep responses brief and relevant , guide the user without patronizing, handle errors gracefully (“I’m sorry, I didn’t catch that” is okay once, but if it repeats, find a different strategy), and inject persona and warmth where appropriate so it doesn’t feel robotic. Also, test with real users extensively. People will say the darndest things; be prepared for variability. Did your music voice app consider that someone might ask “play that song from Titanic”? Does your appliance voice control handle a user swearing at it in frustration? Testing and iterating will uncover these. Remember that voice UI design is a new discipline; it’s not the same as GUI or web design. Hire or consult with conversation designers and linguists if possible; understanding human dialogue patterns is a skill.
* Address Ethical Concerns Proactively: Weave privacy and security into your product from day zero. Make privacy a selling point; for instance, “Our voice device processes everything on-device; your data never leaves your home” is a powerful pitch as compared to the status quo. Ensure compliance with laws like GDPR (which might classify voice data as biometric personal data requiring special handling). Establish clear data governance: who can access user voice logs internally, how long are they kept, can users opt out of data collection to improve models, etc. Being proactive here will save you headaches and build trust. With voice, word of mouth (no pun intended) is important: if early users trust your approach, they’ll become evangelists, but if someone feels creeped out and shares that, others will hesitate. We are at a stage where many users still remember the first time they felt a voice assistant misused their data or triggered without permission. We want the next wave of voice products to reset that narrative by being respectful and transparent.
* **Keep an Eye on Emerging Tech**: The pace of advancement in AI for voice is rapid. New models (like those combining voice, visual, and textual understanding) could open possibilities such as voice assistants that see (using a camera) and talk, which could revolutionize AR (augmented reality) experiences, e.g., smart glasses that you converse with about what you’re looking at. Additionally, improvements in speech synthesis mean future voice apps can have much more customizable personalities; imagine brands having signature AI voices. Another area to watch is emotion and sentiment analysis from voice: AI that gauges how you’re feeling from your tone. This could be used positively (responding with empathy if a user sounds upset ) or negatively (overstepping privacy, so careful!). The key recommendation is stay adaptive. Build your voice architecture in a modular way so you can plug in new models or components as they become available. What’s cutting-edge today might be outdated next year.
* **Quality Over Hype**: Finally, a word of caution: avoid hype and “voice washing” (adding voice just to sound AI-enabled). Users can tell when a voice feature is half-baked or gimmicky. It’s better to have a few voice interactions that work consistently well and solve a real pain point, than to have 50 voice commands that often misfire. Quality in voice apps is hard-won but essential. As BVP noted, it’s easy to demo a flashy voice capability, but customers will churn if it doesn’t work reliably in practice. Achieving high reliability might mean narrowing the scope (e.g., a voice assistant that only does one domain really well), and that’s okay. Reputation matters; many still remember the frustration of early voice assistants and you may not get a second chance with some users if your app disappoints the first time. So focus on robustness, testing, and continual improvement. Instrument your application to measure things like recognition accuracy, how often users have to repeat themselves, latency stats, etc., and use those metrics to drive updates.
We stand at the dawn of the audio-first application era. The phrase “voice is the interface” isn’t just rhetoric, it speaks to a fundamental shift in computing. Just as GUIs and touchscreens made computing more accessible to billions, voice interfaces promise to do the same for billions more, and to open up new modes of interaction we can only partially envision today. This shift is being enabled by AI, but its success will depend on holistic thinking: technology, design, infrastructure, and ethics all working in concert. For those building in this space, it’s a thrilling time! Advances that seemed a decade away are happening now. But it’s also a time for thoughtful strategy, because getting it right will shape how humans and machines converse for years to come. In the end, the goal is simple: make technology speak our language, literally, so interacting with digital systems becomes as natural as talking to a friend. The companies and creators who achieve that will define the next chapter of the interface revolution.
---
# Watch Party Challenges: Technical, Walled Gardens, and More
> Discover the key challenges of watch party synchronization, from latency issues in virtual viewing to real-time streaming alignment. Learn how AI and machine learning can enhance synchronization accuracy and improve the shared viewing experience. Start developing seamless watch party solutions today.
### **Content Walled Gardens: Subscription Access**
One of the biggest hurdles in hosting seamless watch parties is the **content level “walled garden”**—the barriers that keep users within individual streaming ecosystems. For instance, if one person has a subscription to Disney+ but another only has Netflix, enjoying the same movie or series together isn’t possible without access to the same streaming service. This content fragmentation complicates the idea of a shared viewing experience, relegating most watch parties to content that all participants have access to.
Some solutions to this issue are emerging. **Streaming providers are testing friend passes** and other options to enable guests to temporarily access content without a direct subscription. Additionally, the availability of freely accessible content on platforms like **YouTube and TikTok** could help overcome this barrier, allowing users to host watch parties without needing multiple subscriptions. Generated videos are another promising avenue here. Even if they don’t necessarily get you access to all the shows you’d want to watch with someone else, it’s a content format that will lead to more experimental product development, which will in turn catalyze further development around mainstream content.
**Hardware Walled Gardens: Platform Incompatibilities**
Another layer of walled gardens exists at the **hardware level**. Different TVs, operating systems, and streaming devices make it challenging to provide a consistent technical solution for watch parties. While web-based watch parties are easily accessible from laptops, smartphones, or tablets, the experience is significantly limited on these smaller screens, missing the immersive quality of a large TV screen.
However, with technologies like **Kosmi**—a web-based platform that supports casting to smart TVs—these challenges are starting to be mitigated. As streaming devices and TVs continue to standardize around **Apple, Android, and HTML5 among other web technologies** we will see more accessible solutions for large-screen viewing.
**Technical Improvements: AI and Beyond**
The technical aspects of real-time synchronization, latency management, and audio-visual quality have also been challenging for watch party solutions. These issues are magnified when participants are spread across different geographic locations, each with their own internet speed and latency. Fortunately, **advances in AI and machine learning** are helping to create smoother and more synchronized experiences. Machine learning algorithms can dynamically adjust playback and buffering to optimize synchronization, which is crucial for ensuring everyone is watching the same moment at the same time. Moreover, audio technologies have improved to the point where keeping an open microphone while watching and listening to content is now feasible. Even in the case of solutions with a single microphone, the ability to separate a target user’s voice from background noise or the content itself has advanced to a point that technology is no longer a blocker – it’s just an engineering challenge.
As walled gardens at the operating system level continue to consolidate, with fewer and more universally compatible systems like **Apple TV, Android TV, and cross-platform web apps**, developers can deliver more cohesive experiences without building individual solutions for each device type.
**Lessons from Lockdowns and Early Watch Party Experiments**
The lockdowns during the COVID-19 pandemic accelerated interest in shared viewing experiences, leading to a period of rapid experimentation. Large platforms like **Disney, Amazon, and Hulu** explored ways to let users share viewing experiences within their ecosystems. Similarly, startups like **Kosmi** brought innovative solutions, tackling the challenges of synchronization, user experience, and content access in different ways.
These experiments provided valuable insights, laying the foundation for future watch party innovations. The trend toward **consolidation in streaming platforms** and **improved web-based solutions** hints at a promising future where users can more easily overcome content and hardware barriers.
**A Glimpse into the Future: Consolidation and Open Collaboration**
As technology advances, and as barriers fall, watch parties will become ever more immersive and accessible. The dream of shared media experiences across diverse devices and content providers may soon be a reality, with improvements in **open content** and **multi-device compatibility** making it easier for everyone to join in on the fun.
[Get In touch](/contact)
---
# What We Learned Building an On-Device Voice Agent
> While the AI conversation focuses on models and cloud compute, a parallel shift is underway: AI inference is moving onto the devices we already own, reducing the need to send every task to the cloud.
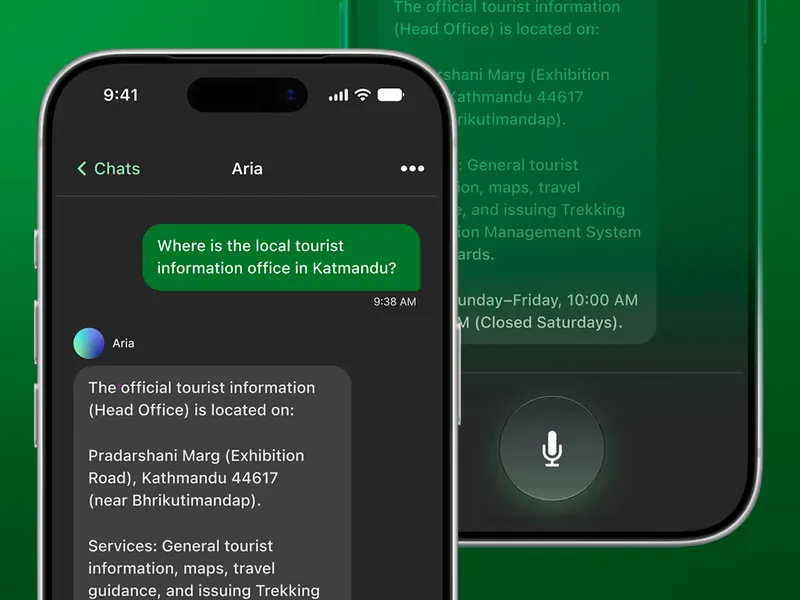
The question we wanted to answer was how much of a genuinely useful travel agent still works completely off-grid, and how cleanly it can reach for a more capable model when one is in range. This post is about what went wrong and what we learned.
The code is open source: [hybrid-voice-agent-sample](https://github.com/switchboard-sdk/hybrid-voice-agent-sample).
## What we built
You talk to the app, and it answers out loud. It's a React Native app built on the Switchboard SDK, and three things run on the phone: speech to text (Whisper), a small language model (Llama 3.2 1B), and text to speech (Sherpa). The small model is enough to hold a conversation but not enough to answer a hard question well, so you can also switch the brain, the part that thinks, as opposed to the parts that hear and speak, to a cloud model, even in the middle of a conversation.
Speech to text and text to speech always stay on the phone, so only the thinking moves. Both brains read and write the same transcript, which is why you can switch while you talk and the conversation continues instead of starting again. On an iPhone 13, a reply from the model on the phone comes back in about 2.6 seconds.

One thing is worth saying first, and it is the boring lesson: almost every real bug in this post came from using the app on a real iPhone, and very few came from the test suite. The tests were useful, but they never found the interesting problems.
## Lesson 1: a small model will not follow your rules
This was the longest fight of the project, and it took four attempts.
The on-device prompt had a rule: refuse anything that is not travel help. Then we got this feedback from a reviewer:
***
###### "It kept saying 'I can only help with travel' no matter what I said to it."
***
**First attempt.** We made the rule narrower, so it would catch fewer things, but this did not help at all.
**Second attempt.** We looked at why, and found that the rule asked the model to answer with one fixed sentence, word for word. Every time it did this, that sentence went into the model's own context, and for a 1B model the most likely next answer is the sentence it just wrote twice. So after two refusals, "Where should I go in Norway?" also came back as "I can only help with travel", and the conversation never recovered.
Other questions in the same session were still answered correctly, so the rules were not broken — the repetition was simply stronger than them.
We fixed this in two ways: the refusal is now said in four different ways, so the user never hears the same sentence twice, and a refused exchange is removed from the history we replay, so the model never reads its own refusal again.
**Third attempt, and the real lesson.** We looked at the rule again and found it was wrong in both directions:
```
"Where is the local tourist information office in Katmandu?"
-> I can only help with travel, and I'm not in a position to provide
information on specific locations.
"Which is cheapest?" (comparing Norway and Sweden)
-> I can only help with travel.
"Write me a poem."
-> twenty lines of verse
```
The first refusal came one turn after the model had recommended a tourist information office, while the one request the rule existed for went through without any problem, twice in one day.
So we deleted the rule and moved the decision into code, where it looks at the answer instead of the question. If the reply is a poem, we refuse, and a poem is easy to detect, because it has several lines with one sentence continuing past the end of the first. Normal text and lists never look like that.
**The lesson:** a rule has to guess what a request is before it sees the answer, while code can look at what actually came back. On a 1B model a request from the user is stronger than a rule in the system prompt, so you cannot win this fight in the prompt — move the decision to where you have more information.
## Lesson 2: we looked for the bug in the wrong place
The replies often did not match the question, and then we found why: the first word of every sentence was disappearing.
```
"How much is a taxi to the harbour?" -> "much is attached to the harbor"
"Write me a poem." -> "me a poem."
```
The obvious answer was that the audio buffer was too small, or that we needed a pre-roll, but that answer was wrong, because the audio was always there.
The real reason was this. The voice detector ended the utterance after the first word, because there was a very short pause after it. That short segment then started its own transcription call, and the call found nothing useful, so it returned an empty string, but it still consumed the audio. So the word was not lost in the buffer; it was eaten by a call that should never have happened.
No buffer setting could fix this, so instead we changed who is allowed to start a transcription. We removed one connection in the SDK's audio graph, so the voice detector no longer kicks off a transcription of its own, and moved that call up into the app's TypeScript layer. Now we wait 350 ms before transcribing, and if the person starts speaking again we cancel the call, so nothing is transcribed until the sentence is really finished.
**The lesson:** when audio goes missing, also ask who is allowed to make the call, not only how big the buffer is.
## Lesson 3: we made people wait for words nobody would hear
The prompt says: answer in one or two short sentences. When the question was broad, the model ignored this and wrote a list instead:
```
[LLM] reply in 9314ms: Norway is a vast and diverse country... Here are some key things to know:
* Weather: ...
* Language: ...
* Culture: ...
* Accommodation: Norway has a wide range <- cut off at 200 tokens
```
Our code already trims the reply down to its first sentence before handing it to the speaker, because the speaker reads out every line it is given. So the user waited 9.3 seconds and then heard one sentence that was ready after about one second, while everything else was generated and thrown away.
The fix was one number: we lowered the token limit from 200 to 80. The output did not change at all — the model simply stops writing text that nobody would hear.
After the change, measured on an iPhone 13 over 25 turns, the median was 2.6 seconds. The same question that took 9.3 seconds came back in 3.5 seconds at turn 2 and 3.8 seconds at turn 22, so there was no slowdown as the conversation got longer.
**The lesson:** a token limit is not only a cost setting, it is also a waiting time.
## Lesson 4: one prompt cannot serve two models
The cloud brain kept telling people it was offline. This looked like a hallucination, but it was not: both brains got exactly the same prompt, and rule 2 started with "You are offline and cannot look anything up." We had told it to say that.
We split the prompt into two, and then a second problem appeared, because the cloud brain had also inherited the careful tone we wrote for the small model. Someone asked for a daily budget for Iceland, and it answered "research accommodation, food and activity costs online for the most accurate figures." It knows that answer; it just did not want to say it.
**The lesson:** being careful is correct for a small model, because it does not know much, but the same words on a big model only make the answer less useful. Write the prompt for the model you are actually using.
## Lesson 5: how to write rules for a small model
We had three rules about not inventing facts. Two of them said what to refuse **and** what to say instead, in one sentence, while the third only said "do not do this" — and that was the rule the model ignored, which we saw break twice on a real phone.
The general idea is that a small model acts on instructions and ignores descriptions, so a rule that only describes the situation ("you have no internet") does nothing, while a rule that says what to do ("say you cannot check it, and say who can") works much better.
One warning, because this part surprised us: we added an example answer to the rule, and when we tested it, the model replied with the example word for word, as the answer to the example's own question. That only proves the example can be reached, not that the rule works in general, so test with a different question than the one in your example.
## Lesson 6: the offline bug was not in our code
Working without a connection is the entire point of this app, so this was the bug that mattered most: in airplane mode, the cloud brain stayed available and the app never told the user the connection was gone. Our router and our UI were both correct, and the connectivity value simply never became false.
The reason was in the library. `expo-network` keeps one network monitor, which it starts when the first listener attaches and cancels when the last listener leaves. On iOS a cancelled monitor cannot be started again, and the call to start it fails quietly, so any subscription owned by a React component stops working the first time that component remounts — and in development that happens immediately.
```
[net] subscribing
[net] change: {"type":"WIFI","isConnected":true} -> on
[net] unsubscribing
[net] subscribing
[net] poll: ... <- and never a change line again
```
We moved the subscription out of React, so it now lives in the module, opens once and never closes, and React reads it with `useSyncExternalStore`.
There was a second, funnier problem in the same task: **you cannot read the log with Wi-Fi off.** The phone sends its console output to the development server over Wi-Fi, so when you turn Wi-Fi off to test offline behaviour, you also cut the log. The line `[net] offline` is written on the phone and never arrives, which cost us an extra round of testing. In the end we just watched the screen.
## Lesson 7: the app was four times bigger than it needed to be
Left alone, the release build would have been about 1.63 GB, and the models were almost all of it.
CocoaPods copies the whole framework into the app, even the parts you never use. The speech framework ships a complete second speech-to-text system, which we do not use because we transcribe with Whisper, and that was 361 MB for one decoder graph plus 27 MB for a model. There was also a German voice we never select, at 83 MB.
Two changes fixed it. We moved the 773 MB language model out of the app and download it at first launch instead, which brought the build down to 856 MB. Then we started deleting the unused speech files right after we download and extract the frameworks, which took it to 384 MB.
**The lesson:** check what your dependencies actually put in the app bundle, because it is often not what you assume.
## Lesson 8: we deleted a feature that worked
We built a small router that sent questions like "how much" and "how far" to the cloud, even when the user had chosen the on-device brain. It worked well, and the answers got better.
We removed it before we pushed it, because this app exists to show that a whole conversation can run on the phone, with the cloud as a choice the user makes rather than something that happens behind their back. An app that quietly sends the interesting questions to a server damages that message more than a wrong walking time does.
**The lesson:** "it works" is not the same as "it belongs in this product."
## Lesson 9: write down what does not work
The small model invents facts, and it sounds confident when it does. It has put a Norwegian city in the wrong island group and it gives flight times to the minute, and once it started a reply with "You're in the airport, and you're due to fly to Kathmandu", when the user had only said hello.
We tried rewriting the rules and we tried temperature 0, but neither was enough. A code check could catch invented numbers, but not invented places — if we refuse every place the user did not name first, the app cannot answer the questions people really ask.
Speech recognition has a similar limit. The base English Whisper model is weak with names, and names are exactly what a travel app hears most, so "Budapest" comes back as "Buddha Pasht" often enough to plan for. Nothing after that step questions a wrong name, so one mistake becomes the base for the rest of the conversation.
We wrote all of this into the README, because the replies sound fluent and confident, and that is exactly why people need the warning.
One more note about writing it down. Our first version of that section was really a report about one afternoon with one phone: it named the device, quoted that session, and said what we had already tried. We rewrote it later as behaviour — what the model does, and how often to expect it. We also removed a number, "about one utterance in six is wrong", because it was a real measurement, but from one speaker, in one room, with one accent, and that is not enough to give a general rate.
## What we would do differently
\- **Use the phone earlier.** Several changes were merged with the note "not verified on device yet", and most of them needed a follow-up, while the test suite never found any of the problems above.
\- **Judge the end of a turn, do not just time it.** Today we wait 500 ms of silence and then another 350 ms, which is 850 ms of waiting, and it is also how long it takes to interrupt the agent. The better solution is a model that decides whether the sentence sounds finished, and the Switchboard SDK already has one, so this is wiring rather than new work.
\- **Size the history by what the model can use, not by what fits.** We first replayed 40 messages, because that is what fits in a 4096-token context, but with 11 exchanges of history the model answered a question from six turns earlier. Ten messages works much better, so the context window was not the real limit.
\- **Give the small model something to look things up in.** Almost every quality problem comes from a 1B model with no retrieval, and the prompt cannot fix that.
The pull requests are public and each one explains the reasoning: [hybrid-voice-agent-sample/pulls](https://github.com/switchboard-sdk/hybrid-voice-agent-sample/pulls). The most interesting ones are:
[#19](https://github.com/switchboard-sdk/hybrid-voice-agent-sample/pull/19) — the missing first word),
[#20](https://github.com/switchboard-sdk/hybrid-voice-agent-sample/pull/20) — the repeating refusal),
[#22](https://github.com/switchboard-sdk/hybrid-voice-agent-sample/pull/22) — the 9-second wait
[#23](https://github.com/switchboard-sdk/hybrid-voice-agent-sample/pull/23) — deciding from the answer instead of the question.
---
# Examples of What You Can Build With Switchboard
> Switchboard gives developers modular building blocks (think: LEGO for audio) to create innovative real-time experiences that can combine music, voice, AI, effects, and more—without reinventing the wheel.

We believe real time voice is the next interface—and we’re making it radically easier to build solutions with it. [Switchboard](https://switchboard.audio/) gives developers **modular building blocks** (think: LEGO for audio) to create new real-time experiences that combine things like music, livestreams, voice chat, AI voice agents, translation, or audio effects from reverb or noise cancellation to auto-tune and voice changers.
Instead of writing custom code to connect everything, you can snap together pre-built components for things like media playback, speech to text, text to speech, audio I/O, mixing and routing audio channels, webRTC, DSP effects, and more—allowing you to focus on designing innovative real time user experiences that can be made from these components rather than spending months in the weeds.
Whether you're working on a product in entertainment, voice AI, gaming, health, education, or any other industry, here are some examples of the types of things you can build with Switchboard.
## Real-World Use Cases Built with Switchboard
#### Voice AI Agent
An AI voice assistant that can talk to you naturally, transcribe your words, and respond instantly—like a smart co-worker or virtual host inside your app.
#### Real-Time Language Translation
A two-way voice translator that listens, interprets, and speaks the translation out loud with minimal latency—whether for fun or customer service.
#### Watch Parties with Voice Chat
Let friends talk while watching videos or livestreams together, with perfectly synced playback auto-leveling volumes driven by voice detection.
#### Voice-Changing Avatars in Games
Give every character a unique voice in real time—turn your voice into a robot, alien, or action hero using audio effects and DSP.
#### Smart Music Player with Voice Control
A music player you can control by speaking. Create playlists from natural language or add hands-free controls.
#### Customer Support Voice Bot
Build a real-time voice bot that understands callers, responds using TTS, and routes conversations to the right place, and on any platform -- via the internet or a phone number.
#### Language Learning Buddy
A speaking partner that listens, helps you pronounce things correctly, and converses back in your target language.
#### Silent Disco / Group Music Sync
Sync music across devices so a group of users can listen together with zero lag—perfect for classes, events, or remote groups.
#### Podcast Co-Listening and Live Reactions
Let couples listen to podcasts while walking the dog while still able to talk through their headphones. Or connect a live audience—like Spotify meets Clubhouse.
#### On-Device Voice Agent with Wake Word
A privacy-first voice assistant that runs on-device, with wake-word detection and no cloud dependency.
#### Smarter In-Car Voice Assistants
An automotive voice agent that can not only talk to you, but that interfaces seamlessly with music, media, and communications.
#### AI-Controlled Livestream Host
A synthetic co-host for your livestreams that can answer questions, highlight comments, or cue music on command.
#### Team Voice Chat with Embedded Music
A persistent audio channel for remote teams with embedded music synchronized for all of you.
#### Voice-Controlled Game Streaming Overlay
A Twitch extension that responds to your voice—triggering overlays, soundboards, or in-game actions on stream.
#### Virtual Health Assistant for the Elderly
A friendly voice interface that can remind people to take medicine, answer health questions, and connect them to caregivers.
#### Audio Diary with Sentiment Detection
A personal audio journal that transcribes your thoughts and analyzes tone or emotional state over time.
## Why This Matters
Building such use cases is normally time consuming and fraught with issues that compound as technical debt and poor user experience. Switchboard removes the friction from building real-time audio experiences. It contains things like:
 Pre-built audio modules (STT, TTS, effects, sync, etc.)
 A flexible SDK for mobile, desktop, web, and embedded platforms
️ Tools that help you innovate 10x faster
If you can imagine it, you can build it—block by block.
## Ready to Start Building?
[Explore the Switchboard SDK](https://switchboard.audio)
Or, if you want help architecting your next voice-first experience.
[Get In touch](/contact)
---
# When Do You Actually Need C++?
> Every business wants customer service to feel like a personal concierge. Few are set up to actually deliver one.
Most software development doesn’t need to touch C++.
A majority of products can be written in Swift, Kotlin, JavaScript, or any number of modern languages that are easier to work with. Entire categories of apps—social networks, marketplaces, streaming platforms—run perfectly well without ever touching low-level code.
Most apps are built around discrete actions—tap a button, get a response. But real-time media and voice apps don’t work that way. Audio is constantly flowing, multiple streams are active at once, and the system has to react instantly—mixing, prioritizing, and transforming signals as they come in.
That’s where things start to break if the underlying system can’t keep up. And that’s typically when C++ becomes part of the solution.
## Where the Performance Difference Actually Comes From
At a high level, C++ gives you more direct control over how your program runs. Code compiles down very close to machine instructions, memory is managed explicitly, and there’s no background system stepping in unpredictably to clean things up or move data around.
Languages like Swift and Kotlin are also compiled, and very fast in general. But they’re designed with different priorities: safety, developer productivity, and managing memory automatically. This is usually incredibly useful but it also means that you don’t have precise control over exactly when things happen.
For most applications, that distinction doesn’t matter. But in systems where work has to happen on a strict schedule—every few milliseconds, without interruption—it starts to matter a lot.
Audio is one of the clearest examples.
## Why Spotify Doesn’t Need C++
Take a typical streaming app like **Spotify **or **Netflix**.
From the outside, these feel like real-time systems. You press play, and audio or video starts instantly. But under the hood, they’re mostly orchestrating playback of pre-encoded media using highly optimized system frameworks like **AVFoundation **on iOS or **ExoPlayer **on Android.
Those frameworks already solve the hard problems. They’re written in low-level code, tuned for each device, and designed to handle buffering, decoding, and synchronization. The app itself is mostly issuing high-level commands: play, pause, seek.
As long as you’re just *playing *audio or video, Swift and Kotlin are more than sufficient. You’re not responsible for the real-time engine—you’re just running it on autopilot.
## When You Stop Playing Audio and Start Shaping It
The situation changes the moment you start manipulating audio in real time.
Imagine a simple guitar app. You plug in, play a note, and expect to hear it instantly with effects applied—distortion, reverb, delay. If there’s even a small hiccup, you hear it immediately as a click, a pop, or a lag between action and sound. The system isn’t just responding to input anymore; it’s continuously transforming a live signal under tight timing constraints.
That same pattern shows up in professional audio tools, where thousands of samples are processed in rapid succession, and timing errors are not just noticeable—they’re unacceptable. At that point, you need guarantees about when code runs, how memory is handled, and how data flows through the system.
That’s where C++ tends to become the foundation. And in music production and other pro audio use cases, it has been the foundation for years.
But we are now seeing new classes of real time audio applications come to market and expect that trend to continue as real time audio technologies make new use cases feasible.
## Interactive Voice Chat Gets Complicated Quickly
Consider something that looks simple on the surface: a group voice chat.
But instead of just talking, participants start watching a video together—a shared media stream, synced across devices. While the video plays, people speak intermittently. When someone starts talking, the system detects speech using voice activity detection (VAD), lowers the volume of the video (ducking) and this makes it easier to hear the person talking. When they stop talking, the video audio smoothly returns to full volume.
Behind the scenes, this means:
* Multiple audio streams (video, multiple microphones)
* Real-time analysis (VAD running continuously)
* Dynamic mixing and gain adjustment
* Tight synchronization between audio and video
All of this has to happen continuously, with minimal latency, across devices with different hardware characteristics.
This is no longer a simple “playback” problem. It’s a real-time orchestration problem. And small timing inconsistencies—whether from memory management, scheduling, or buffering—start to compound into bugs and audio glitches that you can’t diagnose or control from high level languages.
## Real-Time Voice AI Raises the Stakes
Now layer in voice AI, such as a voice agent participating in the voice or video call.
Instead of just passing audio around and mixing it, you’re processing it through a pipeline: capturing microphone input, detecting speech, transcribing it, generating a response, and synthesizing audio back to the user. And you’re doing it continuously, not as a one-off request.
Increasingly, parts of this pipeline are moving onto the device:
* Running VAD locally to avoid sending silence to the cloud
* Performing lightweight speech recognition on-device for latency or privacy
* Handling audio pre-processing (noise suppression, filtering) before anything leaves the device
This hybrid model—some local, some cloud—is becoming the default. It reduces latency, lowers cost, and improves reliability when connectivity is unstable.
But it also means the device itself is now responsible for orchestrating a real-time graph of audio processing steps. Audio is being routed, transformed, and conditionally processed in-flight. Buffers need to stay aligned. Timing needs to be predictable. There’s no room for pauses or jitter.
That’s where a C++ core becomes less of an optimization and more of a requirement. It’s what allows you to build a system that behaves consistently under real-world conditions.
## Live Streaming, AI, and Interaction
Push this one step further.
Imagine a live commerce stream—something like Whatnot or eBay Live, but a more interactive version of it. For example, envision a host presenting products live. Viewers are watching in real time. Some can jump in with voice questions. An AI co-host listens to the conversation, surfaces relevant product details, and occasionally speaks up. Background music plays softly under the stream, adjusting dynamically depending on who’s speaking.
In that environment, you’re dealing with:
* A primary audio/video stream from the host
* Audience voice input, potentially from multiple users
* An AI-generated voice stream
* Background audio that needs to be mixed and ducked appropriately
Everything is live. Everything is interactive. And everything needs to feel instantaneous.
At that point, the system starts to look less like an app and more like a real-time media engine—one that has to make continuous decisions about routing, mixing, and prioritization. And if the system tries to do all of this in the cloud, it will be laggy, expensive, and difficult to scale.
## Why This Matters More Going Forward
For a long time, most apps were built around discrete interactions. You tapped a button, something happened, and the system returned to idle.
That’s changing.
Voice interfaces, AI agents, live collaboration, and shared media experiences are pushing products toward continuous interaction. Instead of isolated requests, systems are increasingly expected to stay active, responsive, and context-aware over long periods of time.
As technology makes more things possible, user expectations grow.
As that shift happens, more applications need to develop real-time systems. And real-time systems depend on being able to precisely control how data flows and how processing happens over time.
That’s exactly the kind of flexibility that low-level audio engines—typically built in C++—are designed to provide.
## Where Switchboard Fits
Switchboard bridges a gap. It provides the control of a custom C++ audio engine without ever needing to write C++. .
Under the hood, it uses a C++ audio engine capable of handling real-time processing, multi-stream routing, and tight timing constraints. The kinds of systems you’d normally only attempt if you were willing to build and maintain a complex native engine yourself.
But instead of exposing all of that complexity directly, Switchboard lets you define how audio should flow—how streams are connected, how processing is applied, how decisions are made—using higher-level abstractions. Those definitions can come from JSON, Swift, Kotlin, JavaScript, or cross-platform frameworks like React Native and Flutter. We are also building a no-code Editor.
So you end up with vastly simplified application development while still benefiting from the determinism and performance of a C++ core.
It’s not about forcing every team to write C++. It’s about making it possible to build systems that would normally require it, without taking on the full cost of doing so.
## The Bottom Line
You don’t need C++ to build most applications.
But if your product starts to depend on continuous audio processing, tight latency, multiple interacting streams, or real-time AI, you’re no longer just building an app—you’re building a system that runs on a clock.
And at that point, the ability to control exactly what happens, exactly when it happens, becomes the difference between something that works in a demo and something that holds up in the real world.
---
# Switchboard for Voice AI
> Open source tools and examples to help voice AI developers reduce costs, improve latency, enhance privacy, and enable offline functionality.
Open source tools and examples for voice AI developers.
Speech Recognition Text to Speech LLM Integration Echo Cancellation Voice Activity Detection Noise Suppression Turn Detection Speaker Isolation Speech Recognition Text to Speech LLM Integration Echo Cancellation Voice Activity Detection Noise Suppression Turn Detection Speaker Isolation
## Built to address real-world constraints
Switchboard for Voice AI uses a hybrid on-device + cloud architecture to help you get the best of both worlds. On-device processing with hand-off to cloud only when necessary.
### Reduce costs
Process audio on-device to minimize expensive API calls and bandwidth usage.
### Improve latency
Local processing eliminates network round-trips for near-instant voice interactions.
### Enhance privacy
Keep sensitive audio data on-device and send only processed text to the cloud.
### Enable offline
Build voice AI features that work without an internet connection.
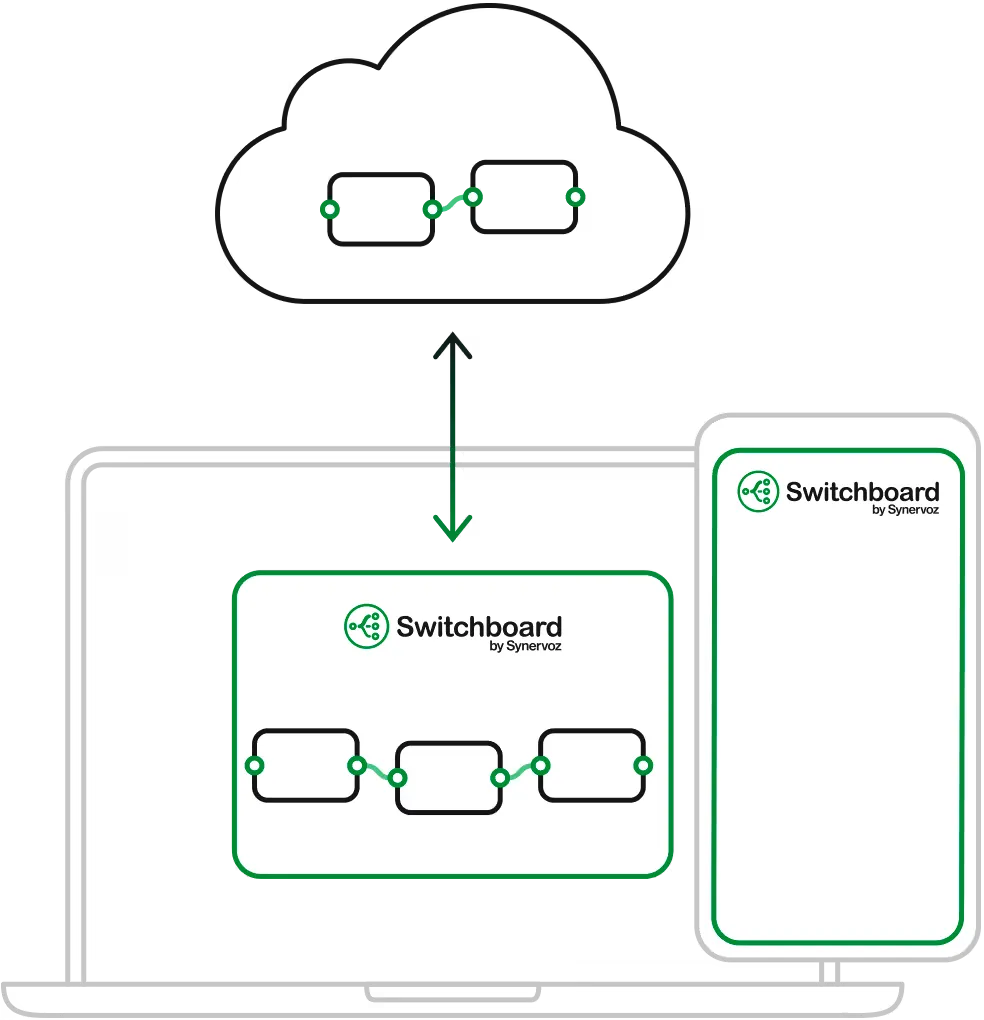
[Learn more](https://switchboard.audio/hub/your-voice-ai-bill-is-telling-you-to-go-hybrid-on-device/)
## Open source repositories
Production-ready examples and reusable components to accelerate your voice AI development
## [OpenAI Realtime Toolkit](https://github.com/switchboard-sdk/openai-realtime-toolkit)
React Native
Build voice-first AI agents with OpenAI Realtime and native audio primitives. On-device voice activity detection, turn detection, and barge-in handling make real-time conversations responsive while simplifying the audio pipeline.
OpenAI Realtime•VAD•Turn Detection•Tool Calling
[View on GitHub](https://github.com/switchboard-sdk/openai-realtime-toolkit)
## [EdgeSpeech](https://github.com/switchboard-sdk/edgespeech)
React Native
On device speech recognition (ASR / STT) and text-to-speech (TTS) so that you can cut costs and latency while simplifying cloud infra. You only send text to the LLM so don't have to worry about webRTC, sockets, or scaling audio in the cloud.
STT (local)•LLM (cloud)•TTS (local)
[View on GitHub](https://github.com/switchboard-sdk/edgespeech)
## EdgeAudio
Coming soon
Swift, Kotlin
On-device preprocessing for speech to speech models (aka S2S or audio models). On device voice activity detection (VAD), echo cancellation, and other audio preprocessing runs locally before connecting to cloud-based speech model (such as OpenAI Realtime API) to optimize performance.
VAD•Echo Cancellation•Specific Speaker Recognition•OpenAI Realtime API
## EdgeWhisper
Coming soon
iOS, Android, macOS, Windows, Linux
Run OpenAI's Whisper speech recognition (ASR) model entirely on-device for maximum privacy and offline functionality across mobile and desktop platforms (iOS, Android, mac, Windows, Linux).
Whisper (local ASR)
## EdgeAgent
Coming soon
React Native
Run a full STT-LLM-TTS pipeline locally. The STT and LLM components each have optional hand-off (or fallback) to cloud alternatives.
STT (local)•LLM (local)•TTS (local)
## EmbeddedVoice
Coming soon
Linux (& custom upon request)
Optimized voice AI components for resource-constrained IoT and embedded systems, including smart speakers, wearables, and edge devices.
Embedded•IoT•Edge Computing
### Need to launch faster or build something custom?
Our team offers expert consulting and forward-deployed engineers to help you design, build, and ship exactly what you need on your timeline.
All of the above can be made available on any platform.
## Get in touch
Have a question or want to work together? We'd love to hear from you.
[Contact us](https://switchboard.audio/contact/)
## Additional resources
## [Voice AI resource hub](https://switchboard.audio/hub/)
Guides, tutorials, and best practices for building production voice AI applications.
[Explore](https://switchboard.audio/hub/)
## [On-device speech recognition](https://switchboard.audio/cases/on-device-stt)
Learn how companies are implementing local speech-to-text to reduce costs and improve privacy.
[Explore](https://switchboard.audio/cases/on-device-stt)
## [Building voice AI agents](https://switchboard.audio/cases/ai-agent)
Explore real-world implementations of conversational AI agents with voice interfaces.
[Explore](https://switchboard.audio/cases/ai-agent)
---
# Contact Us
> Contact Fusion. Get in touch.
---
# Contact Us
> Contact Us. Get in touch.
---
# Download SDK
> Focused on software for interactive voice and video chat projects with complex audio requirements.
[Download SDK](https://switchboard-sdk-android.s3.amazonaws.com/develop/SwitchboardSDK.aar)
## **INVALID DOWNLOAD KEY**
Sorry, the download key provided is missing or invalid. Please use the exact download link found in your Switchboard SDK delivery email.
---
# Frequently Asked Questions
> Frequently Asked Questions about Synervoz
What is Switchboard?
Switchboard is a modular audio SDK and real-time runtime that makes it easy to build audio- and voice-powered applications. It helps developers create low-latency, AI-enabled audio experiences that can run on-device, in the cloud, or both.
How does it work?
Switchboard uses an audio graph model. Each graph is a JSON-defined pipeline of modular audio building blocks like STT, TTS, noise suppression, voice changers, etc. These blocks can be chained together and run in real time.
What does it do?
Switchboard is a modular audio framework incorporating a large library of audio **nodes** `AudioNode`. These nodes can easily be put together into **audio graphs** `AudioGraph`. Switchboard passes these graphs into natively compiled C++ code that runs *fast,* across multiple platforms including iOS, Android, Mac, Windows, web, and embedded platforms.
Audio graphs can be defined in JSON or native languages, making them easy to build while providing complete flexibility at runtime.
Switchboard also has a visual (no-code) node-based editor, the Switchboard Editor, which generates JSON automatically for rapid configuration of audio graphs that can easily be designed and tested in the browser and deployed to many target platforms.
It also allows you to tune parameters for each node or change the audio graph at runtime, rapidly speeding up development cycles.
What are audio nodes?
Audio nodes are essentially modular containers that process audio and include a wide range of functions such as: *speech to text, text to speech, large language models, voice changers, media players, streaming, voice* and *video calling*, the ability to *mix* and *split audio streams, DSP effects*, and much more.
Switchboard also includes [Extensions](https://docs.switchboard.audio/extensions/) to many other popular audio tools and SDKs, both open and closed source.
What platforms does Switchboard support?
Switchboard runs on iOS, Android, macOS, Windows, Linux, and the web. It supports edge compute, embedded systems, and hybrid architectures.
Why should I use Switchboard?
Whether you’re using it for a single node such as *speech-to-text* or a *voice changer*, or stringing multiple nodes together, Switchboard will:
* make it faster and easier to build, test, experiment, and get to market
* make it easier to maintain and make changes later
* save time and money
* drive new revenue and growth by simplifying the addition of new features
Who is Switchboard designed for?
* AI Agent and Voice AI solutions developers
* Real Time Communications (RTC) applications
* Music and social app developers
* R\&D / ML / AI teams looking to commercialize
* Hardware projects like headphones, speakers, wearables, etc.
* Pro audio industry - hardware and software
* Apps & SDKs with voice, VoIP, media players, and other audio features
* Product managers looking for a no code prototyping tool (Switchboard Editor)
See *Use Cases* in main menu for more details.
Can I use Switchboard for building AI voice agents?
Yes. Switchboard is ideal for running LLM-powered voice agents on-device or hybrid. It supports real-time STT → LLM → TTS pipelines, and gives you full control over audio routing, DSP, and model selection.
How does Switchboard help with voice interfaces in mobile apps?
Switchboard lets you embed voice control, transcription, and audio effects into mobile apps without relying on cloud APIs. It supports real-time pipelines optimized for low latency and power usage.
Is Switchboard good for noise suppression or voice enhancement?
Yes. You can bring your own noise suppression model (or use built-ins), and chain it with compressors, equalizers, or echo cancellation using Switchboard’s modular graph.
Can I use Switchboard for building multiplayer audio experiences?
Yes. Switchboard is compatible with WebRTC, LiveKit, Agora, and other voice and video chat frameworks. You can use it to build social audio rooms, watch parties, or spatial audio multiplayer environments.
How is Switchboard different from Agora or Twilio?
Agora and Twilio focus on cloud-hosted communications. Switchboard gives you control over audio processing, routing, and ML—locally or hybrid—making it ideal for more advanced or privacy-sensitive applications. Agora and other VoIP services are available as nodes in Switchboard. They normally function as an audio source (e.g. you can take the audio from a voice / video chat room) or a sink (you can put audio into the room). In short, you wouldn’t use Switchboard instead of either of these services, you’d use it in addition.
How is Switchboard different from Vapi?
Vapi and Switchboard serve different purposes. Vapi focuses on helping developers build agents, while Switchboard helps developers build audio graphs.
You could potentially use both Vapi and Switchboard in your project. For example, you might prototype an agent in Vapi. You might then use Switchboard to optimize an on-device audio graph to save on API costs or introduce more flexibility or to process audio in other ways that are not provided for as part of the Vapi platform.
Switchboard is a modular audio SDK and runtime that gives developers full control over the audio pipeline, letting them build custom real-time graphs with components like STT, TTS, voice changers, and noise suppression that run on-device, in the cloud, or in hybrid mode.
In contrast, Vapi is a hosted voice agent platform focused on telephony use cases, offering a pre-built stack that integrates APIs like ElevenLabs and Deepgram but limits customization and runs entirely in the cloud.
How is Switchboard different from Deepgram or AssemblyAI?
Switchboard is an SDK and runtime for building entire audio pipelines, while Deepgram and Assembly AI focus on individual components such as speech recognition. So, whereas companies like Deepgram and AssemblyAI provide their own speech to text (STT), text to speech (TTS), and related nodes, Switchboard lets developers combine these nodes, as well as many others (voice, music, and other audio related nodes) in a real-time audio graphs that can run on-device, in the cloud, or hybrid. Deepgram and AssemblyAI are typically cloud-only APIs that specialize in speech-to-text (and some related features) with little control over the underlying pipeline. With Switchboard, you can bring your own models, run them offline, chain multiple models or effects, and integrate with WebRTC or embedded devices—offering far greater flexibility, privacy, and lower latency than relying solely on hosted APIs. That said, you can run Switchboard graphs with nodes from Deepgram or AssemblyAI.
How is Switchboard different from Cartesia, or Eleven Labs?
Switchboard is an SDK and runtime for building entire audio pipelines, while Cartesia and Eleven Labs focus on individual components such as speech recognition or text to speech. You can run Switchboard graphs that use Cartesia or Eleven Labs nodes. For example, you can use the [Cartesia extension](https://switchboard.audio/partners/cartesia/) for Switchboard.
How does Switchboard compare to LiveKit or Daily.co?
Switchboard and LiveKit solve different layers of the real-time media stack. LiveKit is a powerful open-source infrastructure for media transport—handling audio/video routing, SFU/relay, and room-based sessions over WebRTC. Switchboard, on the other hand, is focused on audio processing and orchestration at the endpoint: voice activity detection, STT, TTS, noise suppression, LLM integration, and more. You can use them together—Switchboard for local audio graph processing (on-device or with cloud-connected nodes), and LiveKit to handle routing audio between multiple users. Switchboard doesn't replace LiveKit—it extends it by giving developers real-time, programmable control over what happens to the audio before or after it's streamed (see our [Partners/LiveKit](https://www.notion.so/partners/livekit) ). It’s similar with Daily.co and other webRTC providers. We offer some [Extensions](https://docs.switchboard.audio/extensions/) already and will continue adding more.
How does Switchboard compare to JUCE?
JUCE is a low-level C++ framework primarily used for building cross-platform audio applications, especially VST plugins and desktop DAWs. It provides powerful building blocks for UI, audio I/O, and DSP, but it requires deep expertise in C++ and lacks out-of-the-box support for real-time voice AI, on-device STT/TTS, or modular graph-based orchestration. Switchboard, by contrast, is a higher-level SDK and runtime focused on real-time audio and AI pipelines—with language bindings in Swift, Kotlin, and JS, plus support for live graph editing, bring-your-own-models, and hybrid cloud/on-device execution. Switchboard accelerates development for teams building voice-controlled apps, agents, or DSP tools—without the boilerplate and low-level threading work required in JUCE.
How does Switchboard compare to PortAudio?
PortAudio is a low-level cross-platform audio I/O library used to route audio to and from hardware devices. It’s ideal for simple stream management, but it offers no built-in DSP, audio graph management, or support for real-time speech and AI tasks. Switchboard, on the other hand, offers higher level abstractions—providing a modular audio runtime with real-time graph orchestration, support for AI models (STT, TTS, voice changers), and tight integration with mobile, desktop, web, and embedded platforms. While PortAudio is like wiring raw audio cables, Switchboard is like building a fully programmable audio processing studio—letting developers prototype and deploy advanced pipelines without writing audio I/O code from scratch.
How do I start using Switchboard?
You can start using Switchboard in two complementary ways:
### 1. SDK Libraries
Visit our Docs [Downloads](https://docs.switchboard.audio/downloads/) page, and select the individual libraries needed for your platform.
### 2. Switchboard Editor
Use the [Switchboard Editor](https://editor.switchboard.audio/), a browser-based tool to visually construct and test audio pipelines without writing code.
These methods work well together. You can visually prototype your audio pipeline using the Editor, which generates JSON configurations. Then, implement these configurations with the SDK libraries on your target platforms. This approach ensures your audio experiences sound consistent everywhere.
Note that while the Editor covers most functionalities, you may still need to use SDK libraries directly for advanced capabilities.
How do I define an audio graph in Switchboard?
Graphs are defined using a simple JSON schema. Each node specifies a module (e.g. TTS, media player, effect), its config, and its connections. You can create graphs by hand or with the Switchboard Graph Editor (GUI).
What languages does Switchboard support?
* Swift / Kotlin / JavaScript (bindings)
* C++ core engine
* Python
* WebAssembly (limited)
* Switchboard also supports frameworks such as React Native, Flutter, Unity etc.
See our [SDK API reference](https://docs.switchboard.audio/api/) and [integration](https://docs.switchboard.audio/category/integration/).
Where can I find docs and examples?
All documentation, SDKs, and example graphs are on the [Switchboard Docs Portal](https://docs.switchboard.audio/). You’ll find copy-pasteable starter graphs, pre-built modules, and real-time testing tools.
How do I get help from the Switchboard team?
For general inquiries and help, submit a request on our [Contact](https://www.notion.so/contact) page.
For existing customers, you can contact us directly via email.
For enterprise customers we’ll be happy to set up a private Slack channel for live support.
How do I install Switchboard?
Use npm (for JS), CocoaPods (iOS), or Gradle (Android). Prebuilt binaries are also available for C++, with support for native integration. If you can’t find the answer in our [Docs](https://docs.switchboard.audio/) portal, please [Contact us](https://www.notion.so/contact).
How do you mitigate dependency risk?
* Some parts of the SDK are Open Source. See [Introduction](https://docs.switchboard.audio/docs/introduction/) page.
* We offer world class support and broader [consulting services](https://synervoz-website-astro.pages.dev/services/product-consulting) through our parent company, Synervoz. Having this support interface (e.g. via a shared Slack channel) is a huge help for urgent requests and should help mitigate risk overall.
* Escrow is another option we are open to, but only for sizable enterprise deals.
Does Switchboard support BYO models?
Yes. You can plug in your own models, compiled to ONNX or other formats. Many open-source models already work out of the box (e.g. Whisper, Silero, RNNoise, etc.), and Switchboard provides extension templates for C++ and WebAssembly.
How do I use Switchboard with LiveKit or WebRTC?
Switchboard can ingest or output audio to WebRTC-compatible frameworks like LiveKit using media streams. Example integrations and a full LiveKit demo are available in the[ Switchboard GitHub repo](https://github.com/switchboard-sdk) and in the [Examples](https://docs.switchboard.audio/examples/) page of our docs portal.
Can I use Switchboard offline?
Yes. Switchboard supports fully offline audio processing pipelines for mobile, desktop, and embedded. This is perfect for apps that need privacy, low latency, or function in poor network conditions. Many nodes in Switchboard are on-device capable.
How much does it cost?
Switchboard has a free tier up to 20K activations and Commercial Licenses available thereafter.
Consult our [Pricing](https://www.notion.so/pricing) page.
How does pricing work for third party extensions?
Typically you would contract directly with the third party extension provider.
Nevertheless we have partnerships with certain providers so we encourage you to [get in touch](https://synervoz.com/contact) to discuss your use case and the extensions you’d like to use, as we may be able to help.
Can I get access to source code?
* Some aspects of Switchboard are already Open Source. You can learn more about this on our [Introduction](https://docs.switchboard.audio/docs/introduction/) page.
* We also provide [Example apps](https://docs.switchboard.audio/docs/examples) that are Open Source.
* We plan to continue our FOSS contributions and welcome partners to [get in touch](https://synervoz.com/contact).
* For the closed-source aspects of Switchboard, we may offer partial source code licenses based on your needs. This option is generally cheaper, faster, and more robust than developing it yourself. Pricing typically ranges from $XX,000 to $XXX,000, depending on the modules required.
Is there a free tier or trial?
Yes. Switchboard offers a free tier with full access to the SDK and limited usage caps. Switchboard supports many independent developers and zero cost prototyping through to launch. Generally limits are only hit as deployed apps start to scale, or if support is required.
Can I use Switchboard in a commercial product?
Yes, Switchboard’s licensing is designed for commercial deployment. It scales from indie apps to enterprise use cases. See our [pricing](https://www.notion.so/pricing) page.
Is Switchboard open source?
We open source a lot of example apps, starter templates, and other tools including the bring your own extension framework. The platform specific SDKs are generally closed source, though parts of it may be open sourced in the near future. The full commercial SDK is available under a flexible developer-friendly license. Partial source code licenses are also an option for larger customers. Contact the Switchboard team for custom pricing.
Is Switchboard proprietary?
Yes, Switchboard is a proprietary technology. However, we offer a free tier — please see our [Pricing](https://www.notion.so/pricing) page and [Master License Agreement](https://www.notion.so/licensing) for more details.
We also provide open source example applications. You are responsible for reading the license files contained with any distribution package.
We do our best to keep things simple and reasonable, while also supporting the open source community where possible.
Depending on what you build, it might also require a patent license. See [Patents](https://synervoz.com/patents) page.
Do you offer a warranty or Service Level Agreement?
We can provide this option if needed, but it is available only at the enterprise tier and will incur additional costs.
Otherwise, we offer support on a best-effort basis, and typically recommend a monthly support package to address this concern.
Do you also offer design and development services?
Yes we provide a variety of [consulting services](https://synervoz-website-astro.pages.dev/services/product-consulting) through our parent company, Synervoz.
Will Switchboard support embedded systems?
Yes. Embedded is a key target for Switchboard. Current builds already support ARM platforms and edge deployments. Optimizations for low-power devices are actively being developed.
Is Switchboard planning support for RAG pipelines or streaming LLM inference?
Yes. Switchboard already supports RAG and hybrid inference using local + cloud LLMs. Switchboard is not focusing on providing tools for prompt orchestration or conversational memory but these features can be obtained from other platforms, and your agents can be connected into your Switchboard audio graph. We are also able to help with custom development as needed. [Contact us](https://www.notion.so/contact) to learn more.
Can I run multiple LLMs in parallel in Switchboard?
Yes. The modular graph system allows orchestration across multiple models. So, for example, you might run a real time speech to speech pipeline in parallel with a speech to text / LLM pipeline that records and summarizes the conversation.
---
# The Audio Engine
Behind
Immersive Worlds
> Synervoz delivers spatial audio, voice chat, and real-time audio engines for gaming and metaverse platforms. Low-latency, cross-platform, production-ready.
Gaming & Metaverse Audio
Synervoz provides the spatial audio, voice chat, and real-time audio infrastructure that makes players feel truly present — across multiplayer games, VR/AR experiences, and metaverse platforms.
[Talk to an Audio Expert ](https://synervoz.com/contact)[Explore Switchboard SDK](https://switchboard.audio)

< 20ms
Audio Latency
10+
Platforms Supported
360°
Spatial Audio
10+ yrs
Audio Expertise
Core Capabilities
## Everything You Need to Build Standout Audio
Production-ready audio tools purpose-built for the unique demands of gaming and virtual environments — from competitive multiplayer to fully immersive XR.
### Spatial & 3D Audio
Full positional audio with HRTF-based binaural rendering. Players hear footsteps behind them, voices coming from specific directions, and environmental audio that shifts naturally as they move through the world.
HRTF Binaural Positional
### Voice Chat & Proximity Audio
In-game voice with realistic distance falloff, occlusion effects, and directional presence. Conversations sound natural whether players are side by side or across the map — no jarring volume cliffs.
Proximity Occlusion Falloff
### Low-Latency Real-Time Audio
Edge-optimized audio processing keeps latency under 20ms — essential for competitive gaming where a split-second audio cue determines the outcome. No buffering, no lag, no excuses.
< 20ms Edge Processing Real-Time
### Cross-Platform Audio Engine
One audio engine that runs on PC, console (PlayStation, Xbox, Nintendo), mobile (iOS, Android), and XR headsets. Write once, deploy everywhere — with platform-specific optimizations included.
PC Console Mobile VR/AR/XR
### Audio SDK & Integration
Clean C++ core with higher-level bindings for Unity, Unreal, iOS, Android, React Native, and Flutter. Integrates with your existing tech stack — game engines, streaming platforms, and third-party tools — without friction.
Unity Unreal C++ Core
### Noise Suppression & Voice Enhancement
AI-powered background noise removal keeps voice communication crystal clear during live play — even in loud environments. Keyboard clicks, fan noise, and ambient sound vanish. Your voice comes through clean.
AI Noise Removal Voice Clarity Real-Time
Use Cases
## Built for Every Type of Virtual World
Whether you're shipping a competitive shooter or building the next social metaverse, Synervoz has the audio infrastructure to match your vision.
### Competitive Multiplayer Games
Every millisecond matters. Ultra-low latency audio and directional cues give competitive players the edge they need — and the communication clarity to coordinate in real time.
* Directional audio for enemy detection
* Sub-20ms voice latency
* Team channel management
### VR / AR Experiences
Spatial audio is the difference between a VR experience that feels real and one that feels like a screen. HRTF rendering and head-tracking audio create genuine acoustic immersion in virtual space.
* HRTF binaural rendering
* Head-tracking audio
* Environmental reverb and occlusion
### Metaverse Platforms
Social metaverse platforms need audio that scales from intimate gatherings to massive live events. Proximity chat, stage audio, and zone-based broadcasting — all on one platform.
* Proximity voice for avatar interactions
* Stage/broadcast audio for events
* Multi-zone audio environments
### Game Streaming & Broadcasting
Content creators and esports broadcasts demand pro-grade audio. Clean voice capture, game audio mixing, and background noise suppression keep every stream sounding polished.
* Multi-source audio mixing
* Real-time noise suppression
* Low-latency stream output

Seamless Integration
## Drop In, Not Start Over
Synervoz is built to extend what you're already building — not replace it. Our SDK layers on top of your game engine and existing stack, so your team spends time on gameplay, not audio plumbing.
* Unity & Unreal Engine plugins
Native integration packages that fit naturally into your existing project structure and build pipeline.
* Third-party integrations ready
Pre-built extensions for popular voice communication services, analytics, and deployment platforms.
* Faster time to market
Skip months of audio R\&D. Synervoz's existing tech stack handles the hard problems so your team ships sooner.
Why Synervoz
## Audio Expertise You Can Build On
We've spent a decade solving audio problems that most teams don't even know to anticipate. That depth of experience is your unfair advantage.
### 10+ Years of Audio R\&D
Deep expertise across audio DSP, spatial algorithms, voice communication, and real-time systems — accumulated from shipping production software across multiple industries and platforms.
### Production-Ready Tech
Switchboard SDK isn't a prototype — it's battle-tested infrastructure deployed in real products. Your game ships on proven technology, not a science project.
### Ecosystem Integrations
Pre-built integrations and extensions for the tools your team already uses — game engines, voice platforms, streaming services — mean you're not starting from scratch on every connection.
### Edge-First Architecture
Audio processing at the edge means minimal round-trip latency. Players don't wait for the cloud to process a gunshot — it happens locally, instantly, where the action is.
### Expert Support Partnership
You're not buying a library and figuring it out alone. Synervoz engages as a technical partner — helping you architect the right solution for your specific game and player base.
### Faster Time to Market
Every integration, every algorithm, every tested audio path you can reuse is weeks off your development timeline. Ship sooner with confidence in what's under the hood.
## Ready to Make Your World Sound Real?
Talk to a Synervoz audio engineer about your game or metaverse project. We'll help you figure out exactly what you need — and get there faster than you expected.
[Start the Conversation ](https://synervoz.com/contact)[Explore the SDK](https://switchboard.audio)
Related Resources
## Go deeper
[Customer Story](https://synervoz.com/stories/unity/)
[Real-Time Voice at Scale with Unity](https://synervoz.com/stories/unity/)
[How we worked with Unity to deliver high-quality, low-latency voice communication for multiplayer games at scale — without the reliability headaches.](https://synervoz.com/stories/unity/)
[Read the story ](https://synervoz.com/stories/unity/)
[Venture Studio](https://synervoz.com/venture-studio/ronday-vs/)
[Ronday — Spatial Audio for the Metaverse](https://synervoz.com/venture-studio/ronday-vs/)
[Ronday is our own metaverse platform — built from the ground up with spatial audio and real-time voice as core primitives, not afterthoughts.](https://synervoz.com/venture-studio/ronday-vs/)
[Explore Ronday ](https://synervoz.com/venture-studio/ronday-vs/)
[Blog](https://synervoz.com/blog/multiplayer-gaming-audio-challenges/)
[Multiplayer Gaming Audio Challenges](https://synervoz.com/blog/multiplayer-gaming-audio-challenges/)
[A deep dive into the real technical problems of audio in multiplayer games — latency, synchronization, voice quality, and why solving them is harder than it looks.](https://synervoz.com/blog/multiplayer-gaming-audio-challenges/)
[Read the post ](https://synervoz.com/blog/multiplayer-gaming-audio-challenges/)
---
# Ship better audio products, faster
> Synervoz builds real-time audio software and SDKs for embedded hardware — Airoha AB1585 / AB1595, NXP RT600, Renesas RZ/V2H, Xtensa HiFi 4/5, and more. Firmware, DSP, voice AI, and companion apps for wearables, hearables, TWS earbuds, and smart devices.

Audio Hardware Solutions
From firmware to companion apps, Synervoz delivers the embedded audio expertise to bring your hardware to life — across headphones, wearables, smart speakers, TVs, game consoles, and more.
[Start a project](https://synervoz.com/contact/) [See our capabilities](#capabilities)
* Headphones
* Smart Speakers
* Wearables
* Smart TVs
* Game Consoles
* Automotive
Why Synervoz
Launch audio products\
faster, whatever the constraints
--------------------------------
Embedded audio is hard. Limited compute, tight memory budgets, strict power envelopes — we've navigated them all. Our engineers bring deep expertise in firmware, DSP, and audio middleware to help you hit your roadmap without compromise.
* Optimized for constrained SoCs — low memory, low power
* Production-tested across a broad range of hardware platforms
* Team augmentation or full-scope project delivery
* Green-field design or integration into existing stacks
[Discuss your project](https://synervoz.com/contact/)

What we do
## End-to-end audio software for hardware teams
Whether you're refining an existing product or building from scratch, we cover the full stack.
### Firmware Development
Low-level audio firmware for microcontrollers and DSPs. We handle boot sequences, driver layers, HAL design, and real-time audio pipelines on bare-metal and RTOS environments.
### Audio Optimization
Tuning audio algorithms for constrained resources — minimizing latency, reducing memory footprint, and managing power consumption without sacrificing sound quality.
### Companion Apps
iOS, Android, macOS, and Windows companion apps that extend your hardware — EQ control, firmware updates, voice AI configuration, and advanced audio settings.
### Middleware & SDKs
Custom audio middleware and SDK layers for OEM partners. Clean APIs that abstract hardware complexity so your app teams can build on top without embedded expertise.
### Testing & Validation
Rigorous audio quality testing, performance benchmarking, and field validation across device variants. We certify that your audio meets spec before you ship.
### Pioneering New Products
Have a novel concept? We can design your audio architecture from scratch — from initial feasibility through prototyping to production-ready code for your manufacturing partner.
Our work in context
## Powering the devices you use every day


Cross-platform
iOS · Android · macOS · Windows · Smart TV · Embedded
Technologies
## The stack behind great-sounding hardware
Our capabilities span the key architectures and SoCs used in today's leading consumer and professional audio products.
**Xtensa HiFi 4/5** High-performance DSP core for premium audio
**NXP RT600** Low-power MCU for wearables & hearables
**Airoha AB1585 / AB1595** TWS SoC for true wireless earbuds
**iOS / Android** Companion app development for mobile platforms
**Renesas RZ/V2H** On-device ASR and other voice AI technologies
**macOS / Windows** Desktop companion apps & audio drivers
**Smart TV Platforms** Tizen, webOS, Android TV audio integration
**RTOS / Bare-metal** FreeRTOS, Zephyr, and custom schedulers
**Voice AI / DSP** Wake word, AEC, noise suppression, beamforming
How we work
## From brief to production
A straightforward engagement model built around your timeline and team.
1
### Discovery call
We learn about your hardware, constraints, and timeline. No-commitment scoping session with our engineers.
2
### Technical assessment
We review your existing codebase, SoC specs, and audio requirements to define scope and flag risks early.
3
### Build & iterate
Embedded in your team or operating independently, we deliver working code in sprints with clear milestones.
4
### Test & ship
Rigorous validation, performance benchmarking, and knowledge transfer so your team owns the outcome.
## Ready to build great audio hardware?
Tell us about your project and we'll come back with a straightforward plan.
[Start the conversation](https://synervoz.com/contact/) [See all services](https://synervoz.com/services/)
---
# Investors
> Access information for Synervoz investors and partners. Learn about our financial strategy, market potential, and trusted investment community. Synervoz's investors including: Lowercase Capital, Slack Fund, Techstars, Liberty Global, Hedgewood, Tribal Scale, Globalive, CFC Media Lab, 500 Startups.
##### TRUSTED PARTNERS


[Get in Touch](/contact)
---
# Sound Technology
> We help companies build next-gen audio products using real-time Voice and AI, at the edge. Explore the Switchboard SDK for social, gaming, and immersive experience solutions.
Real-time Voice and AI, at the edge.
[Get Started](/contact)
**TRUSTED BY CUSTOMERS AND PARTNERS LIKE**
* 
* 
* 
* 
* 
* 
* 
* 
***
### We are audio-focused software engineers
Synervoz builds software for Real Time Communications (RTC), Consumer Electronics, Media & Entertainment, and technology companies. Our products and services encompass voice technologies, Voice AI, audio and video streaming, webRTC, music, digital signal processing, audio AI and machine learning, and span all platforms including mobile, desktop, web, smart TVs, embedded devices, and gaming consoles.
We design and co-develop apps, SDKs, and entirely new features and products. We power skunkworks with cutting-edge real-time tech and audio-focused AI.


Switchboard simplifies the creation of powerful audio software.
* Quickly build sophisticated audio engines without diving deep into low-level C++ or audio programming details.
* Create audio pipelines that perform consistently across iOS, Android, macOS, Windows, Linux, and the Web.
* Easily integrate audio processing nodes and AI models.
* Prototype audio experiences rapidly in a no-code / JSON environment before implementation.
[Explore Switchboard ↗](https://switchboard.audio/)
[](https://switchboard.audio/)
We have developed new apps and SDKs from scratch, as well as jumped into existing projects with hundreds of engineers, scaling to reach millions of users.
We have collaborated with R\&D teams to innovate and develop projects from prototype through production.
We don’t guard our ideas; we share them with equally passionate development partners and co-develop them under various models.
You have an idea. We can help research, design and prototype it to help get buy-in from stakeholders or investors.
Our domain expertise positions us to provide strategic advice, make introductions, build business cases, and establish new companies.
If you are interested in a Synervoz service click the link below to see how we can help.
### 1/6 - Voice, video and hangouts
Specialized solutions for:
* Voice AI agents
* Voice controlled applications
* Voice and video chat products
* Custom WebRTC solutions
* Innovative communication technologies such as drop-in and handsfree intercom.

### 2/6 - Music and podcast
* We pioneered the listening party
* Invented 'smart ducking' and ‘3D ducking’
* Built experiences to share and synchronize music
* Created new karaoke experiences
Leverage our existing tech stack to make your audio sound better, or to streamline integration with services such as Spotify, Dash Radio, YouTube Music, and live broadcasting platforms like OBS, Millicast (Dolby.io), and Amazon IVS.

### 3/6 - Watch parties, games and social apps
Complex audio challenges arise when combining voice or video chat with other media sources such as games, TV, social videos, and anything else with sound. Synervoz has unique technologies and expertise to help address noise, echo, voice detection, ducking, spatial audio, and more.
We’ve also designed, built, and operated our own products, giving us unique insights on everything from user experience to licensing and business models.

### 4/6 - Remote collaboration and metaverse
* We built “Slack for Audio”
* We have a 3D virtual office platform
* We build metaverse spaces with spatial audio
* Virtual concerts, TVs, arcades, and other venues
* Customizable 2D and 3D online collaboration spaces
* Web-first, Unity, or Hardware-specific

### 5/6 - Hardware and embedded
Customization and optimization of software to tackle hardware constraints such as limited compute, memory, and power. We also offer a comprehensive range of design and development services for firmware, middleware, and companion apps across all platforms. Headphones, speakers, VR/AR, and more.

### 6/6 - Pro audio
In addition to software engineers, the Synervoz team is made up of musicians, DJs, and producers. We combine our musical expertise with software engineering precision to cater to audio professionals, musicians, and hardware manufacturers. Whether it's building plugins, high-end devices, or a next gen digital audio workstation (DAW), we empower your creativity.

Our flagship product. An easy-to-use cross-platform SDK for audio software development. It includes a no-code editor to design audio pipelines, test them in the browser, and deploy instantly to multiple platforms.
Ronday is our metaverse building platform. It includes multiple 3D spaces, multiplayer communication with spatial audio, video, screen sharing, and more. It can be customized to your needs.
Our venture studio encompasses various projects: past, present, and future. We’re always interested in collaboration and co-development opportunities, so reach out if anything looks interesting!
---
# Legal & Privacy
> Terms of Service (“User TOS”).
**Introduction**
These User Terms of Service (“User TOS”) are a legally binding agreement between Synervoz Communications Inc. and its related companies (the “Company” or “we” or “Synervoz”) and you. By using or accessing the Switchboard application (the “App”) on any of our platforms, including iOS, macOS, our web app, or any website connected to domain [www.synervoz.com](http://www.synervoz.com) (the “Site”), which are collectively referred to as the “Service”, you agree to these Terms. The Company may modify these terms at its discretion and you will continue to be bound by these revisions. If we make material changes we will provide you with reasonable notice prior to the changes taking effect by emailing you or notifying you through the Service. Should you object to any changes your only recourse is to stop using the Service. You can review the most current version of the User TOS here. By using or accessing the Service, you agree to the following terms.
**You Must be Over the Age of 13**
You represent that you are i) over the age of 13 ii) the age of majority in your jurisdiction and have read, understood, and accept to be bound by these terms and iii) if you are between 13 and the age of majority in your jurisdiction, that your guardian has reviewed and agrees to these Terms.
**By using the Service, You Agree to Our Usage Policy**
The Service allows for voice, textual, and other forms of communication with other users of the Service. The Company will not under any circumstances be liable for activity by any user of the Service, nor will it be liable for any content posted to the Service. The Company may terminate your access to the Service for any reason, without notice. As a condition of your use of the Service you agree not to:
* harass, abuse, or act with ill intent towards anyone
* communicate with children under 13
* use the Service for spam, telemarketing, or other similar communications
* use the service to coordinate any unlawful activities
* attempt to obtain private information from other users
* attempt to transmit data infected with a virus or any other software that could damage the operation of the Service or other users’ computers
* violate any other user or person’s rights including intellectual property rights, information rights, privacy rights, trademarks, copyrights, patents, trade secrets, and any other right
* make false claims to the Company about other users
We reserve the right to determine what constitutes inappropriate usage and we reserve the right to take action where appropriate including the termination of your access to the Service.
**Data Policy**
By using the service you agree to our Data Policy. We collect certain information when you use the Service. This includes information that you use to register with us, and any voice recordings that you elect to share with us. Users that elect to share their voice recordings with us do so in order to help us improve the service by using our software to improve the quality of communication on the Service. All information is collected anonymously and is used solely for the purpose of teaching our software to better recognize a user’s voice.
Additionally, our service may ask for access to your address book, calendar, facebook account and email address and we may collect information from them at any time. Collection of this information will be for the sole purpose of improving the service, developing new services.
**Your Account**
You are responsible for your log-in credentials and for any activity that results from the use of your log-in credentials. Upon launching the service for the first time, you will be prompted to create an account to use certain features by providing various log-in details including a valid email address. You are responsible for maintaining the confidentiality of your log-in credentials. You agree to notify us immediately at if the confidentiality of your credentials has been compromised. You agree that we will not be liable for any loss or damage arising from unauthorized use of your credentials.
**Information – Provided by Synervoz**
Information provided by Synervoz (“Synervoz Information”) is for your personal use only. Synervoz owns this information. You agree not to copy Synervoz Information: i) for commercial purposes; ii) in a manner that violates another person’s privacy; iii) for any reason that might violate applicable laws. Synervoz does not guarantee the accuracy, quality, or integrity of user content posted. You accept that you may be exposed to offensive or objectionable material and that Synervoz will not be liable for any such content.
**Information – Collected by Synervoz**
You agree that Synervoz can store, use, learn from, and share information, data, and content in accordance with its Data Policy. You will continue to own intellectual property rights associated with any content you share, such as photo, video, and musical content. It is also your sole responsibility to ensure you have the rights to share any content. You hereby grant Synervoz all rights necessary to provide the Service in connection with the content you share. If any others have rights in the content you share, you further promise that you have the rights to grant Synervoz the necessary rights to this content. These rights shall constitute a perpetual, non-exclusive, transferable, royalty-free, sublicensable, and worldwide license to use, host, reproduce, modify, adapt, publish, translate, distribute, perform, display, and create derivative works from, your content. Synervoz reserves the right to remove and permanently delete your content for any reason.
**Information – Not Allowed**
You agree not to provide any information that could violate copyright laws, any federal or state laws, privacy laws, defamation laws, or that might otherwise cause harm of any kind to you or the Company. If the Company learns that a user under the age of 13 or a minor that has provided information without parental consent it will delete that information.
**Copyright Complaints**
The Company asks users to respect the intellectual property of others. If you believe your work has been copied in a way that constitutes copyright infringement, or that your intellectual property rights have been otherwise violated, you should notify the Company. In accordance with the Digital Millennium Copyright Act and other applicable intellectual property laws, the Company will investigate any alleged infringement and take appropriate actions. Please contact us at with infringement complaints. An infringement complaint requires the following information:
A statement by you that you believe that the disputed use is not authorized by the copyright or the intellectual property owner, its agent or the law along with an electronic or physical signature of the copyright owner or authorized person
A signed statement by you, made under penalty of perjury, that your infringement complaint and all information contained in the supplied information is accurate and that you are the copyright or intellectual property owner or are authorized to act on the copyright or intellectual property owner’s behalf
A description of the copyrighted work or intellectual property
Information that will help us locate the material that you claim is infringing on your copyright or intellectual property
Your contact information, including your address, telephone number and email address
Counter-notice: If you believe your Content was removed and is not infringing, or if you have written authorization from the Copyright or intellectual property’s owner or agent to upload and use the content, you may send a written counter-notice to . A counter-notice requires the following information:
A signed document that A) identifies the content that has been removed or to which access has been disabled and a description of the location at which the content appeared before it was removed or disabled, B) provides a statement from you that you believe in good faith that the content was removed or disabled as a result of mistake or misidentification of the content and C) your contact information, including name, address, telephone number, and email address
**Indemnification**
You agree to indemnify the Company from any loss, liability, claim, demand, damages, cost and expenses, including reasonable attorneys fees, arising out of or in connection with your use the service. As used in this section, “you” shall include anyone accessing the service using your password.
**Waiver**
Under no circumstances will the company be liable to you or to any third person arising from use of the service. This includes any consequential, incidental, special, punitive or other indirect damages, including any lost profits or lost data arising from use of the service. The Company shall not be liable for user content or the defamatory, offensive or illegal conduct of any third party and that the risk of harm or damage from the foregoing rests entirely with you.
**Severability**
The User TOS will be enforced to the fullest extent permitted under applicable law. If any provision of this Terms of Service is held by a court of competent jurisdiction to be contrary to law, the respective provision will be removed and all other provisions of this Terms Of Service remain in effect
**Assignment**
You may not assign any of your rights or delegate your obligations under these User Terms of Service, whether by operation of law or otherwise, without the prior written consent of us. We may assign these User Terms of Service in their entirety without your consent to a corporate affiliate or in connection with a merger, acquisition, corporate reorganization or sale of any of our assets.
**Governing Law**
The User Terms of Service represents a legally binding agreement and any disputes arising will be governed exclusively by the internal laws of the Province of Ontario.
**International Use**
The service and the transmission of applicable data, if any, is subject to United States export controls and any download or use of the software must not be in violation of U.S. export laws. You agree to comply with local rules and laws regarding your use of the Service, including as it concerns online conduct and acceptable content.
**Fees**
Basic functionality of the Service is free for use. We may charge fees for certain features which will be displayed on our platform. It is your responsibility to pay any appropriate government taxes, fees or service charges from a transaction occurring through the Service. We are not responsible for collecting, reporting or paying any such taxes, fees or service charges except as may otherwise be required by law.
**Communications with Synervoz**
You agree that we may communicate with you by email or through the Service in connection with customer service and the provision of the Service. This includes, but is not limited to, electronic mail, text messages, voice messages, live voice over IP, and push notifications.
**Contacting Synervoz**
You may contact us at or to report anything you believe is a violation of these Terms.
---
# Patents
> Explore the patented audio technology developed by Synervoz. View our published patents protecting key innovations in real-time communication and social audio.
**PUBLISHED PATENTS**
[US11150866B2](https://patents.google.com/patent/US11150866B2/en?q=\(Synervoz\)\&oq=Synervoz)
[US9462115B2](https://patents.google.com/patent/US9462115B2/en?oq=US9462115B2)
[Get in Touch](/contact)
---
# Press
> View Synervoz in the news. Explore press coverage, media mentions, patents, and articles on our partnerships and real-time audio innovations.
###### webRTC Ventures interview
[Play](https://youtube.com/watch?v=_7C6bJHP5QU)
**PUBLISHED PATENTS**
[US11150866B2](https://patents.google.com/patent/US11150866B2/en?q=\(Synervoz\)\&oq=Synervoz)
[US9462115B2](https://patents.google.com/patent/US9462115B2/en?oq=US9462115B2)
**ARTICLES**
[*LiveOne partnership*](https://www.globenewswire.com/news-release/2025/07/03/3109778/0/en/LiveOne-Nasdaq-LVO-Partners-with-Synervoz-for-Voice-AI-and-B2B-Growth.html)
[*American Genius*](https://theamericangenius.com/tech-news/app-turns-phone-intercom-great-remote-teams/?utm_source=facebook\&utm_medium=Social\&utm_campaign=AG)
[*SXSW Interview*](https://austinstartups.com/sxsw-startups-switchboard-d9c6422051d5)
[*SXSW Finalist*](https://schedule.sxsw.com/2018/events/PP98293)
[*Slack Investment*](https://betakit.com/slack-reveals-11-more-companies-backed-through-its-106-million-fund)
[*Liberty Global Video*](https://www.youtube.com/watch?v=yLadwKUFjIY)
[*MaRS Future Of Work Challenge*](https://betakit.com/intelocate-takes-home-resolvetos-100000-investment-prize)
[*Virgin Media Webinar*](https://www.virginmediabusiness.co.uk/insights/voip-webinar/play-voip-webinar)
[Get in Touch](/contact)
---
# Revolutionize your operations with humanoid robots
> Revolutionize your operations with humanoid robots. Deploy humanoid robots to optimize efficiency, safety, and innovation in your operations.
Deploy humanoid robots to optimize efficiency, safety, and innovation in your operations.
### Leading the robotic revolution
Fusion stays ahead of trends to help our customers stay ahead of competitors. Our **robotics rental business** pairs humanoid robots with human experts that can help train and adapt them to your operations. We help you learn, experiment, and deploy a robotics strategy to lead the competition in cost efficiency, safety, and innovation.
[Get started](https://synervoz.com/contact-us/)
[](https://synervoz.com/contact-us/)
### Tailored solutions for every sector
Focusing on industries that demand precision and resilience, we deliver bespoke robotic solutions to the **automotive manufacturing** and **mining** sectors, ensuring that every robot we deploy is optimized for the specific challenges and needs of your industry.
[Get started](https://synervoz.com/contact-us/)
[](https://synervoz.com/contact-us/)
We assess your operational needs and challenges.
Assess feasibility, potential ROI, and integration scope.
We tailor robots to your workflow.
Your team learns the skills to manage and work alongside robots.
Seamless robot integration into your daily operations.
Ongoing assistance and optimization to ensure peak performance.
[Get started](https://synervoz.com/contact-us/)
* **Increase Efficiency:** Robots work tirelessly, reducing downtime and increasing output.
* **Enhance Safety:** Take on hazardous tasks and reduce workplace accidents.
* **Boost Innovation:** Implement cutting-edge technology that pushes your operations ahead of the curve.
* **Scalable Solutions:** Easily adjust your robotic workforce as your business needs evolve.
---
# Untitled
> Index page showcasing all the Synervoz services available, providing a list of solutions, tools, and resources offered.
An extension of your team with access to our entire pool of experts.
Custom development services for companies within our domain of expertise.
Get to market faster. Save time and money by starting with our existing tools.
When you need to design and build software from the ground up.
Defining requirements, collecting data, and implementing solutions that fit within your constraints.
We bring AI models into production in constrained environments.
---
# AI and ML Services
> We specialize in bringing AI models into production in constrained environments. Synervoz can help optimize models to ensure compute and memory constraints are met, while conforming inputs and outputs to other parts of the application to which they will be connected.
We specialize in bringing AI models into production in constrained environments.
[Get started](/contact)

It’s one thing to have a team of researchers who can build artificial intelligence and machine learning models. It’s another to bring those models into production.
### Model optimization
Synervoz can help optimize models to ensure compute and memory constraints are met, while conforming inputs and outputs to other parts of the application to which they will be connected.

* Build a mobile app or prototype to demonstrate the capabilities of your in-house model.
* Integrate open-source models into your application or internal system.
- Build systems that combine multiple models in series and in parallel.
- Determine what’s possible and design the system to optimize for: device constraints, latency, security, and user experience.
We’ve done this in multiple real time audio applications so if anyone can make it work, we can.
### At the edge
Many AI models currently run in the cloud. However, you might prefer to run your model at the edge (on device) for various reasons:
* to minimize latency
* ensure security and privacy
* reduce bandwidth costs.
Achieving this requires leveraging AI acceleration capabilities on your target device and optimizing the model itself. We specialize in this area, especially with audio and related models like LLMs, Speech-to-Text, and Text-to-Speech.

### On all platforms
Whether you're aiming to target multiple platforms such as desktop (macOS, Windows, web, Linux), mobile devices (iOS, Android), or embedded systems, Synervoz offers extensive expertise in AI across all these platforms. In addition, our internal technology, like the Switchboard SDK, significantly accelerates the deployment of AI models across multiple platforms.

This includes our ONNX extension, which can help bring your model into production:
* without needing to build or maintain your own SDK
* adding support for more platforms (if you do already have a library)
* providing support for additional languages and frameworks (e.g. React Native, Flutter, etc.)
* providing extensibility with other Switchboard features

### AI agents
Our Switchboard SDK offers flexible AI agent solutions, enabling easy creation and deployment of audio graphs. It supports various features like speech-to-text, LLMs, and language translation, allowing for quick integration into diverse use cases such as customer service, social apps, and entertainment. Models can run in the cloud, on-premises, or on-device.
[Learn more](https://switchboard.audio/cases/ai-agent/)
[](https://switchboard.audio/cases/ai-agent/)
### Reduce cost and time to market (TTM)
Any of our services can be integrated into solutions that use our SDK and/or pre-existing source code. This can help reduce hours and TTM.
[Let's talk ➜](/contact)
[](/contact)
---
# Needs Assessment
> Optimize your project's success. Get expert needs assessment for technical requirements, data collection, and solution implementation with Synervoz.
Helping you define requirements, collect data, and implement solutions that fit within your constraints.
[Get started](/contact)

Our approach combines technical insight with hands-on support—ensuring you have what you need to move from planning to deployment with clarity and confidence.
We start by understanding your goals, technical constraints, and target user experience. From there, we work with your team to define technical requirements and identify the most promising implementation alternatives.

### Collaborative process
We ask questions until we understand your business problems, desired outcomes, and assumptions inside out. From there we discuss the optimal user/customer journeys to get you there. As these needs come together with technical and cost constraints, technical solutions emerge. We discuss the pros and cons with you to further iron out the true constraints and priorities -- which typically evolve over time. We help you estimate the costs of alternatives, allowing you to make informed decisions.

After performing a needs assessment, we will know whether using our SDK is a viable alternative. When it is, it typically saves on engineering costs and time to market. When it isn’t, we’ll tell you. Our goal is to minimize your total cost while maximizing reliability.
We can help you integrate and deploy the SDK while training you on its capabilities. Moreover, where there are gaps, we can help you fill them by designing custom nodes, wrappers, or other features to help integrate in your use case. A few hours from our team can save many hours for yours.
Our support doesn’t stop at launch. We offer continued consultation as your product evolves—answering questions, advising on scaling, and helping you make the most of future Switchboard updates and features.
For partners who see **Switchboard** as a solution that extends their own product’s capabilities, we offer free ideation and training sessions as well as offer tools to help with cross promotion, including demos in some cases. See our [Switchboard Partner Page](https://switchboard.audio/partners/) for more details.
### Reduce cost and time to market (TTM)
Any of our services can be integrated into solutions that use our SDK and/or pre-existing source code. This can help reduce hours and TTM.
[Let's talk ➜](/contact)
[](/contact)
---
# Product Consulting
> When you need to design and build software from the ground up. Whether you've validated product-market fit or simply have a basic napkin sketch, we can help craft a top-tier user experience.
When you need to design and build software from the ground up.
[Get started](/contact)

As an experienced product team we embrace a collaborative approach to help drive success. We align your product goals with the dynamic needs of your audience.
### Human-first design
We craft immersive digital products that blend creativity, innovation, and our audio technologies with behavioral science to deliver exceptional experiences and drive sustainable growth.

Whether you've validated product-market fit or simply have a basic napkin sketch, we can help craft a top-tier user experience.
* Product conceptualization
* Research & Testing
* UX/UI Design
* Prototyping
* Design Systems (implementation and optimization)
* Mobile and web development
* Technical architecture
* Software engineering

We can assist in choosing the right technologies, SDKs, and open-source code. We’ll clarify the trade-offs between building in-house and using off-the-shelf tools, and illustrate the short-term and long-term cost implications of different approaches.
Our experience with niche audio technologies overlapping features makes us more efficient and provides more reliable estimates compared to teams unfamiliar with similar technologies.
We can design and ship your minimum viable product by identifying the essential features required. This approach reduces cost while accelerating time-to-market.
We can help bring your product to market by leveraging our network of partners. Focusing on a narrow set of use cases and industries has helped us build a network that’s likely to include partners relevant to your project.

### Reduce cost and time to market (TTM)
Any of our services can be integrated into solutions that use our SDK and/or pre-existing source code. This can help reduce hours and TTM.
[Let's talk ➜](/contact)
[](/contact)
---
# Software Engineering
> Custom development services for companies within our domain of expertise. Synervoz works with companies building products using voice and audio technologies and especially those used in media, entertainment and online collaboration. While we have unique expertise in real-time audio software development, we can ultimately work across any part of your stack on any feature or task, whether audio-related or otherwise.
Custom development services for companies within our domain of expertise.
[Get started](/contact)

Synervoz works with companies building products using voice and audio technologies and especially those used in media, entertainment and online collaboration.
### Any platform, any issue
While we have unique expertise in real-time audio software development, we can ultimately work across any part of your stack on any feature or task, whether audio-related or otherwise.

* iOS: Swift, Objective-C
* Android: Kotlin, Java, Android NDK, JNI
* C++
* React Native, Flutter
- C++, Javascript, Typescript
- WebAssembly
- Node.js, Next.js
- React, Angular, Vue
- MongoDB, Post greSQL
- Websockets, Elastisearch
- AWS, Google, Azure cloud services
- Symfony, Drupal
- Java, Ruby
- Docker, Kubernetes
- Python, Matlab
* JUCE, Superpowered, AudioKit
* Audio Units, CoreAudio, AAudio
* VST
* AudioWorklets, WebAudio, ToneJS
* Machine learning techniques for audio
* TensorFlow, ONNX
* Digital Signal Processing (DSP)
* webRTC / XMPP / VoIP services
* Faust, Supercollider
SOCs and chipsets for headphones and speakers:
* Embedded Linux
* Yocto Linux
* Porting and optimizing ML models
* Xtensa HiFi DSPs for audio, voice, and speech (HiFi 4 and HiFi 5)
* GAP9, RISC-V
* ARM Cortex
* FreeRTOS
- Nintendo, Playstation, XBox
- Smart TVs
- VR Headsets
* DevOps, CI/CD
* App Store Distribution
* Opsec / infosec / appsec
* CMake
* Agile methodologies
* Figma ideation, design, & rapid prototyping
* Testing & ongoing support
### We are entrepreneurs
**What sets us apart:**
* [Our Story](/story) sets us apart from other alternatives or agencies, giving us a competitive advantage in our industry.
* Our products—which include our [Switchboard SDK](https://docs.switchboard.audio), as well as [new experiences](/venture-studio/) that we design, prototype, and co-develop with our partners (often using the SDK).
* Our niche industry focus, expertise, and thought leadership in shared media experiences.
* Our approach, risk appetite, partnership, and business model.

We bring a depth of knowledge and a one-of-a-kind toolkit that’s crafted for innovation and efficiency.
Part of your core engineering team. Like an employee with more flexibility, capacity, and access to deeper pool of knowledge across our entire team. [Learn more](/services/staff-augmentation)
If you think of us as ‘outsourced’ or ‘external’ you’re missing an opportunity. We do best when we’re an integral part of your team performing core tasks with daily comms on Slack.
Nobody else has our [SDK](https://switchboard.audio), sample apps, test apps, and other assets we can leverage. Chances are we’ve built something similar before, so we can be multiples more efficient with each hour.
### Reduce cost and time to market (TTM)
Any of our services can be integrated into solutions that use our SDK and/or pre-existing source code. This can help reduce hours and TTM.
[Let's talk ➜](/contact)
[](/contact)
---
# Staff Augmentation
> An extension of your team with access to our entire pool of experts. Synervoz has unparalleled expertise, engineering talent, and a decade of experience in building audio products from concept through deployment.
An extension of your team with access to our entire pool of experts.
[Get started](/contact)

Synervoz has unparalleled expertise, engineering talent, and a decade of experience in building audio products from concept through deployment.
**TRUSTED BY PARTNERS LIKE**
* 
* 
* 
* 
### Our domain
**Software development for audio, media, entertainment, and online collaboration.**
Our team of engineers specializes in audio software projects as well as the overall products and industries where audio is a key component. These include ->
* ### Voice, video, and hangouts
* ### Music and podcast
* ### Watch parties, games, and social apps
* ### Remote collaboration and metaverse
* ### Hardware and embedded
* ### Pro audio
If more than one of these is included in a single product, even better. We have unique expertise and IP for use cases in which real time communication (RTC) comes together with other media, such as music, TV / streaming services, games, and other activities.
### Competitive advantage
We focus on projects within our domain to further enhance our competitive advantage as the largest pool of independent audio software development experts outside major players like Apple, Google, Meta, Amazon, Bose, etc. For these companies, we provide access to an additional talent pool, offering increased flexibility and agility.

Whether it’s mobile, desktop, web, embedded, or something else, if it touches our domain, we can help.
See our [Software Engineering](/services/software-engineering) services.
We can help design your product from research through to testing, prior to building it.
See our [Product Consulting](/services/product-consulting) services.
We understand the market and user behaviors in our domain. We also understand the competitive landscape, legal constraints, economics, and have a solid network of potential partners we can leverage.
### Versatile expertise
Once we start working with you, our capabilities span the full stack, allowing us to provide additional support to help expedite any of your most urgent issues.
**Example:
** You’re building a listening party app; our collaboration initially focuses on the complex audio components. However, our assistance isn't limited to this area; we can also help resolve general bugs or get non-audio features out the door faster.

We function as an extension of your team and work alongside your engineers, generally using shared Slack channels to work together on a day-to-day basis.
### Full-time equivalents (FTEs)
Not only can we act as an extension of your team, but we can draw upon a broader pool of experts, and we have the flexibility to involve different members of our team.
Rather than assigning specific individuals, we typically use the concept of FTEs—full-time equivalents. While that might mean that we dedicate some or all of an engineer’s time to your project for a specific set of tasks, it also provides the flexibility to involve someone else if that person is better suited to a particular task, to fill in gaps when someone is unavailable, or to speed things up to meet an important deadline.
We can offer fractional FTEs or multiple FTEs.

Staff Augmentation services start at $5,000 per month for a fractional FTE. Hourly rates decrease for longer duration contracts and higher numbers of FTEs.
Synervoz also offers tailored hourly consulting services designed to meet your specific needs, ensuring personalized solutions at competitive rates.
### Reduce cost and time to market (TTM)
Any of our services can be integrated into solutions that use our SDK and/or pre-existing source code. This can help reduce hours and TTM.
[Let's talk ➜](/contact)
[](/contact)
---
# Untitled
> Synervoz provides solutions for: Innovation,; Voice AI; Audio Hardware; Music, Media, and Social; Pro Audio; Gaming and Metaverse; Automotive; Communications; Other Industries.
Working with R\&D teams to bring new products to market faster and cheaper.
Integration of AI models and infrastructure into larger systems.
Firmware and embedded development for audio hardware.
Tools and pre-built software for music, media, and social applications.
For projects requiring high fidelity and customizable audio solutions.
Immersive audio solutions for gaming and virtual environments.
Automotive audio ecosystems and infotainment.
For anyone working on real time communications (RTC) solutions
Technologies and expertise that extend beyond the most obvious use cases.
---
# Intelligent Voice AI
for the Connected Car
> Synervoz brings production-grade voice AI to automotive — in-cabin assistants, wake word detection, noise suppression, and on-device speech processing built on the Switchboard platform.
Voice AI · Automotive
From wake word detection and in-cabin noise suppression to on-device voice assistants and infotainment integration — Synervoz delivers production-ready voice AI built for the demands of the automotive environment.
[Talk to an Expert ](https://synervoz.com/contact/)[See Capabilities](#capabilities)
Core Capabilities
## Everything You Need for Voice AI in the Vehicle
Production-ready voice AI tools purpose-built for the acoustic challenges and real-time requirements of the in-cabin environment — from driver interaction to infotainment control.
### Wake Word & Voice Trigger Detection
Always-on, low-power wake word detection that activates the voice assistant instantly — running entirely on-device, with no network dependency. Customizable trigger phrases for OEM or aftermarket branding.
On-DeviceLow PowerCustom Triggers
### In-Cabin Noise Suppression
Real-time acoustic echo cancellation (AEC), road noise reduction, and beamforming for multi-microphone arrays. Ensures clean voice capture even at highway speeds or with audio playback active.
AECBeamformingRoad Noise
### On-Device Speech-to-Text & NLU
Automatic speech recognition (ASR) and natural language understanding that runs locally — no audio leaving the vehicle. Fast, private, and functional in areas without connectivity.
ASRNLUOffline-First
### Voice-Controlled Infotainment
Natural language interfaces for navigation, media playback, climate control, and connected services. Works with Android Auto, CarPlay, and custom IVI platforms built on Linux or QNX.
Android AutoCarPlayIVI
### Speaker Identification & Personalization
Identify individual occupants by voice to personalize settings, preferences, and media recommendations automatically — without requiring a login or button press.
Voice IDPersonalizationMulti-Occupant
### Hybrid Cloud Orchestration
Coordinate on-device voice processing with cloud-based services for complex requests — keeping sensitive audio local while reaching cloud NLU or content APIs only when connected and appropriate.
Edge + CloudSwitchboardModular

Natural voice control — no buttons required

Broad ecosystem compatibility across OEM and aftermarket platforms
Use Cases
## Voice AI Across Every Automotive Context
From OEM in-cabin assistants to aftermarket infotainment and fleet telematics — Synervoz has the building blocks to match your deployment context.
### OEM In-Cabin Voice Assistants
Custom voice AI for production vehicles — branded wake words, always-on microphone processing, and natural language control of vehicle systems with sub-50ms response times.
* Custom wake word training & deployment
* Multi-microphone array processing
* Integrates with vehicle domain controllers
### Infotainment & Head Unit Apps
Build or modernize apps for Android Auto, CarPlay, and custom IVI head units. Synervoz bridges mobile audio stacks to in-vehicle platforms — including streaming, podcast, and entertainment apps.
* Android Auto & CarPlay adaptation
* Audio engine porting across platforms
* Voice-first UX for driver safety
### Fleet & Commercial Vehicles
Voice interfaces for fleet management, driver coaching, and telematics — designed for noisy commercial environments and operable hands-free to keep drivers safe and compliant.
* Hands-free dispatch & navigation commands
* Driver monitoring & fatigue detection signals
* Edge inference for connectivity-limited routes
### EV & Autonomous Vehicle Platforms
Voice AI for next-generation vehicle platforms — including cabin experience in autonomous vehicles where the driver may become a passenger, and energy-efficient audio processing for EV power budgets.
* Passenger-mode cabin voice experience
* Low-power audio pipeline for EV efficiency
* Prototype-to-production on Switchboard SDK

Platform
## Switchboard: The Flexible Engine Behind Production Automotive Voice AI
Building voice AI for the vehicle means dealing with platform fragmentation, acoustic variability, and the need to swap models as the technology evolves. Switchboard is the infrastructure layer that makes this tractable.
* Cross-platform from day one
A single C++ audio engine that targets iOS, Android, Linux, and embedded MCUs — deploy the same pipeline across head units, companion apps, and cloud.
* Swap models without rebuilding
Replace the wake word engine, ASR model, or TTS synthesizer as better options emerge — without rewiring the rest of your audio pipeline.
* Prototype fast, deploy with confidence
Switchboard Editor's no-code graph UI lets you wire up a voice pipeline in hours. Validate acoustic behavior, then deploy the same graph to production hardware.
* On-device by design
Privacy-first architecture keeps voice data local. No audio transmitted unless you explicitly route it — compliant with automotive data regulation and OEM security requirements.
On-Device Architecture
## Voice AI That Works Without a Signal
Connectivity in a vehicle is intermittent. Synervoz builds voice AI that operates fully on-device by default — so the in-cabin experience works at highway speed in the middle of nowhere, not just in parking structures with good Wi-Fi.
* Zero-Latency Wake Word
Always-on keyword detection with sub-50ms response — runs on the audio DSP or application processor, consuming minimal power even in sleep mode.
* Multi-Mic AEC & Beamforming
Our C++ audio engine processes microphone arrays in real time — eliminating echo from speakers, attenuating road and wind noise, and focusing on the speaker's voice.
* Offline-Capable ASR & NLU
Core speech recognition and command understanding run fully on-device using compact models optimized for automotive-grade SoCs — no network round-trip needed for most interactions.
* Intelligent Cloud Fallback
When connectivity is available, Switchboard can route complex requests to cloud services — seamlessly, without changing the application interface above it.
* Power-Optimized for EV & Embedded
Audio pipeline power profiling and DSP-offload strategies keep voice AI within automotive power budgets — critical for EV efficiency and always-on embedded deployments.
On-Device Voice Pipeline
Microphone Array
Multi-channel capture
AEC / Noise Suppression
Beamforming + road noise removal
Wake Word Detection
Always-on, <50ms trigger
ASR + NLU (On-Device)
Offline speech understanding
Cloud Services (Optional)
Complex queries when connected
Why Synervoz
## Audio Expertise Built for Automotive
Real-time audio and voice processing is the core of what we do — and we've been doing it for over a decade.
### 10+ Years of Audio R\&D
Deep expertise in audio DSP, microphone array processing, and real-time voice systems — built from shipping production software across mobile, embedded, and connected device platforms.
### Production-Ready Technology
Switchboard SDK is battle-tested infrastructure deployed in real products — not a research prototype. Your automotive deployment ships on proven technology.
### Embedded & Edge-Native
Our C++ core runs on resource-constrained automotive SoCs — not just cloud servers. We understand power budgets, memory constraints, and real-time audio scheduling at the hardware level.
### Model-Agnostic Architecture
We don't lock you into a specific ASR vendor or NLU provider. Switchboard's node-based design means you can swap models as the landscape evolves without rebuilding your stack.
### Ecosystem Integration
We can help integrate new functionality into your existing ecosystem. Whether you're working with DSP Concepts Audio Weaver, QNX Sound, or a custom stack, we can design integrations that fit your existing architecture.
### From Prototype to Production
Switchboard Editor lets you validate a voice pipeline in days. We work with you from proof-of-concept through hardware integration and production certification — not just the demo.
## Ready to bring voice AI into the vehicle?
Whether you're building an IVI app, integrating a custom voice assistant, or evaluating on-device audio AI for a next-generation platform — let's start with a technical conversation.
[Talk to an Expert ](https://synervoz.com/contact/)[Explore Switchboard SDK](https://switchboard.audio)
---
# Communications
> Experts in real-time communications (RTC). For telcos, online events, remote office meetings - Synervoz has products and services that can accelerate innovation.
For telcos, online events businesses, or anyone working on real time communications (RTC) solutions, Synervoz has products and services that can accelerate innovation.
### Thought partners
Differentiate from competitors by offering richer communications services such as a hands-free walkie-talkie, virtual meeting spaces, language translation, and customized team communication tools.
We are pioneers in the space and have extensive experience experimenting with new behaviors. Bring your own idea or build upon some of our experimental projects through our [Venture Studio](/venture-studio/).

### Technology partners
Communications start with audio I/O on a device. Synervoz has extensive tools that allow for rapid prototyping and experimentation with new audio and AI features.
Learn more about our [Switchboard](https://switchboard.audio/) SDK.

### Experts in RTC
Synervoz has extensive experience working on real-time communications (RTC) products. Leverage our team to augment yours or to build an entire project from soup to nuts.
Learn more about our [Staff Augmentation](/services/staff-augmentation).

---
# Real-Time Voice
Intelligence for
Modern Finance
> Synervoz delivers real-time voice AI for financial services — trader surveillance, deepfake detection, speaker verification, and on-device audio intelligence built on the Switchboard platform.
Voice AI · Financial Services
From trader communications surveillance to deepfake detection and speaker verification — production-grade voice AI built for the most demanding compliance and security environments in financial services.
[Talk to an Expert ](https://synervoz.com/contact/)[See Capabilities](#capabilities)
< 50ms
Processing Latency
10+
Platforms Supported
0
Audio Egress Required
10+ yrs
Audio Engineering
Core Capabilities
## Everything You Need for Voice AI in Finance
Production-ready voice AI tools purpose-built for the unique demands of financial services — from real-time surveillance to infrastructure-level architecture.
### Trader Communications Surveillance
Continuously monitor voice communications for market-abuse indicators — keyword and phrase detection, sentiment signals, and acoustic pattern anomalies — across voice channels at scale.
Real-TimeKeyword SpottingNLP
### Deepfake & Synthetic Voice Detection
Identify cloned, replayed, or AI-synthesized audio in real time using signal-level and linguistic analysis. Protect against voice-based social engineering targeting financial personnel.
Anti-SpoofingSignal AnalysisLiveness
### Speaker Verification & Biometrics
Passively verify caller identity throughout a conversation — no PINs, no challenge questions. Detect when an unauthorized or synthetic voice impersonates a known participant.
Passive LivenessVoice IDContinuous Auth
### Acoustic Anomaly & Anti-Spoofing
AI anomaly models analyze prosody, breath patterns, and acoustic coherence to distinguish genuine voice from presentation attacks, replay attacks, and injected audio streams.
Anomaly DetectionProsody AnalysisOn-Device
### Transcription & NLP Pipelines
Speech-to-text and NLP workflows tuned for financial vocabulary, regulatory language, and noisy trading-floor environments — integrated with existing surveillance and eComms platforms.
ASRFinancial NLPeComms
### Architecture & Data Integration
Design and implement data flows, transcription pipelines, and APIs that unify voice, chat, and trade data — connecting capture infrastructure to surveillance, fraud, and case management systems.
API IntegrationData PipelinesAudit Trail
Use Cases
## Built for Every Layer of Financial Voice Compliance
Whether you're modernizing trader surveillance, hardening authentication, or building a new detection pipeline — Synervoz has the infrastructure to match.
### Trading Desks & Broker-Dealers
High-volume voice environments where every call may be subject to regulatory review. Real-time monitoring, searchable transcription, and anomaly alerting built to handle trading-floor scale.
* Real-time market-abuse detection
* Searchable voice archive integration
* Low-latency alert delivery
### Fraud & Identity Verification
Call centers and IVR systems targeted by vishing and voice cloning attacks. Passive speaker verification and deepfake detection protect both customers and staff without adding friction.
* Passive identity verification during calls
* Deepfake detection at call-center scale
* Integration with existing fraud platforms
### Regulatory Compliance & eComms
Unified voice data capture and analysis that feeds directly into your existing compliance and eComms surveillance workflows — with auditable data flows for regulatory examination.
* Unified voice + chat + trade surveillance
* Auditable pipeline for regulatory review
* Connects to existing case management
### On-Premises Infrastructure Build-Out
Institutions that cannot route voice data through cloud APIs. Synervoz designs and implements fully on-prem voice AI infrastructure — from capture to analysis — within your security perimeter.
* Zero-egress architecture design
* Hardware-agnostic deployment
* Model isolation for risk governance
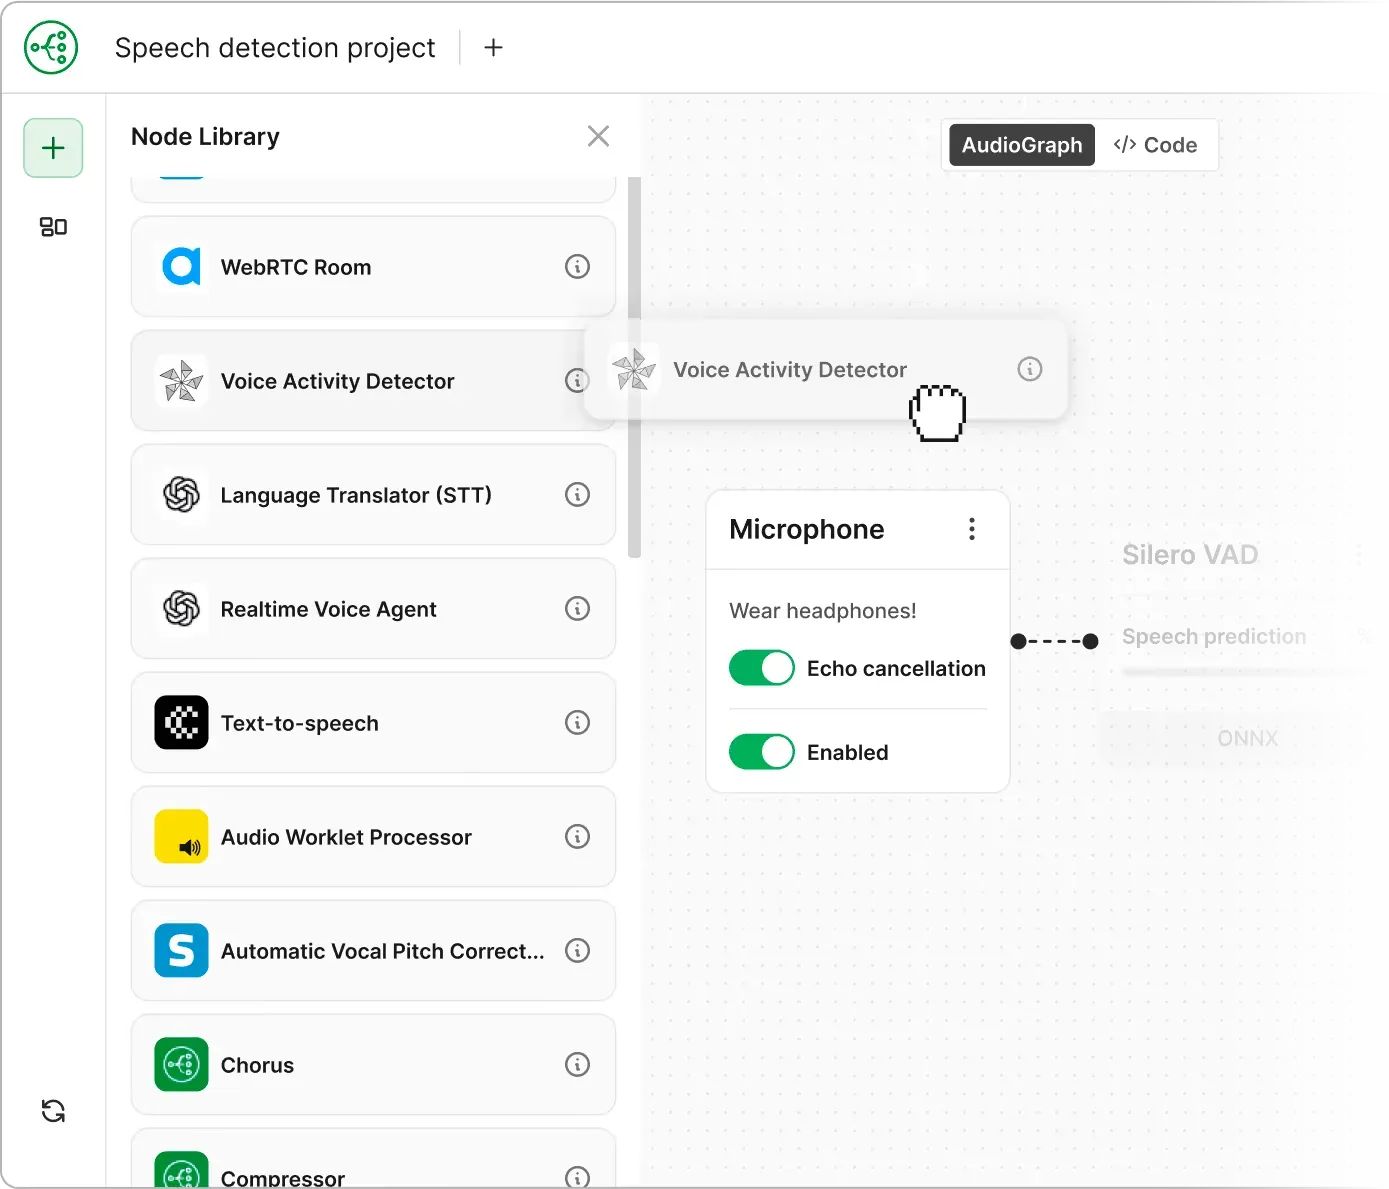
Platform
## Switchboard: The Flexible Architecture Behind Production Voice AI
Most voice AI projects stall at the integration layer — swapping models, connecting data sources, and wiring transcription to alerting is slow and brittle. Switchboard is the platform we built to solve this.
* Swap models without rebuilding
Replace the transcription engine, NLP model, or speaker-ID system without rewiring the rest of your pipeline.
* Connect new components easily
Every capability is a connectable node — add, remove, and reroute without touching upstream or downstream systems.
* Auditable for regulatory scrutiny
Explicit, documented data flows let you demonstrate to regulators exactly what happens to voice data at every stage — no black-box middleware.
* Prototype fast, deploy with confidence
Switchboard Editor's no-code graph UI lets you validate a new pipeline before writing a line of code — then deploy the same graph to production.
On-Device & On-Premises
## Voice AI That Stays Inside Your Perimeter
Financial institutions operate under strict data sovereignty requirements. Synervoz specializes in real-time voice AI that runs entirely on-device or on-premises — no audio leaves the building.
* Zero-Egress Architecture
Voice capture, transcription, analysis, and alerting all run within your infrastructure. No audio transmitted to third-party cloud services.
* Sub-50ms Latency at the Edge
Our C++ audio engine processes voice in real time — fast enough for live surveillance, active call monitoring, and instant fraud alerts.
* Hardware-Agnostic Deployment
From trading floor workstations to dedicated on-prem servers and embedded appliances — Synervoz voice AI runs on the hardware you already own.
* Hybrid Cloud Orchestration
Need on-prem capture with cloud-scale analytics? Switchboard cleanly separates sensitive processing from aggregation workloads.
* Model Isolation & Governance
Run AI models in isolated environments with explicit input/output contracts — meeting internal model risk management requirements without slowing delivery.
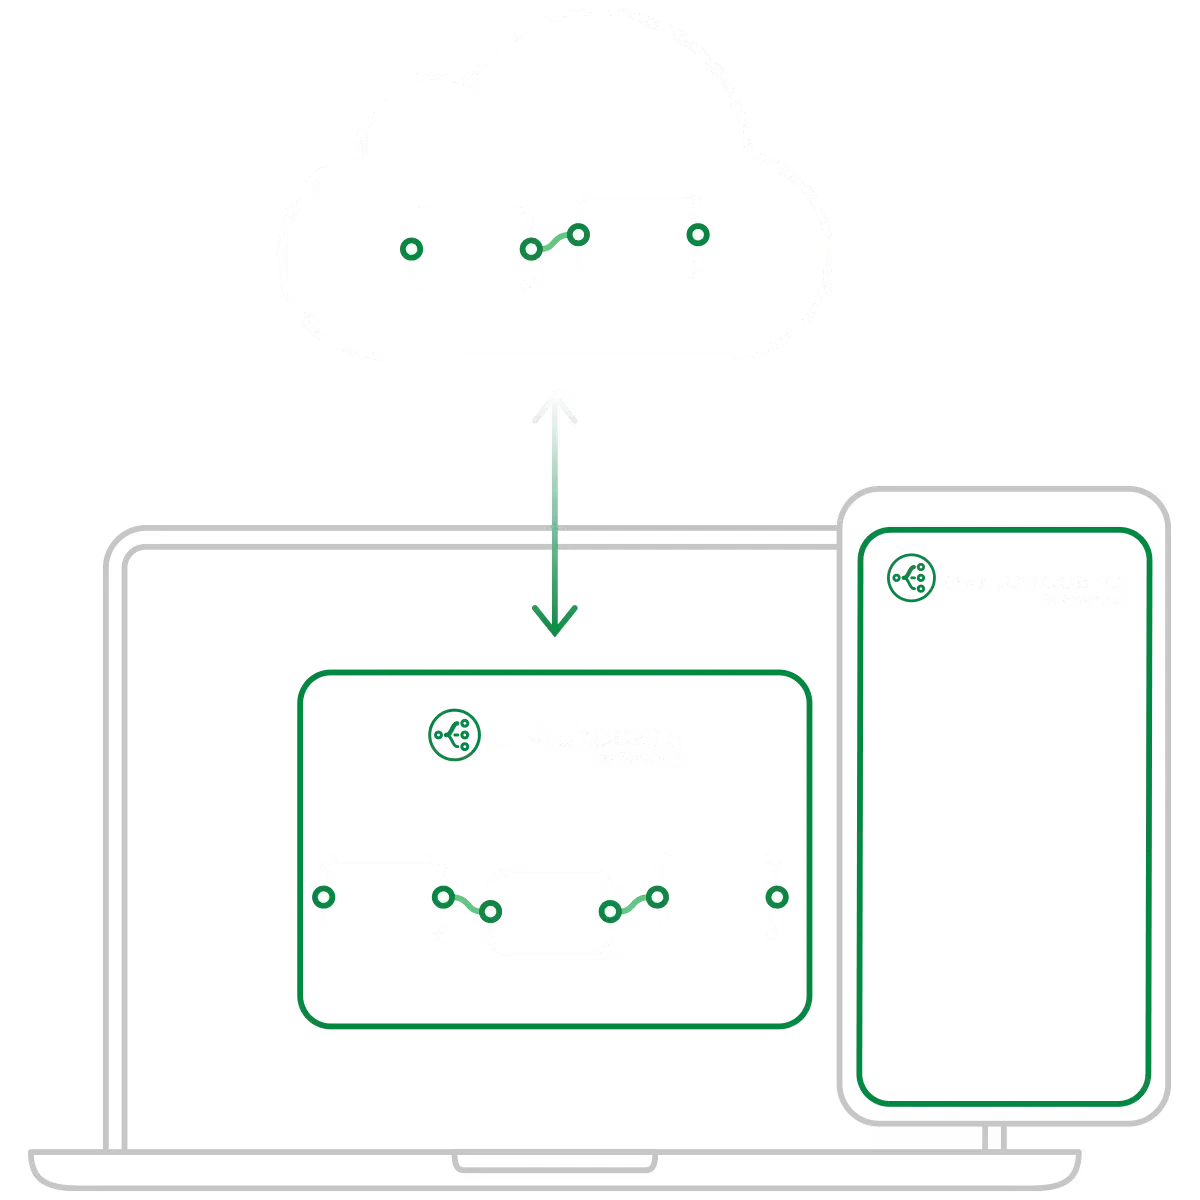
Why Synervoz
## Audio Expertise You Can Build On
We're not a generalist AI consultancy that added voice to its pitch deck. Voice and audio technology is the core of what we do.
### 10+ Years of Audio R\&D
Deep expertise across audio DSP, voice communication, and real-time audio systems — accumulated from shipping production software across multiple industries and platforms.
### Production-Ready Technology
Switchboard SDK is battle-tested infrastructure deployed in real products — not a science project. Your deployment ships on proven technology.
### Integration-First Approach
We design voice AI systems to fit your existing data infrastructure — trade surveillance platforms, eComms archives, case management, and incident response workflows.
### Model-Agnostic Architecture
We don't lock you into a vendor's transcription or NLP model. Switchboard's design means your infrastructure investment isn't tied to today's model generation.
### Expert Partnership Model
You're not buying a library and figuring it out alone. Synervoz engages as a technical partner — helping you architect the right solution for your environment and regulatory context.
### Rapid Time to Value
Using Switchboard Editor and our modular SDK, we can validate a voice pipeline in days and move to production deployment in weeks — not quarters.
## Ready to talk voice AI for your organization?
Whether you're evaluating vendors, modernizing an existing system, or exploring what's possible — let's start with a technical conversation.
[Schedule a Conversation ](https://synervoz.com/contact/)[Explore Switchboard SDK](https://switchboard.audio)
---
# Gaming and Metaverse
> Immersive real-time audio solutions built for in-game voice chat, metaverses, or virtual spaces. Synervoz builds engaging environments for your needs. Get started with us today!
Audio plays a pivotal role in gaming and virtual environments.
### Immersive audio should sound life-like
Spatial audio and robust voice chat are often central to the user experience, and should not be considered an afterthought.

Synervoz offers essential tools and services for creating engaging gaming environments.
Leverage our Switchboard SDK to optimize real-time voice communications so players can converse without delays or audio glitches, while also working seamlessly with music, voice changers, transcripts, and other audio features.
Leverage our Ronday platform to experiment with new virtual spaces or quickly build prototypes of 3D spaces with interactive objects such as TVs, arcades, and card tables you can actually use.
Leverage our voice effects in Switchboard or our Voicemod extension for anonymity or to give your users fun new features to help with engagement and retention.
We can help with spatial audio in the context of VoIP, objects placed in 3D worlds, and more through a combination of our products (like Switchboard and our partner extensions) and services.
We're familiar with common issues and tools such as: Unity, Vivox, Unreal Engine, Discord Activities, WWise, FMOD, Tencent GME, Photon, and more.

This involves optimizing compatibility, performance, and user interfaces to accommodate device and game constraints.
Whether you’re building a game or virtual space for remote work, Synervoz has a breadth of experience, existing tech, and integrations / extensions to third party tools that can help save you time to market and solve your audio problems faster.
---
# Audio Hardware
> Synervoz builds audio software for all platforms. This includes firmware and embedded development for pretty much any hardware with speakers and/or a microphone.
Synervoz builds audio software for all platforms. This includes firmware and embedded development for pretty much any hardware with speakers and/or a microphone.
From headphones and speakers to wearables, TVs, and game consoles, we have experience across a variety of form factors, operating systems, and highly constrained systems.

### Launch audio products faster
You may be facing challenging constraints: limited compute, memory footprint, power consumption, and more. We can do the necessary customization, optimization, and testing to bring your use case into production despite those constraints.
Let us help [augment your team](/services/staff-augmentation) to execute your existing roadmap faster or help to redefine what’s possible with your product by leveraging our creativity and experience.

### Pioneering new solutions?
We can design and build your software solution from scratch, whether it's firmware, middleware, or a companion app for higher level platforms like iOS / Android / Mac / Windows or a smart TV.

### Technologies we work with
We work deep in the embedded stack, across **Cadence Tensilica HiFi 4/5 DSPs** and SoCs including **NXP i.MX RT600, Airoha AB1585/AB1595, Renesas RZ/V2H**, and more. Our team brings real-time audio, DSP, and AI workloads onto constrained hardware—optimizing performance, latency, memory, power consumption, and integration with the surrounding device software.\
\
We deliver unparalleled audio experiences on all types of devices and operating systems, from firmware through companion app. Whether it's optimizing audio quality for headphones, speakers, or wearables, our expertise redefines the standards of sound engineering.

---
# Take Hospitality Voice AI Beyond the Demo
> Synervoz specializes in the real-time audio, voice, device and on-device AI infrastructure behind production hospitality experiences. Take your voice AI beyond the demo.
HOSPITALITY
Your AI might already know what to say. We help it work in the real world.
Big Tech is focused on the brain. We wire it to the body more efficiently.
[Discuss Your Project](https://synervoz.com/contact/) [Explore Switchboard](https://switchboard.audio)
WHERE WE COME IN
## Where are you today?
Either way, we can help.
If you’ve already started
You have a demo, a proof of concept, or a pilot underway. But real environments surface real problems — noise, latency, device fragmentation, flaky connectivity, integration complexity. We’ve solved these before. We can help you move from “works in the lab” to “works in production.”
* Diagnose and fix audio quality issues
* Reduce latency for real-world responsiveness
* Harden for edge devices and unreliable networks
* Integrate with your existing property systems
[Discuss your next project →](https://synervoz.com/contact/)
If you’re just getting started
We’re fast. Our team specializes in getting a production-grade voice AI prototype in front of real users quickly — on real devices, in real environments, with the infrastructure to scale. You don’t have to build the plumbing from scratch.
* Rapid prototyping on target hardware
* Production-grade audio pipeline from day one
* On-device + cloud hybrid architecture
* A working foundation you can build on
[Discuss your next project →](https://synervoz.com/contact/)
USE CASES
## Where Voice AI Shows Up in Hospitality.
These aren't demos. They're production challenges with real acoustic, latency, and integration requirements.
Guest Experience
### In-Room Voice Assistant
Guest asks for extra towels, adjusts the thermostat, or requests a restaurant recommendation — all via voice. Works without cloud dependency, responds in under a second.
Guest Experience
### AI Concierge
A voice-first front-of-house experience — available on lobby kiosks, in-app, or via phone — that handles FAQs, bookings, and property navigation without a human agent.
Staff Operations
### Housekeeping Copilot
Staff speak requests hands-free into existing radios or headsets. "Room 412 is ready." "Send maintenance to 8." AI logs it, routes it, and confirms — no app required.
Staff Operations
### Real-Time Translation
Staff and guests speak in their native language. Voice AI translates in real time. Eliminates communication barriers at the front desk, in restaurants, and at events.
Operations
### Maintenance & Facilities
Technicians report issues and receive work orders by voice. "Elevator three is down." AI creates the ticket, notifies the right team, and tracks resolution — hands-free.
Food & Beverage
### Voice Ordering
In-room dining, poolside ordering, or bar requests — all by voice. Integrates with existing POS systems and handles natural conversation, not just rigid commands.
CAPABILITIES
## We Build the Layer Between the Model and the World.
The model handles language. We handle everything around it — the audio capture, real-time processing, device orchestration, and infrastructure that makes it actually work.
### Real-Time Audio Processing
Noise suppression, echo cancellation, voice activity detection, barge-in, and turn detection — tuned for the unpredictable acoustics of real hospitality environments.
### On-Device + Cloud Hybrid
Not everything needs the cloud. We architect systems that run latency-sensitive and privacy-sensitive processing on-device, escalating to cloud models only when warranted.
### Staff Voice Copilots
Bring AI into radios, headsets, and phones frontline teams already use. Hands-free access to guest information, workflow triggers, and inter-department coordination — without a screen.
### Low-Latency Streaming
Voice AI that doesn't feel like a phone tree. We optimize end-to-end latency across STT, LLM, and TTS pipelines so interactions feel natural, not robotic.
### Cross-Platform Deployment
One audio engine across iOS, Android, embedded Linux, web, and custom hardware. Consistent behavior whether you're running on a guest room tablet or a staff radio.
### Resilience at the Edge
Connectivity drops. Networks fluctuate. We build systems that degrade gracefully — maintaining core functionality on-device when cloud access is interrupted.
[Talk to Us](https://synervoz.com/contact/)
ARCHITECTURE
## The Right Processing in the Right Place.
A hotel property may span hundreds of rooms, multiple staff teams, and a dozen device types. A one-size cloud architecture doesn't cut it.
We design hybrid pipelines that keep latency-critical and privacy-sensitive processing local, while using cloud models where they add the most value.
On-Device
Wake Word
VAD
Noise Suppression
Echo Cancel
Local Model
Selective escalation
Cloud
On-prem models
Frontier models
Fine-tuned SLMs
WHEN TO TALK TO US
## You Don't Need to Replace Anyone.
We're specialists in real-time audio and voice infrastructure. Many teams bring us in to fill that gap alongside their existing team.
Your demo sounds great but fails in a noisy lobby or real room
Latency is high enough that conversations feel awkward
You need to deploy across embedded devices, radios, or non-standard hardware
Cloud costs or connectivity constraints make a pure-cloud approach unworkable
You want a working prototype on real hardware, fast
Your AI team is strong on models but doesn't have real-time audio expertise
[Talk to Us](https://synervoz.com/contact/)
BUILT ON
## Switchboard SDK
Our proprietary audio SDK is our unfair advantage. A C++ core with a node-based pipeline architecture — deployable on iOS, Android, embedded Linux, web, and custom hardware.
When the project calls for it, Switchboard gives us capabilities no off-the-shelf stack can match. You can also license it directly to build and own your own pipeline.
[Explore Switchboard](https://switchboard.audio)
Input
MicStreamFile
Noise Suppression
Echo Cancellation
VAD / Turn Detection
STT
LLM Orchestration
TTS
Output
SpeakerStreamDevice
## Ready to Talk?
Tell us where you are. We'll tell you where we can help.
[Get in Touch](https://synervoz.com/contact/) [Explore Switchboard](https://switchboard.audio)
---
# Innovation
> Propel R&D to market with Synervoz's Innovation as a Service. We specialize in Voice AI, audio/DSP, real-time comms, and consumer electronics.
We work with R\&D teams to bring new products to market faster and cheaper.
### Our domain includes
* Software with real-time, on-device constraints
* Voice AI / voice tech & audio / DSP
* Real time communications (RTC)
* Consumer electronics
* Social and collaboration apps
* Music & entertainment
* Metaverse builders, and more

For these type of needs Synervoz can
### Build you new products with our Switchboard SDK.
### Leverage our Venture Studio products to experiment faster.
### Augment your R\&D team to commercialize your research.
### Fill the gap between R\&D and product
In many cases companies have powerful tech in-house that struggles to see the light of day. There exists a gap between the research team and productionizing that research.
Synervoz has worked with some of the world’s leading R\&D teams to bring cutting edge research to market through a combination of its product and service offerings including those mentioned above.

### Strategic insights
Gain clarity in a fast-moving landscape. Our domain expertise helps you decode complex market dynamics, spot emerging trends early, and uncover hidden competitive advantages. We work with you to translate insight into innovation—shaping strategies, products, and features that drive lasting value.
[Get started](/contact)
[](/contact)
### Rapid ideation and prototyping
Our Switchboard SDK, sample apps, and Venture Studio provide us with a platform for rapid experimentation, ideation, and building prototypes in hours instead of weeks, while end products can be built in days instead of months or more.

Licenses starting at
**For commercial projects**
***
• Implement yourself or\
• We can integrate it for you
See [**Pricing page**](https://switchboard.audio/pricing/?__hstc=60008626.7765192eda929b0b48572c12109a8732.1751569872519.1751569872519.1751569872519.1&__hssc=60008626.1.1751569872519&__hsfp=2756109930) on Switchboard's website to learn more.
Starting at
**For one FTE**
***
• Flexible staffing, from fractional to multiple FTEs\
• All experienced in Switchboard and other proprietary tools.\
• Multiply your team’s output
Customized solutions
**For larger enterprises**
***
• More flexibility\
• Source code licenses\
• Custom Switchboard built for you
---
# Music, Media and Social
> Increase engagement: Social products now thrive with music, TV, games, and activities. Synervoz provides solutions for seamless interactive media and audio integration.
Nobody wants to hang out in an empty chatroom. Social products have evolved, with music, TV, games, and activities on the rise to increase engagement.
We offer a comprehensive set of tools and pre-built software for **music**, **media**, and **social** applications. Leverage any of these resources to speed up your product launch:
* the [Switchboard](https://switchboard.audio/) SDK
* licensable source code
* our [venture studio](/venture-studio/) projects
* [white label](/white-label) offerings
* Development team [augmentation](/services/staff-augmentation)

[Get your free consultation ->](/contact)

Use [Switchboard ](https://switchboard.audio/)together with these services to make your app more interactive.
### Interactive media
Need your social app to integrate the capability to do things together. Like watch TV, listen to music, or play a game together?
Want to add shared activities to your social app? Features like watching TV, listening to music, or playing games together sound great, but they come with technical hurdles.

* noise
* echo
* voice detection
- mixing
- ducking
- volume normalization
* audio
* spatial audio
* Bluetooth limitations
and more...
***
Either you’ll be writing a lot of custom glue code or\
[get in touch](/contact) to see how we can help.
### Voice changers, audio effects, generative AI, and more
Want to integrate voice changers, autotune, or sound effects? What about speech to text, text to speech, or an LLM. Customized AI agent? Music generation? an AI assistant / LLM? We’ve got you covered there too.

Benefit from our flexible and modular Switchboard framework designed for rapid prototypes, experiments, and iterations. Our framework allows for quick adjustments, customization and enhancements, enabling you to iterate efficiently and adapt to evolving requirements with ease.
We provide support to seamlessly integrate prototypes and experiments into production-ready applications, improving efficiency and reducing downtime. Our team works closely with product managers and engineers throughout the development lifecycle to achieve optimal results.
---
# Other Industries
> Audio applications for consumer electronics, industrial automation, biomedical engineering, financial signal processing and more.
Our technologies and expertise extend beyond the most obvious use cases.
Digital signal processing (DSP) is crucial in ECG and EEG devices for analyzing physiological signals. By examining electrical activity from the heart and brain, these tools aid in diagnosis and health optimization. Synervoz can customize Switchboard or leverage its DSP expertise for various biomedical engineering applications, such as Heartscreen.
Switchboard is designed for use in audio processing pipelines, but it can be adapted for use in image and video processing pipelines as well.
For example, to classify or generate images and videos in multiple stages.
Instrumentation and control systems often involve real-time monitoring and control pipelines involving digital signal processing chains. For example, imagine an industrial process outfitted with microphones that are constantly monitoring for acoustic anomaly detection.
Our Switchboard technologies can be adapted for such purposes, and Synervoz can help customize solutions as necessary via our extensive ***services*** offering.
While our focus in the Consumer Electronics domain is Audio Hardware, a broad array of devices can benefit from both our Switchboard SDK and our Services.
Many devices rely upon signal filtering, noise reduction, as well as voice recognition and processing to enable voice-activated assistants, hands-free controls, and other interactive technologies.
Whether for analysis and prediction in financial markets or monitoring transactions for fraudulent activity, real time digital signal analysis and processing chains are commonplace in the finance industry. But generally technologies are aging, expensive to change, and lack flexibility. We can help solve that problem through a combination of the Switchboard SDK and our custom Software Engineering service.
---
# Pro Audio
> Building music tech applications, plugins, multi-track recorders, software to teach / learn music, hardware or anything in the audio space. Our products and services cater to both hardware and software projects requiring high fidelity and customizable audio solutions.
Our products and services cater to both hardware and software projects requiring high fidelity and customizable audio solutions.
### Music production
The Synervoz team is full of musicians and more than one of our software engineers also have their own recording studio. We have worked on numerous music tech applications, plugins, multi-track recorders, software to teach / learn music, as well as hardware projects for musicians and recording studios.

### Music and AI
We're among the most specialized partners you'll encounter in the music and AI space, whether you're a label seeking to create new value from old assets or a startup developing the next generation of music streaming applications.

We can help you integrate the following industry AI models into both new and existing projects, using a combination of tools and other AI models.
* 
* 
* 
* 
Note: These tools are currently integrated into our [Switchboard](https://switchboard.audio/) SDK.
[Get your free consultation ->](/contact)
### Podcast software
Robust audio engines are essential when it comes to building software for podcasts. Leverage the Switchboard SDK and our services to build a more robust product, faster.
* Virtual podcast studios
* AI video editor
* consumer apps (for listening / sharing podcasts)

### Commercial establishments
Developing a karaoke bar or equipping an event venue with a mix of hardware and software? We can assist. Our extensive experience enables us to lead in designing your system, recommending specific hardware, and building/customizing software as needed.

---
# Real-Time Voice AI
for the Modern Network
> Synervoz delivers real-time voice AI for telecommunications — network-embedded audio intelligence, voice fraud detection, subscriber platform enablement, and rapid innovation prototyping built on the Switchboard platform.
[](/_astro/hero-video.68726c18.mp4)
Voice AI · Telecommunications
From network-embedded audio enhancement and voice fraud detection to subscriber platform enablement and rapid innovation prototyping — carrier-grade voice AI built on the Switchboard platform.
[Talk to an Expert ](https://synervoz.com/contact/)[Explore Use Cases](#use-cases)
Use Cases
## Voice AI Across the Telecom Stack
Whether you're hardening network security, modernizing customer experience, enabling enterprise customers, or driving innovation — Synervoz has the tools and expertise to match.
### Innovation & Rapid Prototyping
For teams exploring what's next in network-embedded voice. Switchboard's node-based architecture and no-code Editor make it practical to rapidly validate new ideas before committing engineering resources.
* Drop-in voice & video communication features
* Voice-controlled user interfaces & smart home integration
* Immersive audio for AR/VR & spatial computing
* Voice AI over media streaming pipelines
* Prototype in days with Switchboard Editor, deploy the same graph to production
### Voice Fraud & Security
Voice fraud is evolving fast — deepfake audio, vishing, SIM swap, robocalls. Switchboard gives your team the audio pipeline to rapidly integrate and evaluate the best fraud detection and biometric models available, without rebuilding your stack each time.
* Plug in speaker verification and synthetic voice detection models via the node graph
* Experiment with multiple vendors side-by-side before committing
* Pre-process and route audio to existing fraud management systems
* Prototype and test on real call audio without production risk
### Network Audio Quality & Enhancement
Audio quality vendors are multiplying fast. Switchboard gives your team a common audio pipeline to rapidly evaluate and integrate noise suppression, echo cancellation, and enhancement models — on-device, at the edge, or within the media plane — without rebuilding around each one.
* Swap in different enhancement models without touching the rest of the pipeline
* Test and compare vendors side-by-side using the same call audio
* Deploy at any layer — device, edge, or in-network — using the same graph
* No rip-and-replace — layers into your existing voice infrastructure
### Customer Experience & Contact Centers
The best intent, transcription, and biometric vendors change year over year. Switchboard gives contact center teams the audio routing layer to rapidly plug in, evaluate, and replace models — without rebuilding your stack each time.
* Route call audio to any transcription or intent recognition model via the node graph
* Experiment with voice biometric vendors before committing to one
* Build post-call analytics pipelines that connect to existing CCaaS platforms
* Prototype new IVR flows in the Editor, deploy the same graph to production
### Subscriber & Enterprise Platform Enablement
Your enterprise customers want to ship voice AI features — but building the audio plumbing is slow. Switchboard SDK gives them a cross-platform audio engine they can embed and use to rapidly prototype and integrate voice capabilities across iOS, Android, desktop, and web, powered by your network.
* Cross-platform audio SDK your customers embed directly in their products
* Lets them experiment with wake word, assistant, and speaker ID models without building from scratch
* Node-based graph makes it fast to wire in new capabilities as the model landscape evolves
* Differentiated platform service — value beyond raw connectivity
### Compliance & Regulatory Obligations
Regulatory requirements vary by region and evolve constantly. Switchboard gives your team the flexible deployment architecture to build compliant voice capture and analysis pipelines — on-prem, hybrid, or zero-egress — and swap out the analysis layer as requirements change.
* On-premises and zero-egress deployment options
* Explicit, auditable data flows from capture to analysis
* Hybrid: on-network capture cleanly separated from analytics
* Architecture that adapts as regulatory requirements shift

Platform
## Switchboard: The Flexible Architecture Behind Production Voice AI
Most voice AI projects stall at the integration layer — swapping models, connecting data sources, and wiring real-time processing into existing infrastructure is slow and brittle. Switchboard is the platform we built to solve this.
* Swap models without rebuilding
Replace transcription engines, NLP models, or speaker-ID components without rewiring the rest of your pipeline.
* Integrate with existing network infrastructure
Designed to layer into your existing voice stack — not to replace it.
* Auditable, documented data flows
Every component in the graph has explicit input/output contracts — essential for carrier regulatory environments where opaque middleware isn't acceptable.
* Prototype fast, deploy with confidence
Switchboard Editor's no-code graph UI lets innovation teams validate new voice pipelines before writing a single line of code — then deploy the same graph to production.
On-Network & On-Device
## Voice AI That Lives Inside Your Network
Telcos operate under strict data sovereignty and latency requirements. Synervoz specializes in real-time voice AI that runs entirely on-network, on-device, or at the edge — no audio routed to third-party cloud APIs.
* Zero-Egress In-Network Processing
Voice capture, enhancement, analytics, and alerting all run within your infrastructure. No audio transmitted to third-party cloud services.
* Minimal Latency at the Media Plane
Our C++ audio engine processes voice in real time — fast enough for live call enhancement, active fraud monitoring, and instant alerting.
* Hybrid Architectures Supported
Need on-network capture with cloud-scale analytics? Switchboard cleanly separates sensitive real-time processing from aggregation and reporting workloads.
* Hardware-Agnostic C/C++ Core
Switchboard SDK is built on a portable C++ core with higher-level bindings — deploy to routers, set-top boxes, mobile devices, and network appliances, or custom hardware.

Why Synervoz
## Audio Expertise You Can Build On
We're not a generalist AI consultancy that added voice to its pitch deck. Voice and audio technology is the core of what we do.
### 10+ Years of Audio R\&D
Deep expertise across audio DSP, voice communication, and real-time audio systems — accumulated from shipping production software across multiple industries and platforms.
### Carrier-Grade C++ Core
Switchboard SDK is built on a portable, high-performance C++ core — the kind of infrastructure that belongs in a network, not bolted on from a web API.
### Integration-First Approach
We design voice AI systems to fit your existing infrastructure — IMS, VoLTE, SBCs, media gateways, contact center platforms — not to replace it.
### Model-Agnostic Architecture
We don't lock you into a vendor's transcription or NLP model. Switchboard's design means your infrastructure investment isn't tied to today's model generation.
### Expert Partnership Model
You're not buying a library and figuring it out alone. Synervoz engages as a technical partner — helping you architect the right solution for your network environment and regulatory context.
### Rapid Time to Value
Using Switchboard Editor and our modular SDK, we can validate a voice pipeline in days and move to production deployment in weeks — not quarters.
## Ready to talk voice AI for your network?
Whether you're evaluating vendors, hardening network security, or exploring what new voice experiences are possible — let's start with a technical conversation.
[Schedule a Conversation ](https://synervoz.com/contact/)[Explore Switchboard SDK](https://switchboard.audio)
---
# Voice AI
> Synervoz specializes in the integration of AI models and infrastructure into larger systems to develop end-to-end solutions for real world problems using real time voice and audio technologies.
Synervoz integrates **Voice AI models** and infrastructure into hybrid cloud / on-device systems to solve real world problems.
### Proprietary platform
Our [Switchboard SDK](https://switchboard.audio/) is a one of a kind tool, giving us an unfair advantage. It’s like an assembly line for Voice AI solutions, allowing us to help you get to market faster while saving time, money, and accomplish things that others can’t.

Switchboard also provides the flexibility to quickly test different models and infrastructure configurations. So if you want to compare using OpenAI, Llama, and other open source models, as well as different infrastructure options, Switchboard can help you do this much faster than custom building the pipelines yourself.

### AI agents
Synervoz has built AI agents for customer service, language translation, as well as social and entertainment purposes.
Our solutions include a combination of our products and services. See how our Switchboard SDK can help you build [AI agents](https://switchboard.audio/cases/ai-agent/). We can custom build any aspect of your solution, including the user interface, the models and infrastructure used, and tie it into your backend to retrieve information and automate processes.

### All devices with a microphone
Smart speakers, wireless earbuds, VR headsets, smart glasses, and other mixed reality devices, smartwatches, phones, laptops, TVs, and just about anything else with speakers and a microphone—AI will be embedded in all of these devices, and you will talk to it.
Whether you’re building a personal assistant for such devices or a solution that allows friends and colleagues to use these devices together, it will require specialized engineering skills that are in short supply.

Embedded audio pipelines, along with other software and firmware development for device manufacturers.
Custom development services for new and existing voice AI projects.
Our weapon for building complex audio graphs with ease on any platform.
### Custom voice apps
There are lots of apps for note taking during voice and video calls and off-the-shelf solutions for phone call answering, automated outbound sales calls, screening for interviews, creating podcasts, customer support, and most other things that can be done by Voice AI. But Synervoz can offer more...
[Get started](/contact)
* ### Need a bespoke solution that’s hooked up to your own data sources?
* ### That doesn’t share that data with third parties?
* ### That ties into your specific workflows and systems?
* ### Embedded in your own hardware?
Use CasesIndustries
**Call Center Automation**\
Switchboard enables fully customizable voice agents for call centers, allowing teams to rapidly update models, deploy across platforms, and stay ahead as AI and telephony tech evolves.
**Voice Controlled Devices**\
Integrate responsive, real-time voice interactions into embedded systems or edge devices with low-latency models tailored to your hardware and use case.
**New User Onboarding**\
Deliver personalized onboarding experiences through voice-guided flows that adapt in real time based on user input and contextual cues.
**In-App Technical Support**\
Embed dynamic voice assistants directly into your app to offer hands-free, conversational troubleshooting and product guidance.
**Virtual Assistants**\
Build integrated virtual assistants that can be fine-tuned, deployed on your infrastructure, and updated without vendor lock-in.
**Workflow Automation**\
Trigger, manage, and monitor complex workflows via voice commands—minimizing manual steps and enhancing productivity across tools and teams.
**Financial Services**\
Securely manage tasks like identity verification, account access, and onboarding with adaptable voice agents that meet compliance and latency requirements.
**Healthcare**\
Power patient enrollment, appointment scheduling, multilingual voice AI solutions deployed in controlled environments to maintain compliance.
**Education**\
Enable interactive learning experiences with voice-driven tutoring and responsive feedback that adapts to each student’s pace and language.
**Hospitality**\
Provide instant, voice-based concierge services, booking support, and language localization tailored to your brand experience.
**Telecom**\
Augment support flows with voice AI that can troubleshoot, upsell, or escalate as needed—on mobile, desktop, or embedded devices.
**Smart Homes**\
Enable intelligent device control and contextual voice responses, whether in fully offline, edge-deployed systems or cloud-connected platforms.
### Offline solutions
You know how to leverage models such as OpenAI in the cloud, but your project has constraints that prevent you from sending data over the wire. You need a fully offline or on-prem solution.
We’ve built voice AI pipelines and other LLM use cases that operate fully offline and can be deployed anywhere.
Whether it's offline language translation for classified meetings or another use case, we can help you build a solution that operates within the confines of a single device, local area network, or any other configuration required.

### Digital Transformation
Beyond generic voice conversations, businesses need industry-specific solutions. Generic chatbots won’t cut it. You need a multimodal AI that understands your industry’s lingo and can read documents, databases, and integrate with your CRM, scheduling, and other systems.
[***Fusion***](https://fusion.synervoz.com/) brings everything together. Imagine being able to talk to an AI that understands your customers, competitors, and can leverage your business’s data to provide new products, services, and internal tools. Fusion provides solutions beyond Voice AI and helps you transform your business in any part of your technology stack.

AI is shifting behavior back to talking instead of typing. As this happens, demand for real time audio solutions is outstripping supply of engineering expertise.
We’re here to help.
---
# Customer Stories
> Bose, Amazon, Meta, Jamstack, Kosmi, Campground, Unity, IBM, MRG Events, Audioshake, Slang.ai, Mayk.it, Superpowered, Heartscreen Health, Prism Sound, Beatbox, 3Fire Music, Voicemod, Rapchat, Riff, Rtyst, Kudo, JCA, Immersitech, Galamat, Loops by CDub, Sonix, Socan, MemoChat.
Discover how we’re building tailored audio experiences for a variety of customers.

***
**ENTERPRISE CUSTOMERS**
Synervoz has a long history of working with Bose on cutting edge R\&D projects spanning AI, embedded development, and porting algorithms to multiple software platforms.
Synervoz worked with Amazon on a first of its kind music streaming service, as well as with the IVS / Twitch team on new audio streaming use cases including a karaoke sample application.
Synervoz has worked with Meta on audio engine development, audio testing applications, and new product experimentation.
**FEATURED STORIES**
### Unity
Explore how Synervoz helped evolve the world's largest in-game voice platform with robust mobile support and real-time audio expertise.
[*See the story *](/stories/unity)>
[](/stories/beatbox)
### Beatbox
Transforming karaoke into a gamified, studio-quality social experience using our low-latency Switchboard audio platform.
[*See the story *](/stories/beatbox)>
[](/stories/beatbox)
***
### Jamstack
Revamping the companion control app and groundbreaking built-in effects engine for an attachable smart amp.
[*See the story *](/stories/jamstack)>
[](/stories/jamstack)
***
### Kosmi
A single place for watch parties, games, music and other apps with friends—all with voice and video chat.
[See the story](/stories/kosmi) >
[](/stories/kosmi)
***
### Campground
Music streaming parties where you can talk while listening to music together.
[*See the story*](/stories/campground) >
[](/stories/campground)
***
**ADDITIONAL CUSTOMERS AND PROJECTS**
Builds communities with a scalable communication solution that connects players across platform divides.
A global technology innovator, leading advances in AI, automation and hybrid cloud solutions that help businesses grow.
Aims to lead the event industry with the ability to seamlessly design and execute events of any scale.
A voice AI featuring a digital phone concierge service with multiple capabilities.
A Virtual Music Studio for next-gen music creators.
Provides audio, networking and cryptographics C++ SDKs.
Allowing doctors to listen to heart sounds remotely, and to find early heart disease.
Manufacturers of professional audio products for recording studios.
A breakthrough karaoke experience for everyone. Coming soon to NYC.
World leaders in multi-track music playback technology. Technology which is used to make apps for Apple and Android mobile devices.
Provides real time voice changers and a soundboard for gamers, karaoke, and more.
All in one platform for music creators. The easiest way to record songs on your phone used by millions around the world with over 200,000 free beats and instrumentals.
Built for Communities. Voice, Video, Chat with Music. Go live in your community chat room and connect with your audience live on voice & video in real-time.
A social video application that helps aspiring artists build an engaged fanbase, collaborate and compete for fame.
A multilingual web conferencing platform with human and AI-powered live translation. Run meetings and events in any language.
A nonprofit consulting firm that helps organizations leverage data and technology so you can do more, perform better, and dream bigger.
Powered by machine learning, our voice chat focused software provides your users with experiences that feel more connected and personalized. Solutions for noise suppression and spatial audio.
Music recording application with studio functionality where the user has the opportunity to record his/her voice over background music. Also known as Fuchuk.
Library of drum loops and click tracks, that have been created to be compatible with the most commonly performed gospel songs.
Lead your team to victory with the performance-oriented and personalized voice chat made for gamers.
Serving over 185,000 music creators and publishers, protecting their rights while licensing music and collecting and distributing royalties in Canada and around the world.
A voice messaging app that offers secure, effortless communication with fun voice filters, making it easy to express yourself and stay connected.
The world’s leading live entertainment company where you discover, buy tickets for, and experience concerts, tours, and festivals featuring top artists around the globe.
An all-in-one digital music and entertainment platform combining music streaming, podcasts, live concert and festival livestreams, curated radio stations, and original artist content.
---
# Beatbox
> A gamified karaoke experience in New York City, blending our software and A/V expertise.
Story

***
A gamified karaoke experience in New York City, blending our software and A/V expertise.

Beatbox Venue in New York City is transforming karaoke into a full-day social destination — serving food, drinks, and a deeply interactive music experience. Synervoz partnered with Beatbox to design and deploy a robust, low-latency audio platform built on [Switchboard](https://switchboard.audio/), integrating real-time lyric tracking, pitch detection, and responsive scoring.
Synervoz was involved in all parts of the stack including the UI and in-game experience, the audio software subsystem, hardware selection, and overall system performance, testing, and debugging.

***
“Switchboard and the team at Synervoz were incredible partners from concept to launch. Our gamified karaoke experience is unlike anything else, with complex coordination between hardware, audio software, and in-game UX. We couldn’t have pulled it off without them.”

## Sara Goodison
CEO of Beatbox
**Switchboard Audio Engine** – modular audio processing engine.
**Whisper (on-device)** – Switchboard node used for lyric transcription and alignment
**Unity integration via OSC** – synchronized message layer
**Pitch + lyric detection systems** – measures how well you're singing in real-time
**Audio effects + VST support** – pitch shift, autotune, reverb; making you sound better
**ASIO/WASAPI** – low-latency hardware interface and reliability layer
To achieve real time performance, Synervoz moved audio processing** outside of Unity and into Switchboard, dramatically improving speed and stability**.
We implemented **dedicated systems for pitch and lyric detection**, as well as **voice effects processing** systems, both optimized to minimize latency. **Whisper STT** was embedded directly into the audio engine and operates on-device as a Switchboard node, synchronized with game events to deliver precise lyric transcription and visual feedback.

Using **OSC** (**Open Sound Control**), the audio and game engines communicate through a tightly defined message layer — covering timing, message formats, and error handling — ensuring seamless coordination during every performance.

### Reliability by design
Beatbox operates in a live venue, so reliability was built into every layer. Synervoz improved fault tolerance, recovery, and synchronization to ensure the system remains stable under real-world use. Key improvements include ->
* ### Offline mode for continued operation when streaming services fail
* ### Lyric detection tuning to distinguish singing from spoken voice
* ### Enhanced debugging tools to trace and evidence stream issues
* ### Custom backgrounds for branded and sponsored sessions
### The result
Beatbox now delivers a venue-grade karaoke experience with studio-quality sound, reactive visuals, and instant feedback — all running locally for uncompromising performance.
Guests can pick a song, step up to the mic, and see their lyrics come alive with perfectly timed audio and effects powered by [Switchboard](https://switchboard.audio/).

Check out more customer stories: [Jamstack](/stories/jamstack), [Kosmi](/stories/kosmi), [Campground](/stories/campground)
---
# Campground
> Campground (formerly Roadtrip) allows its communities to collaborate on playlists and host listen parties (streaming music in sync while also being able to talk), making the internet a little less quiet.
Story

***
Campground allows its communities to collaborate on playlists and host listen parties (streaming music in sync while also being able to talk), making the internet a little less quiet.
### Listen Parties
A core feature of Campground is Listen Parties. This underpins the notion that music should be social, even when you can't be physically in the same place.
Listen Parties comprise two main components: synchronized music playback, and a persistent voice call so that people can spontaneously talk as if they're in the same room. Talking over a voice call while music is playing introduces complex audio issues like masking (can't hear the person because music is too loud), echo, and other issues introduced by operating system limitations (e.g. iOS and Android aren't meant to have calls + music simultaneously).
Fortunately, Synervoz are experts in this area. In fact, Listen Parties are how we got started as a company. A journey we shared with our friends at Campground.

### What we did
The Switchboard SDK is at the heart of Campground. It's audio engine allows for the mixing and management of multiple audio streams such as the VoIP connections and the music in real time.
Voice activity detection and auto-ducking (reducing music volume when someone talks) are among many important features provided by the Switchboard SDK.
We were also closely involved with the development team on a daily basis and contributed to many features and aspects of the app development.


All prototypes courtesy of [Campground](https://twitter.com/campgroundxyz).
Check out more customer stories: [Kosmi](/stories/kosmi), [Jamstack](/stories/jamstack)
---
# Jamstack
> A multi-platform control app that compliments the Jamstack 2: the world’s most advanced guitar amp.
Story

***
A multi-platform control app that compliments the Jamstack 2: the world’s most advanced guitar amp.

### What does the Control App do?
The Jamstack Control App allows users to effortlessly change guitar and bass effects. They can browse, craft, tweak, and share effects presets through the app. The customization is next level, as users can change their recording mode, wireless modes, dial in dozens of settings, and create their own presets.


### What we built
The app needed a revamp, particularly focusing on effects enhancements and fixes to the Android version. This involved stabilizing the Bluetooth connection between the app and amplifier chip, as well as:
* debugging existing code for new release
* creating a desktop updater
* removing fragmentation
* optimizing performance
* new, easier to use effects
* community features and gamification

***
“These guys are the best to work with. Fast, flexible, communicate clearly, and know audio inside out at every level of the stack; from firmware and Bluetooth to iOS and Android.”

## Chris Prendergast
CEO of Jamstack
Kotlin multiplatform was used to help build both iOS and Android platforms, ensuring a seamless user experience across both platforms. With the improvements to the Android version a user with either device could now get the same rockin’ experience!

### Conclusion
Synervoz was able to enhance the effects experience of the Control App, through new options and improved reliability, and continues to collaborate with Jamstack on new technologies.

Check out more customer stories: [Kosmi](/stories/kosmi), [Campground](/stories/campground)
---
# Kosmi
> Kosmi is a web app that makes it super easy to have watch parties and play games together online in virtual rooms with voice, video, and text chat. Kosmi brings together your favorite TV, movies, games, music, and other apps, all in one place. Just share a link with friends, family or coworkers to hang out in custom rooms and enjoy a number of different activities together.
Story

***
A virtual entertainment hub for friends, family, and co-workers.
### What is Kosmi
Kosmi is a web app that makes it super easy to have watch parties and play games together online in virtual rooms with voice, video, and text chat.
Kosmi brings together your favorite TV, movies, games, music, and other apps, all in one place. Just share a link with friends, family or coworkers to hang out in custom rooms and enjoy a number of different activities together.


### Audio challenges
Kosmi allows users to watch videos, play video games, listen to music, and use other apps together; all while on voice and video chat. But what happens when the audio from the media player leaks into the microphone?
Enter Synervoz: the Switchboard SDK helps to solve these issues, as well as positions Kosmi for cross platform initiatives that will allow it to be used with TVs and with various configurations of hardware.


Check out more customer stories: [Jamstack](/stories/jamstack), [Campground](/stories/campground)
***
---
# Unity
> Synervoz brought Vivox to mobile for Unity, drawing on a team that knows the platform down to its recording.
Story

Synervoz brought Vivox to mobile for Unity, drawing on a team that knows the platform down to its recording.

### The engagement
Synervoz worked with Unity on the Vivox SDK, which let Unity's customers deploy Vivox to game titles across desktop, console and mobile. We were brought on to improve mobile device support.
Vivox has been in production one way or another since 2006, and it was built desktop first. Making it run properly on mobile took real consideration, because mobile wants a mobile-first design. That reaches from how audio is captured and cleaned up on a phone to how a call holds together as the device moves between networks.

We took on the mobile side of the SDK. Unity's customers got echo cancellation, network roaming, and the other mobile essentials that make voice work well on a phone.
With those essentials in place, Unity's customers could ship Vivox on mobile the same way they already did on desktop and console. Voice became a first-class part of a mobile title.

Source: [Riot Games adds Vivox voice comms to its latest title](https://unity.com/resources/riot-games-adds-vivox-voice-comms-to-its-latest-title) — Unity
Check out more customer stories: [Beatbox](/stories/beatbox), [Jamstack](/stories/jamstack)
---
# Our Story
> Synervoz evolved from an app to the Switchboard SDK, now working with top companies to deliver next-gen audio experiences. We do everything audio. Today, we do anything and everything audio. We’re based in Toronto with additional offices in Vancouver, Budapest, and remotely.
We started Synervoz with a bold vision: to reinvent how people connect online — whether for work or play. Our first product was an audio-first social network with hands-free controls, Slack integration, and shared music experiences layered on top of live voice and video. It was ahead of its time. We shifted gears — turning our real-time tech into Switchboard, a powerful SDK that lets anyone build these kinds of next-gen experiences. The stage is now set to bring these features into in mainstream platforms. Today, we work with some of the biggest names in audio and real-time comms. We’re proudly based in Toronto, with team members in Vancouver, Budapest, and beyond.
Synervoz enters Techstars with an app that lets you talk (VoIP) while listening to music. A voice detector ducks the music when someone speaks.
Synervoz raises $1.5M from top investors like Lowercase and Slack to build Switchboard, an audio app for spontaneous communication including drop-in, voice commands, music, and more. “Audio-Slack”
Switchboard comes out of beta as one of the top products on Product Hunt and starts to grow. But there’s a problem, we don’t have Android yet, and we haven’t yet solved noise and echo suppression.
Realizing we’re early with our social audio vision, Synervoz pivots from B2C (an app) to B2B (an SDK + custom engineering). From here, Synervoz starts to grow from cash flow, rather than venture capital.
The pandemic hits, new behaviors take root including social audio, watch parties, and more. Meanwhile, we help productionize machine learning models for audio, making new use cases feasible.
Today we sell software and services to customers with advanced audio and VoIP needs. We also have internal projects and R\&D that we continue to advance; testing and iterating on new products and ideas.
In building out the Switchboard app, we touched a lot of audio technologies including webRTC, ML models for voice detection, speech to text and text to speech, noise and echo suppression, low level audio programming, and more. We also learned a lot about the limitations of high level audio frameworks like those available on iOS and Android. That led us to develop the Switchboard SDK.\
\
Check out our Venture Studios page to see some of the cool features we built for Switchboard, and to better understand some of what we could help you build lightning fast.
[Go to Venture Studio](https://synervoz.com/venture-studio/)
### Our team values and supports one another.
We’ve had some memorable moments along our journey and always make the most of it when we can meet together in person, whether its for events or a night out on the town.


Voice communication and music are in our DNA and have been the primary focus in our company evolution.

Go to [Switchboard ](https://switchboard.audio)to learn more about our internal projects and platform.
Dual undergrad from Queen’s. Top 1% of MBA class (IE, Spain). Background as a Professional Engineer, Manager, and in Finance. Started Synervoz in 2014. Designed product. Wrote patents (issued and pending). 2x Techstars founder, Creative Destruction Lab, 48 Hrs in Valley, Berkeley Skydeck. Won Canadian Music Week pitch contest, finalist at SXSW. Well-traveled (60 countries and counting).
U of T computer science, mathematics, and music tech background. Former reverse engineer for Telus with experience in security and communications. Proficient across multiple platforms and programming languages. Audio and real time systems expert. Music production studio owner. World’s first cyborg DJ (built and performed with embedded system). With Synervoz since 2015.
MSc. Advanced Software Engineering at Kings College, London. iOS expert level developer with in depth knowledge of object oriented (Swift, Obj C, C++, Java), scripting (PHP, JS, AS, Python), declarative (Prolog, Erlang) and procedural (C, Pascal) languages. Extensive experience with audio, VoIP, & webRTC. Multilingual (English, Hungarian, Italian). With Synervoz since 2016.
Thom led the Vivox engineering team at Unity where he scaled teams and systems used by millions worldwide. Thom has also helped launch and grow several startups. At Synervoz, Thom leads technical business development and GTM for Switchboard. He also helps manage engineering priorities, customer projects, and hiring. Thom studied Computer Science and Physics at the University of Toronto.
---
# Venture Studio
> Our lab to experiment with new ideas, cutting-edge tech, and build new prototypes and POCs. We started our venture studio to experiment with new product concepts, leading to new opportunities for Synervoz and its co-development partners.
Our lab to experiment with new ideas, cutting-edge tech, and build new prototypes and POCs.
[Get in Touch](/contact)

Social media broke human connection. But AI offers a fix—by transforming passive content feeds into meaningful real time experiences with friends.
* Imagine a voice assistant wired into all your devices — one that can talk to your friends and bring you together spantaneously the moment you're both free. Suddenly, you're hanging out more, watching shows together, syncing up your speakers for shared music sessions — not just doomscrolling solo.
* At Synervoz, we’re at the forefront of this shift. Our Switchboard SDK empowers developers reinventing real time interaction with cutting edge AI tools.
* Our SDK is our unfair advantage — we move 10x faster, testing wild ideas before others even spot the trend. The Venture Studio is our playground for the future.
We welcome co-development partners on any of the projects you see here.
An immersive 3D virtual office platform with spatial voice communication, video, screen sharing, music, and more. Unity project with a browser first design. Can be customized for your project.
A growing social entertainment hub where users can watch TV shows, movies, play games, music, apps and chat together.
An app that lets you communicate in a foreign language without the help of a dictionary or interpreter.
[Partner with us ➜](/contact)
A voice-enabled app where you can ask questions naturally and receive responses from a language model in real time.
An app for testing a new drop-in voice communication paradigm. Built on top of the Switchboard SDK, opportunities abound for extending upon this MVP.
Discover our series of short videos that dive into the functionality of the first Switchboard app and the cutting-edge audio tech that sparked its creation!
A unique VoIP communications project with various POCs that’s ready to be embedded in headphones, speakers, and ported to other new form factors.
Before Amazon’s "Drop-in" existed, we built a prototype where we used Echo to control connectivity and key-bind shortcuts to activate the intercom.
As daily Slack users, we see an opportunity to bring remote teams closer together. We've experimented with new channel types and prototypes, integrating innovative audio features and social activities.
Explore the magic of our SDK with a curated lineup of interactive examples, and discover the possibilities!
All rights reserved, see [Patents](/patents).
---
# Buddy Speakers and Headphones
> Unlock shared audio with Buddy Speakers & Headphones. Enjoy music while watching videos and calls together, using voice control, ducking, and VoIP.
Bringing Switchboard to more platforms.

### True cross-platform
The Switchboard user experience is great on mobile phones and laptops. But there are limitations.
By building Switchboard into hardware, limitations are overcome and the user experience extends to use cases and devices where they make the most sense:
* Watch parties on the TV in your living room
* Drop-in audio on your smart speakers
* Hands-free experiences with headphones that aren’t limited by Bluetooth issues

A source separation approach for 2+ people to share media while still being able to talk through their headphones.

[Play](https://youtube.com/watch?v=XeaxksRPtO4)
Demo shown uses the Switchboard 1.0 app.
### Speakers become social devices
Whether it’s listening to music or watching TV together (in a watch party), or playing games together, integrated VoIP functionality turns smart speakers into social devices.
When coupled with a companion app that cleverly integrates features like presence detection, connecting and synchronizing media like Spotify and Netflix, as well as positional audio to make it feel like you’re in the same room together, Buddy Speaker and Headphones take Switchboard to the next level.


### Interested in a partnership or co‑development?
If you’re looking to collaborate or need help with a similar project, we’d love to connect.
[Partner with us ➜](/contact)
[](/contact)
< [Back to Venture Studio](/venture-studio/)
All rights reserved, see [Patents](/patents).
---
# Conversational LLMs
> Advancing real-time conversational AI solutions. Our conversational LLM powers advanced AI agents designed for customer service, language translation, and social or entertainment applications. Combining cutting-edge technology with tailored implementation, it delivers intelligent, adaptable solutions for every use case.
Advancing real-time conversational AI solutions.
### Smarter AI for every interaction
Our conversational LLM powers advanced AI agents designed for customer service, language translation, and social or entertainment applications. Combining cutting-edge technology with tailored implementation, it delivers intelligent, adaptable solutions for every use case.
[Try it out](https://llm.synervoz.com/)
[](https://llm.synervoz.com/)
See how our expertise and tools, including our flagship Switchboard SDK, can help you create intelligent, natural, and adaptable AI agents.
[Play](https://youtube.com/watch?v=SvfG45KIlfM)
[Play](https://youtube.com/watch?v=TeUxbal67po)
[Play](https://youtube.com/watch?v=Dl4SHFgn4ak)
[Try it out](https://llm.synervoz.com/)
### Interested in a partnership or co‑development?
If you’re looking to collaborate or need help with a similar project, we’d love to connect.
[Partner with us ➜](/contact)
[](/contact)
< [Back to Venture Studio](/venture-studio/)
---
# Instant Intercom
> Explore the Synervoz Instant Intercom project: high-speed, drop-in audio communication using Flic buttons, voice commands (Alexa), and keybind shortcuts. We’ve experimented with different mechanisms that make it extremely fast to reach your teammate, friend, or whomever.
“James, get me those TPS reports.”
Each button is tied to a specific person. You could tap to drop in for a real time audio call, or press and hold to leave a voice message
Commands which could be through your phone, or Alexa-powered devices.
This shows how frictionless it is to respond when someone starts talking to you.
Keybind shortcuts if you’re using Switchboard on your laptop (we also had Slack shortcuts).
For example a bracelet or phone feature that recognizes specific gestures you make with your hand.
### Interested in a partnership or co‑development?
If you’re looking to collaborate or need help with a similar project, we’d love to connect.
[Partner with us ➜](/contact)
[](/contact)
< [Back to Venture Studio](/venture-studio/)
---
# Kosmi
> Kosmi is a fully functional, responsive web app that centralizes TV, movies, games, music, and other apps. Enjoy features like Voice Chat, Video Chat, Watch Parties, and Gaming all in one social entertainment hub.
A social hub with a passionate community of over 200K MAUs who come together to enjoy all things entertainment.

### Real time voice and video
Kosmi is a fully functional platform and responsive web app that brings together TV, movies, games, music, and other apps, all in one place. Features include:
* Voice Chat
* Video Chat
* Watch Parties
* Gaming
* Other Activities

[Play](https://youtube.com/watch?v=OBxsBBKoWcs)
[Learn More @kosmi.io](https://kosmi.io)
### White label
Launch a lightly customized version of Kosmi on your domain for your community, such as:
* Entertainment hub for employees
* Events companies
* Film festivals
* Dating apps

### Custom
Use Kosmi’s technology to power a multiplayer experience in your product:
* For startups & technology companies
* For streaming services and other content owners

[Learn More @kosmi.business](https://www.kosmi.business)

Kosmi is an independent entity and Synervoz is a shareholder.
### Interested in a partnership or co‑development?
If you’re looking to collaborate or need help with a similar project, we’d love to connect.
[Partner with us ➜](/contact)
[](/contact)
< [Back to Venture Studio](/venture-studio/)
---
# LanguageBuddy
> Install LanguageBuddy for AI-based, real-time language translation in any virtual meeting, including Zoom, Teams, Slack and Meet.
AI based real time language translation for any virtual meeting software.


For two-person calls, only one person needs to install LanguageBuddy. One person can translate both inbound and outbound audio.
[Play](https://youtube.com/watch?v=4YlVPJc0rRk)
LanguageBuddy can also include a practice mode where users can chat with an AI / LLM and learn other languages in a conversational setting. 
LanguageBuddy can be connected to different third-party AI models. For example, Google’s Cloud Translation API works well for casual conversations, but perhaps you have your own model specifically trained on medical or legal terminology. Or perhaps you are interested in connecting it to one of the many popular open-source Large Language Models.

LanguageBuddy is a virtual audio device that can be customized for other use cases as well. Think of it as a transformer that can capture your microphone and transform its output in any way you desire, such as removing noise, applying a voice changer, or adding effects, before routing it into any application that requires a microphone input—from meetings and podcast recordings to voice and video messages, in-game voice chat, and more.

### Interested in a partnership or co‑development?
If you’re looking to collaborate or need help with a similar project, we’d love to connect.
[Partner with us ➜](/contact)
[](/contact)
< [Back to Venture Studio](/venture-studio/)
---
# Ronday
> Our metaverse platform unlocks connection, collaboration, & productivity in shared 3D spaces. Build virtual venues—from concert halls & theatres to meeting rooms & arcades.
Our metaverse building platform enables connection, collaboration, and productivity in shared 3D spaces.

[Play](https://youtube.com/watch?v=t9U7wlkVGu0)
Check out more videos on [Ronday’s YouTube page](https://www.youtube.com/@getronday/videos).
### Real time voice and video
Synervoz added an improved audio pipeline to enhance robustness while simultaneously eliminating noise and echo issues. In addition, the VoIP pipeline needed to interface with the 'in-game' audio system (ambient audio for sound effects produced by objects in the 3D space, such as a boombox or TV).

### Spatial audio
Spatial audio is another important component of virtual spaces. We needed to consider not only how to create realistic environment with respect to directional audio, occlusion, reverb, and attenuation, but also how VoIP connections would scale as more participants entered the space.

Synervoz delivered a robust, cross-platform audio pipeline capable of mixing and managing various audio channels at scale, and continues to make improvements to the platform.
With features including multi-user screen sharing, music, and interactive objects that can launch games, watch parties, and other activities, we’re building a platform that’s as immersive as it gets.

Turn it into a 3D / virtual:
* Concert venue
* Movie theatre
* Arcade, casino, or gaming space
* Sports bar
* Meeting, event, or conference space
* Cafe or coworking space
* Creative, recording, or production studio
* Trivia venue
or just about anything else!

### Interested in a partnership or co‑development?
If you’re looking to collaborate or need help with a similar project, we’d love to connect.
[Partner with us ➜](/contact)
[](/contact)
< [Back to Venture Studio](/venture-studio/)
---
# SDK Examples
> The Switchboard SDK is Synervoz’s flagship product. Explore our curated collection of sample apps and demos built with the Switchboard SDK. These examples showcase its capabilities and potential applications, helping you quickly grasp what you can create—with or without additional support from Synervoz.
A collection of our Switchboard SDK sample apps and other demos.
Simplify the process of creating a karaoke app.
Mix tracks, apply effects and sync beats in real-time.
Guitar effect app showcasing Switchboard SDK functionality.
Implement the audio pipeline of a simple online radio app, with easy integration.
This example plays an audio file and ducks the playback volume based on the user's microphone input.
This example adds a reverb effect that simulates the natural reverberation of sound in a physical space.
This example reduces unwanted background noise. It works by muting or eliminating any sound that falls below a given threshold level.
### Interested in a partnership or co‑development?
If you’re looking to collaborate or need help with a similar project, we’d love to connect.
[Partner with us ➜](/contact)
[](/contact)
< [Back to Venture Studio](/venture-studio/)
---
# Slack for X
> Design & build audio prototypes for Slack. Explore instant communication, Switchboard 1.0 app integration, and simultaneous channel monitoring.
A series of prototypes and proof-of-concepts that revolve around Slack and instant communication
[Play](https://youtube.com/watch?v=2ALiM-yokEE)
Users could seamlessly switch between these channels using voice commands, enhancing communication efficiency.
Additionally, users could leave voice messages in the app that would automatically post (both the voice message and its transcript) in the corresponding group's Slack channel.
[Play](https://youtube.com/watch?v=ORsDODqBmFQ)
### Music Channels
We aren’t sure why Slack doesn’t have music channels yet. We first pitched it many years ago, before the Huddles / Chime partnership was inked. And we, among many others we’ve spoken with, think Music channels for Slack would be a killer feature. As would other types of channels where you could watch, play, and create together.

Nevertheless, below is some inspiration. While Spotify would be a killer integration for Slack, it comes with annoyances and limitations given not everyone has Spotify Premium. So, as an MVP, we propose music that everyone would have access to right away.
Radio has advantages in this regard. AI Generated music opens up more possibilities here -- some ethical / legitimate, others perhaps less so.
Users would start by selecting a category for their audio channel.
Users could communicate in real time while listening to a synced playlist on Spotify or other music app.
Users could communicate in real time casually or in meetings with designated speakers/presenters.
### Watch Party & Game Channels
Discord is moving in an inspiring direction, but it is constrained from making major design changes that would alienate its existing user base. As such, it’s hard to make an app that’s purpose designed around specific use cases.
We see an opportunity for content owners to build their own platforms for watching, playing, or experiencing that content together.
E.g. “Slack for Sports” is illustrated here.

### Interested in a partnership or co‑development?
If you’re looking to collaborate or need help with a similar project, we’d love to connect.
[Partner with us ➜](/contact)
[](/contact)
< [Back to Venture Studio](/venture-studio/)
---
# Switchboard 1.0
> Switchboard 1.0 was the feature-rich app (built between 2015-18) that inspired Synervoz's founding. It showcased our vision for a new communication paradigm, but its complexity (multiple real-time audio features, cross-platform) led us to develop the Switchboard SDK—our current focus.
A chat platform where people can communicate instantaneously.
### Background
Switchboard 1.0 was the feature-rich app (built between 2015-18) that inspired Synervoz's founding. It showcased our vision for a new communication paradigm, but its complexity (multiple real-time audio features, cross-platform) led us to develop the Switchboard SDK—our current focus.
While the Switchboard 1.0 app is no longer active, if it piques your interest, we can revive a simplified version (starting with [Switchboard Lite](/venture-studio/switchboard-lite)) upon request. The videos below demonstrate key features, all available in our current Switchboard SDK for easy integration into new applications.

An introduction to Switchboard and how users can communicate on the app.
An introduction to Switchboard and basic intercom functionality.
A demo of how silencing and switching off work on Switchboard.
Voice control of Switchboard.
How to send asynchronous voice messages including a cool Slack integration.
This shows how to quickly onboard your whole Slack team to Switchboard.
Here is one of many cool things you can do with Switchboard's Slack integration.
This shows how frictionless it is to respond when someone starts talking to you.
We walk you through an older version of the interface, illustrating some key features. Experience has been improved, but this gives you the idea!
This shows a few of the many ways you can use Switchboard's tech.
We programmed a flic button to really turn your phone into an intercom.
Listen together + talk like you're in the same room.
Web app demo showing sync & ducking while watching video.
This illustrates the Switchboard spontaneous voice chat paradigm in action, as well as some cool audio features at the end.
### Interested in a partnership or co‑development?
If you’re looking to collaborate or need help with a similar project, we’d love to connect.
[Partner with us ➜](/contact)
[](/contact)
< [Back to Venture Studio](/venture-studio/)
All rights reserved, see [Patents](/patents).
---
# Switchboard Lite
> Seamlessly blend social audio with sound tech using Switchboard Lite. Features include intercom, music ducking, and synchronized listening. Built on top of the Switchboard SDK.
Where social audio meets sound technology.

Switchboard Lite is a simplified reincarnation of the original Switchboard (1.0) app.
Years ago, Synervoz changed its focus from building the Switchboard app to building the Switchboard SDK and other developer tools.
The Switchboard Lite app is built on top of the Switchboard SDK and is an example of the types of products that are much easier to build with our SDK.

[Play](https://youtube.com/watch?v=CxZ7lri6CAw)
Note: All features mentioned exist in the Switchboard SDK. The current Switchboard Lite app has a subset of these features as described below.
### Music + intercom
The core aspects of Switchboard were the Intercom, and the Music.
The intercom allows for drop-in audio chat. So, if your friend is sitting there listening to music, you can just “drop in” on them and start talking. The music “ducks” (reduces in volume) automatically when someone speaks (voice detection).
The music is currently provided by Dash Radio. Because of this, it’s synchronized by default if you’re on the same station as your friend. And nobody needs to log in or authenticate with Spotify Premium.
The original version of Switchboard also had Spotify integration, hands-free voice commands, and many other features. All of these are still available if desired.


Some of the apps and use cases we’ve considered include:
* Remote Work
* Running, Cycling, Motorcycling
* Fitness, Skiing & Outdoor Activities
* Listen Parties & other social use cases

We’re excited to partner and bring these use cases to life faster than anyone else can. Learn more about the original version of Switchboard 1.0, featuring bite-sized demo videos.
[Explore Switchboard 1.0](/venture-studio/switchboard-1-0)
We encourage developers and partners to get in touch to discuss customizations and co-development opportunities.

Explore the Switchboard Lite app for yourself.
[](https://apps.apple.com/us/app/switchboard/id1224681642?platform=iphone)
[](https://play.google.com/store/apps/details?id=com.synervoz.switchboard)
### Interested in a partnership or co‑development?
If you’re looking to collaborate or need help with a similar project, we’d love to connect.
[Partner with us ➜](/contact)
[](/contact)
< [Back to Venture Studio](/venture-studio/)
All rights reserved, see [Patents](/patents).
---
# White Label
> We offer white label solutions for rapid design, prototyping and testing, as well as customized options using our SDK and support services.
Get to market faster. Save time and money by starting with our existing tools.
[Get started](/contact)

We offer white label solutions for rapid design, prototyping and testing, as well as customized options using our SDK and support services.
### Save time and money
Why reinvent the wheel when you don’t have to. We have spent years building and testing our own products. That’s a code base you can leverage in more ways than one.
Whether we make a copy of a whole product and make a few minor tweaks or instead help you assemble a brand new product using several of our building blocks, we can likely save you a lot of time and money in comparison to building everything from scratch.


[Get started](/contact)
### Audio and other apps
We’ve built numerous audio apps. Some of these are open source and available on the [Examples Page](https://docs.switchboard.audio/docs/examples) of our Switchboard SDK.
We can also leverage any of our [Venture Studio](/venture-studio/) projects to get you to market faster and cheaper.

### Social and Metaverse apps
We have battle-hardened apps that can be used as templates for other apps that require a lot of the same functionality. A few examples include:
* Switchboard 1.0 or [Switchboard Lite](/venture-studio/switchboard-lite)
* [Ronday](/venture-studio/ronday-vs)
* [Kosmi](/venture-studio/kosmi-vs)
These can all be customized, white labelled, or leveraged in another form of creative partnership. Let us know what you’re building, and we’ll let you know how we can help.

### Audio engines
Time and time again we’ve watched customers fall into the trap of building custom audio engines to circumvent the limitations provided by open source alternatives.
Get to market faster and cheaper by leveraging what you need from [Switchboard](https://switchboard.audio) SDK. Apart from leveraging Switchboard as an SDK, we offer partial source code licenses and can leverage modules as-needed for your project.
Switchboard creates and manages VoIP connections, music, real time effects, auto-ducking and so much more. You don’t have to build a new cross platform engine from scratch!

### SDK modules
Bose PinPoint, Amazon IVS, Voicemod, Agora, Superpowered, AudioShake to name a few.
Our Switchboard SDK has over 25 extensions and the library continues to grow, including both open source and commercial modules for pretty much anything that touches audio. If you need help creating, implementing, or comparing audio modules, we can help.

### Reduce cost and time to market (TTM)
Any of our services can be integrated into solutions that use our SDK and/or pre-existing source code. This can help reduce hours and TTM.
[Let's talk ➜](/contact)
[](/contact)
---
# Specialized engineers. Elastic capacity. Proprietary tooling.
> Synervoz combines senior engineers with years of developer tooling and deep specialization in real-time audio, embedded systems, mobile, and AI — helping internal teams prototype, productionize, and ship new capabilities faster.
[](/_astro/w-s-hero.6d8497e4.mp4)
Synervoz combines senior engineers with years of proprietary developer tooling and deep specialization in real-time audio, voice, mobile, embedded systems, and AI.
We help you prototype, productionize, and ship new capabilities faster.
[Talk to our team ](https://synervoz.com/contact)
## You can't staff for every technology shift
Keep Headcount Flexible
Engineering teams need to move faster without permanently increasing headcount.
Expertise Across the Full Stack
Product development now spans embedded systems, mobile, real-time audio, ML, cloud AI, and on-device AI.
Bring in Specialized Engineering Talent
Synervoz provides flexible access to small, senior teams with deep expertise across these technologies.
Scale Up, Transfer Knowledge, Move On
Plug in when needed, accelerate initiatives, transfer knowledge, then ramp down or shift to the next priority.
Add capability without adding headcount
Embedded
Mobile
Real-time Audio
ML
Cloud AI
On-device AI
## Build vs. buy is the wrong question
You don't have to choose between building every capability internally and handing the problem to an outside consultancy. Blend specialized external capability into your existing team.
### Build
Internal team does everything. Full control, but limited by the expertise and bandwidth you have today. Hiring for every emerging competency isn't sustainable.
### Buy
External team owns the problem. Faster to start, but your team doesn't grow. When the engagement ends, the capability leaves with it.
Recommended
### Blend
Synervoz specialists and technology augment the internal team, accelerate the work, and transfer capability back. Your team retains ownership and grows stronger.
Augment Prototype Productionize Transfer
[Talk to Synervoz ](https://synervoz.com/contact)
## Not a typical consulting team
### Technology + People
We've spent years building developer tooling specifically for real-time audio and increasingly on-device AI. We bring that technology into engagements alongside our engineers, so we're not always starting from scratch.
### Specialists, Not Generalists
Our engineers work across disciplines that don't usually sit in one team. That combination lets us solve problems that cross traditional engineering boundaries.
Real-time audio Embedded DSP Mobile On-device ML Cloud AI
### Prototype to Production
We don't just build demos. Our experience building production products and developer tooling helps us rapidly validate new ideas — and then turn the ones that work into technology that can actually ship.
## Not every problem needs another cloud API call
Cloud AI is incredibly powerful, but at scale it can introduce latency, token and inference costs, connectivity dependencies, and privacy concerns. Synervoz specializes in hybrid architectures that combine cloud models with on-device intelligence.
#### On Device
DSP
Noise / Echo Suppression
VAD
Turn-Taking
Classification
STT / TTS
Smaller Models
Escalate
#### Cloud
Large Language Models
Complex Reasoning
Knowledge Retrieval
Lower latency
Lower inference cost
Better privacy
Greater reliability
## What's the capability you need next?
You don't need to build every emerging competency internally. Bring us the problem. We'll bring specialized engineers, technology, and experience to help your team get there faster — and leave your organization stronger when we're done.
[Talk to Synervoz ](https://synervoz.com/contact)